
LLM
-
Apple’s on-device Apple Intelligence foundation model explained
Apple Intelligence utilizes a hybrid architecture featuring a 20B parameter model and 3 billion parameter components to balance privacy and power. The…
-
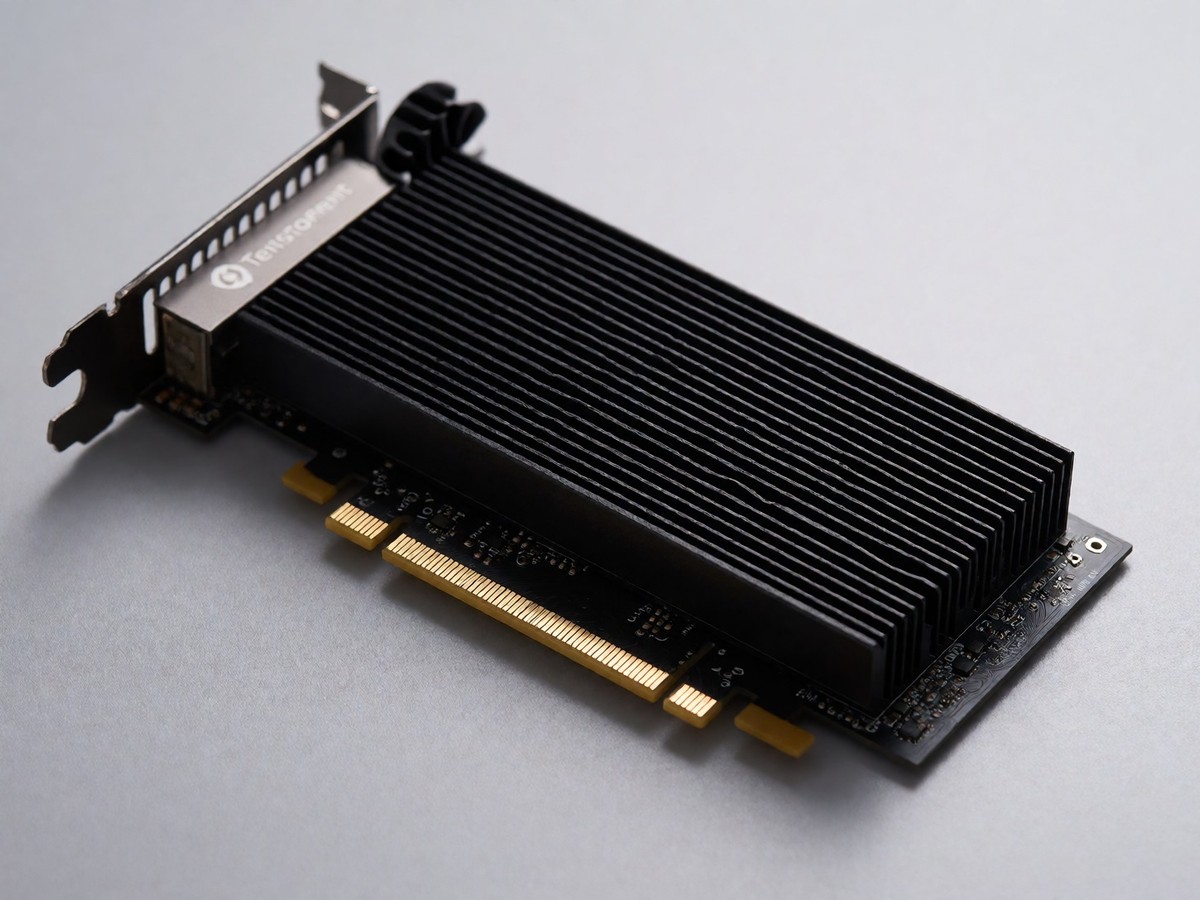
Getting Started with Tenstorrent Wormhole n150
The Tenstorrent Wormhole n150 PCIe card uses the tt CLI to manage drivers and the TT-Metalium SDK. It supports serving LLMs via…
-
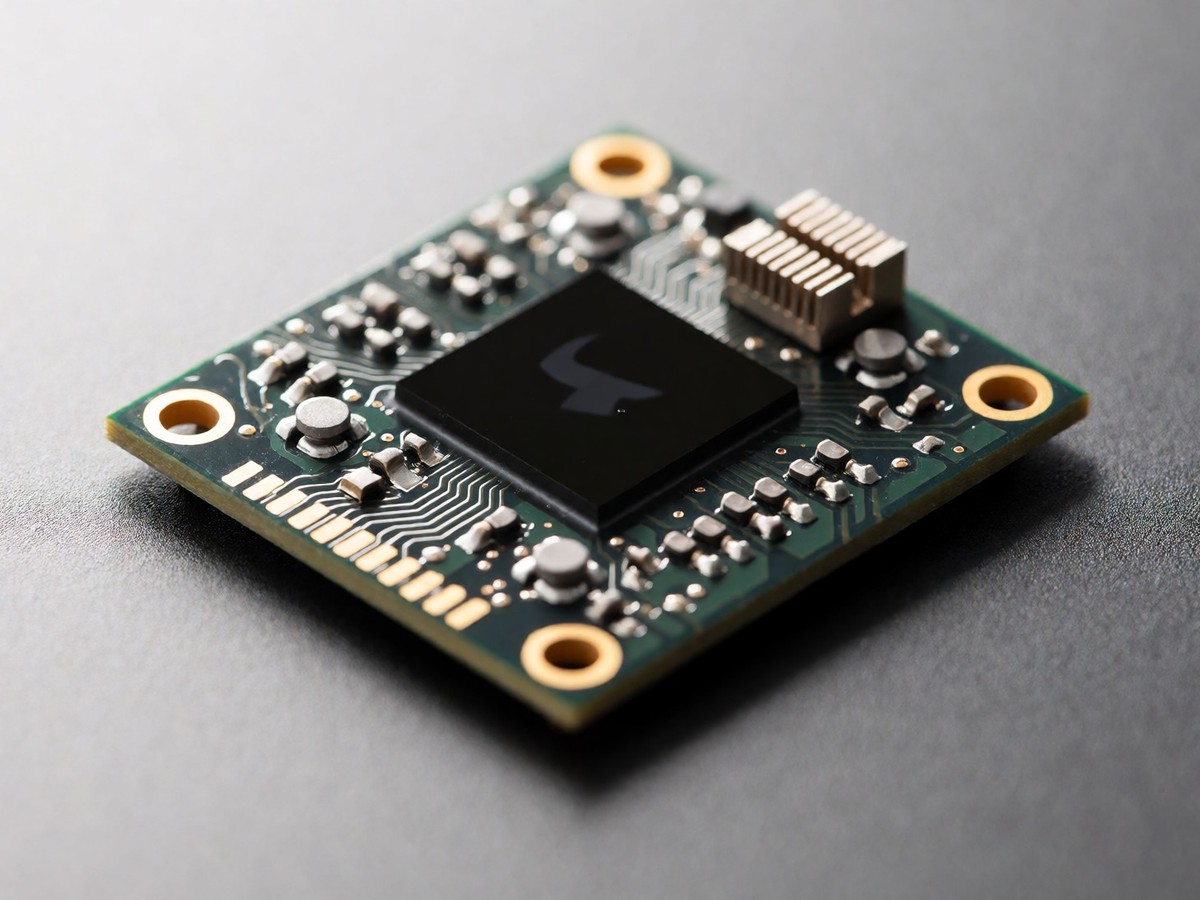
Hailo-10 hardware performance and GenAI acceleration
The Hailo-10 GenAI accelerator delivers 40 TOPS of performance while running Llama2-7B at 10 tokens per second within a 5-watt power envelope.…
-
Moonshot AI Kimi model updates and API pricing details
Moonshot AI released the K2.6 model featuring an agent cluster architecture that supports 300 sub-agents working in parallel. The company also announced…
-
How DeepSeek’s $14B V3 model changes LLM cost efficiency
DeepSeek-V3 training required only 2.788 million H800 GPU-hours costing $5.576 million, shifting the cost curve for enterprise AI. This efficiency impacts cloud…
-
Scale AI’s defense pivot and Donovan LLM deployment
Scale AI has signed a $100 million enterprise agreement with the Department of Defense to deploy Scale Donovan, the first large language…
-
Trends in Sam Altman’s $500B Stargate Project and GPT-6 deployment
OpenAI’s GPT-6 deployment introduces tiered intelligence with GPT-6 Astra achieving a 32% higher average score than GPT-5.6 Sol. The rollout includes cost-efficient…
-
Memory Exhaustion and Communication Bottlenecks in Llama 3.1 405B
Llama 3.1 405B requires 810 GB of memory for FP16 precision, necessitating distribution across multiple SambaNova SN40L RDUs. Improper sharding in feedforward…
-
Wasted Infinity Fabric bandwidth in Mixtral 8x22B clusters
Engineers often stall Mixtral 8x22B performance by ignoring ROCm 7 kernel optimizations and incorrect NUMA modes. Proper configuration of AITER kernels and…
-
Llama 4 deployment priorities for local inference
Meta’s Llama 4 models offer efficient local enterprise deployment through mixture-of-experts architectures. Llama 4 Maverick outperforms GPT-4o and Gemini 2.0 Flash on…
-
Deploying Mistral AI Codestral 22B on Azure AI Foundry
Azure AI Foundry provides Serverless API and managed compute paths for deploying Mistral AI’s Codestral 22B. This 22B parameter model achieves an…
-
The Cerebras CS-3 delivers 2,500 tokens per second for Llama 4 Maverick
Cerebras CS-3 delivers Llama 4 Maverick inference at 2,500 tokens per second per user, significantly outperforming the NVIDIA DGX B200. The WSE-3…