Kernel communication failures
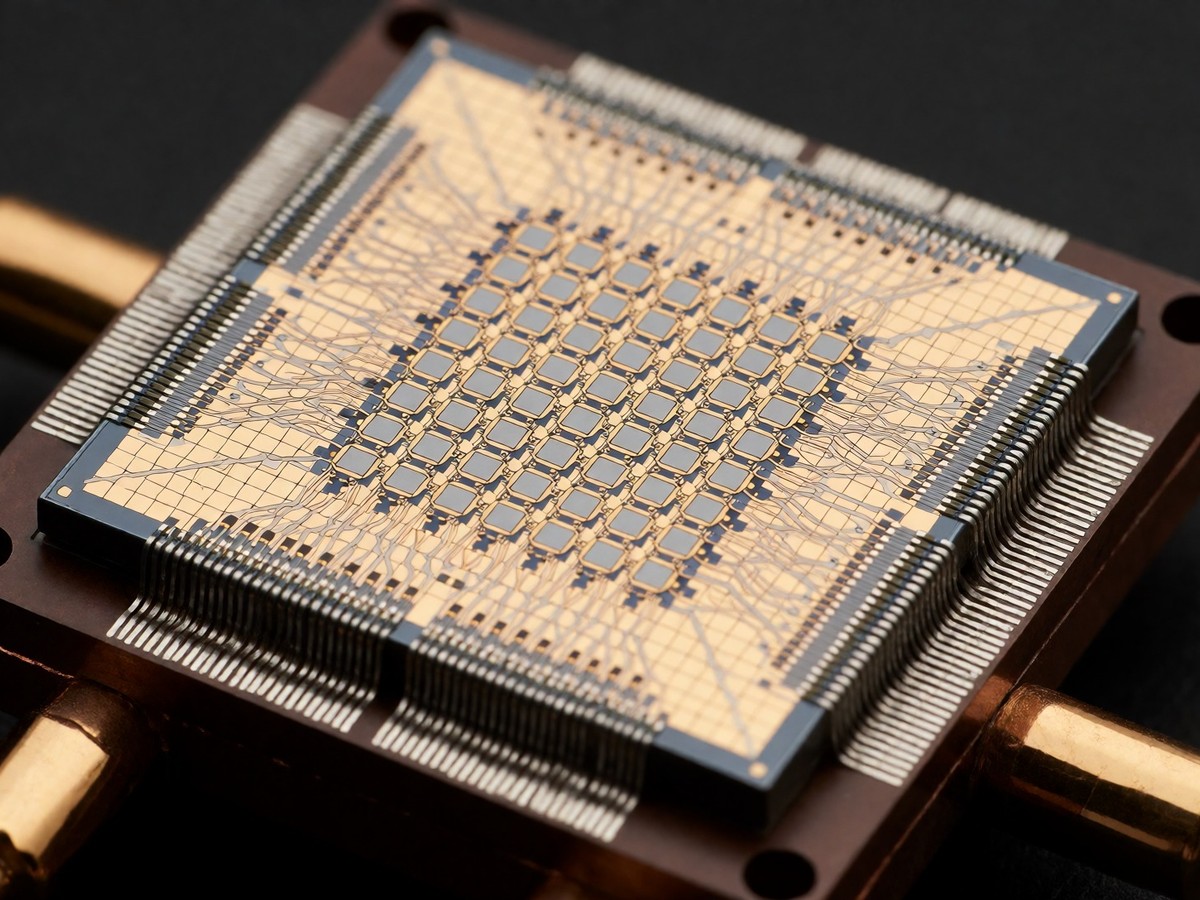
I see engineers stalling Mixtral 8x22B performance by ignoring ROCm 7 kernel optimizations. This model uses 44 billion active parameters per forward pass. If engineers fail to utilize the AITER kernels for MoE and MLA fusion, they prevent the MI350X from reaching the high throughput levels required to serve the 44 billion active parameters of the Mixtral 8x22B model in production. These kernels integrate directly into vLLM to improve MoE performance. You should also set the environment variable NCCL_MIN_NCHANNELS to 112 to increase the number of channels. Set HIP_FORCE_DEV_KERNARG to 1 to help vLLM performance. I also suggest you set TORCH_BLAS_PREFER_HIPBLASLT to 1. This ensures the system uses hipBLASLt for better results. To fully utilize the architecture, you can set PYTORCH_TUNABLEOP_ENABLED to 1 and PYTORCH_TUNABLEOP_VERBOSE to 1. The seven 4th Generation Infinity Fabric links provide 1,075GB/s of peak bandwidth. The Infinity Fabric AP link connects the two IO dies with 5.5TB/s of bidirectional bandwidth, which is essential for multi-GPU scaling. If you do not configure tensor parallelism via the tensor-parallel-size parameter in vLLM, you waste this interconnect speed. Each of the eight XCDs has 32 CDNA 4-based Compute Units. This results in a total of 256 CUs and 1,024 matrix engines per accelerator. The system supports new FP4 and FP6 data types. The CDNA 4 architecture re-architected the matrix engine to natively accelerate FP6 at twice the throughput of FP8. This speed matches the FP4 throughput.
Memory and NUMA bottlenecks
Incorrect memory partitioning often limits the 8.0TB/s peak bandwidth of the HBM3e. The MI350X allows for two NUMA per socket modes: NPS1 or NPS2. If you choose the wrong mode, you create bottlenecks when the 256 Compute Units attempt to access the 288GB of HBM3e. The architecture places eight XCDs atop dual IO dies. These IO dies use a 6nm process and manage the 128 channel HBM3e interface. If you do not tune the gpu_memory_utilization parameter, you risk leaving headroom on the table. Set this value higher than 0.9 to increase throughput. You must watch for HIP or CUDA Out Of Memory errors when you do this. The 256MB of Infinity Cache and the 128 channel HBM3e interface require precise management. The compute chiplets use a 3nm N3P process. These chiplets sit on top of the IO dies. The memory operates at 8Gbps. The 128 channel HBM3e interface provides the necessary bandwidth to keep the 1,024 matrix engines fed. This is vital when the Mixtral 8x22B model relies on its 176 billion total parameters. The MI350 series claims a 35x generational leap in inferencing performance. It also aims for a 30x boost in energy efficiency. Why does the NPS2 configuration still struggle with latency in these specific clusters?
| Component | MI350X Specification |
|---|---|
| VRAM Capacity | 288GB HBM3e |
| Memory Bandwidth | 8.0TB/s |
| Infinity Fabric Links | 7 (4th Gen) |
| Peak Link Bandwidth | 1,075GB/s |
| Compute Units | 256 |
| Matrix Engines | 1,024 |
| TDP | 1,000W |
Rack density and context pressure
The MI350X AC deployment packs 64 GPUs per rack using 4U chassis. Each chassis contains 8 accelerators. This setup provides double the density of typical 10U configurations. The MI350X has a 1,000W TDP. This 1,000W TDP is a heavy burden for existing air-cooled data centers. The Mixtral 8x22B model uses a 65,000-token context window. This large window puts massive pressure on the 288GB of HBM3e. Because the model has a total parameter size of 176 billion, the 288GB capacity is essential. I recommend you use PyTorch TunableOp to automate parameter adjustment. Set PYTORCH_TUNABLEOP_ENABLED to 1 to help the system find the best settings for your workload. The MI350X utilizes the CDNA 4 architecture. It also uses the latest 3nm process for its compute chiplets. The MI350X AC allows 8 GPUs in a 6U chassis, while NVIDIA uses a 10U configuration for 8 GPUs. This means AMD fits 64 GPUs per rack versus 32 for NVIDIA. The Mixtral 8x22B uses a sparse Mixture-of-Experts architecture. This architecture only requires about 44 billion active parameters per forward pass. However, the total parameter size reaches 176 billion. This discrepancy means the system must move huge amounts of data across the Infinity Fabric to access the necessary experts. The 288GB of HBM3e capacity per GPU allows for larger context windows without excessive tensor parallelism. This 288GB of HBM3e capacity is 50% higher than the 192GB found in the NVIDIA B200.