High-density infrastructure and NVIDIA clusters
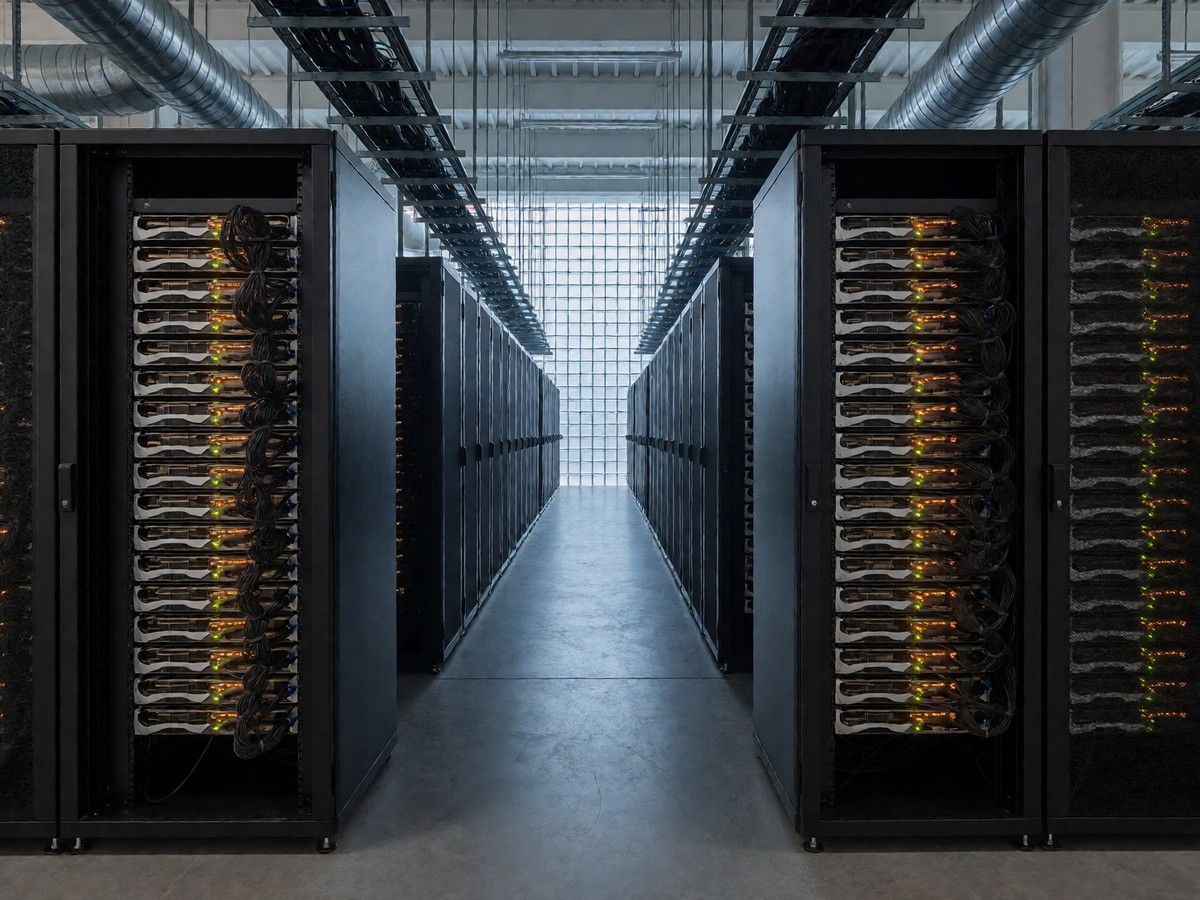
Lambda builds modular AI factories that incorporate high-density power, liquid cooling, and high-bandwidth interconnects to support labs training and deploying the next generation of superintelligence. These systems rely on single-tenant NVIDIA GB300 NVL72 clusters using NVIDIA Quantum-2 InfiniBand to provide security and performance. This shared-nothing architecture offers hardware-level isolation to protect sensitive data and ensures production-grade compliance via SOC 2 Type II certification. Users spin up HGX B200 and H100 instances in minutes to facilitate rapid testing and prototyping. These production-ready NVIDIA HGX B200 and H100 GPU clusters optimize distributed AI workloads for training foundation models and serving billions of tokens. The infrastructure supports mission-critical workloads for hyperscalers building global AI infrastructure, enterprises in regulated industries, and frontier labs building trillion-parameter foundation models. Lambda provides managed clusters and co-engineering from a team that builds infrastructure for the largest AI labs. The company handles the full lifecycle of AI workloads, from training to deployment. You can scale from one GPU to hundreds of thousands of GPUs to meet your specific workload demands.
AI factory mission and scale
ML engineers founded Lambda in 2012 in San Francisco, starting in the Noisebridge anarchist hackerspace in the Mission District. The company grew from an under-the-desk hustle into a pursuit of AI factories at gigawatt scale. One hundred percent of the engineering, operations, and support staff dedicate their work to AI workloads and infrastructure. The leadership combines deep machine learning experience with decades of experience building and scaling global infrastructure. The company aims to make compute as ubiquitous as electricity and provide everyone in America with the power of superintelligence through infrastructure that supports AI services used by hundreds of millions of people. Lambda builds tools for teams pushing the frontier of superintelligence. They prioritize customer success by working backward from the customer experience to determine which technology they must invent. The team operates with a "One Team" mentality, recognizing that personal interest serves the interest of the customer and company first. They follow a "Do-ocracy" principle where employees take action to get things done. They also encourage employees to write down their thoughts in one or two-page documents to communicate through time and space. They ask questions such as whether their work will delight the customer and how the customer defines success. They seek to build products that help customers achieve success. They also promote a culture where employees ask: "Does the customer care about this work?" Does the massive scale of their gigawatt-scale AI factories meet the requirements for future superintelligence?
Organizational principles and deployment
Lambda provides dedicated, single-tenant infrastructure to train foundation models. The company provides scale from one GPU to hundreds of thousands of GPUs to support the goal of "One Person, One GPU." This capability supports frontier labs and enterprises. The company emphasizes "Real recognize real" to attract great people who want to work with other great people. Lambda maintains a "no politics, no crypto" environment to avoid holy wars at work. They focus on outcomes rather than titles and value anonymous feedback. The organization follows the principle to make decisions quickly and execute quickly, recognizing that reversible decisions allow for faster action. They also prioritize the idea that every problem is a people problem and every solution is a people solution. They also advocate for being excellent to each other.
| Feature | Specification |
|---|---|
| GPU Clusters | NVIDIA HGX B200 and H100 |
| Primary Cluster | NVIDIA GB300 NVL72 |
| Networking | NVIDIA Quantum-2 InfiniBand |
| Security | SOC 2 Type II |
| Architecture | Single-tenant, shared-nothing |
| Scaling | One GPU to hundreds of thousands |
Lambda provides managed clusters and co-engineering from a team that builds infrastructure for the largest AI labs. They focus on the idea that every problem is a people problem and every solution is a people solution. While they provide advanced solutions for AI workloads, the company’s specialization in AI means they lack the breadth of services found in more generalist cloud providers.