
NVIDIA
-
Groq Inference Economics vs NVIDIA H100 Cloud Pricing
Groq LPUs deliver 300 tokens per second using on-chip SRAM, making them 10x more energy-efficient than GPUs. While Groq costs $0.59 per…
-
People shaping Groq’s tensor streaming architecture for real-time AI inference
Jonathan Ross and Douglas Wightman founded Groq to build deterministic chips for fast AI inference. After a $20 billion Nvidia licensing deal,…
-
Blackwell vs. MI350: The Hyperscale Adoption Split
NVIDIA Blackwell drives 70% of data center revenue, but AMD MI350 offers 288GB memory and 40% lower costs. The market splits between…
-
Lambda Labs GPU cloud and NVIDIA H100 clusters
Lambda Labs provides high-density AI infrastructure featuring NVIDIA GB300 NVL72 clusters and H100 instances. These single-tenant systems support mission-critical workloads for frontier…
-
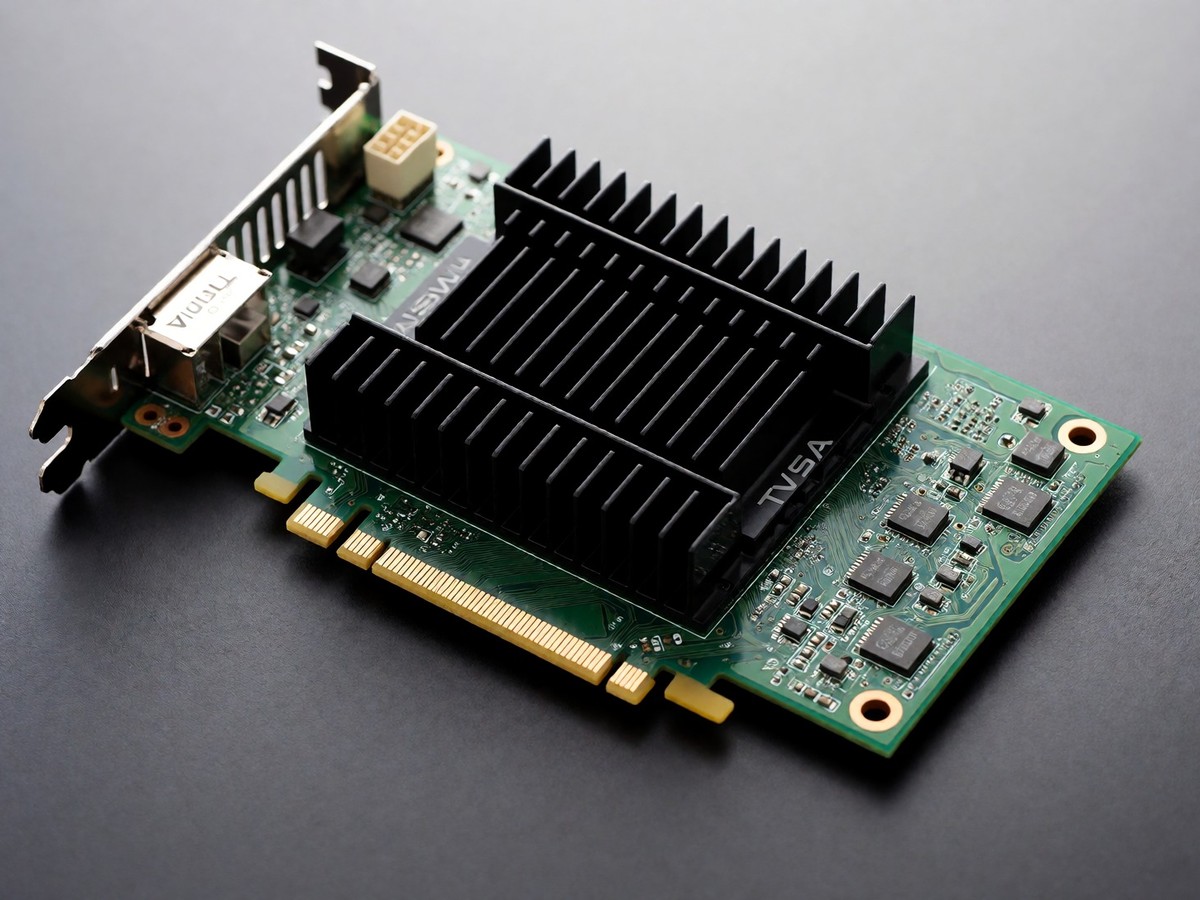
NVIDIA’s journey from Tesla K20 to Blackwell B200 dominance
NVIDIA’s software moat built on CUDA and early Kepler architecture paved the way for the Blackwell B200, which delivers 20 petaflops of…
-
Etched Sohu vs NVIDIA Blackwell performance comparison
Etched Sohu delivers 500,000 tokens per second on Llama 70B using TSMC 4nm silicon, offering a significant throughput advantage over NVIDIA H100…
-
The Groq LPU vs NVIDIA H200 in Enterprise Inference
Groq scales its LPU architecture using Samsung 4nm production with yields exceeding 80 percent to compete against NVIDIA H200 performance. While NVIDIA…
-
The 2012 ImageNet breakthrough and the legacy of Geoffrey Hinton
Geoffrey Hinton and his team achieved a massive victory in the 2012 ImageNet challenge using AlexNet, a deep convolutional neural network. This…
-

D-Matrix Corsair chip delivers 10x faster inference than NVIDIA
D-Matrix began shipping its Corsair digital in-memory compute hardware to hyperscalers and AI labs in June 2026. Led by Sid Sheth, the…
-
The risks of Tesla’s AI chip pivot and Dojo scaling
Tesla is shifting resources from its dedicated Dojo supercomputer team toward a single architecture for AI5 and AI6 processors. This transition occurs…
-

Groq LPU speed advantages for real-time finance
Groq LPU delivers 580 tokens per second for Llama 3.3 70B, significantly outperforming the 90 tokens per second from NVIDIA H100. This…
-
Lightmatter’s Passage platform challenges NVIDIA NVLink dominance
Lightmatter’s Passage platform utilizes 3D-stacked silicon photonics to deliver 114 Tbps aggregate bandwidth. This architecture bypasses copper bottlenecks using the Guide light…
Trending Now
- Groq Inference Economics vs NVIDIA H100 Cloud Pricing
- How Runway’s Gen-4 Turbo is changing fashion campaign production workflows
- Why Synthesia’s AI avatar platform matters now for enterprise training
- Why Hugging Face’s open model ecosystem matters for Meta Llama fine-tuning
- People shaping Groq’s tensor streaming architecture for real-time AI inference