
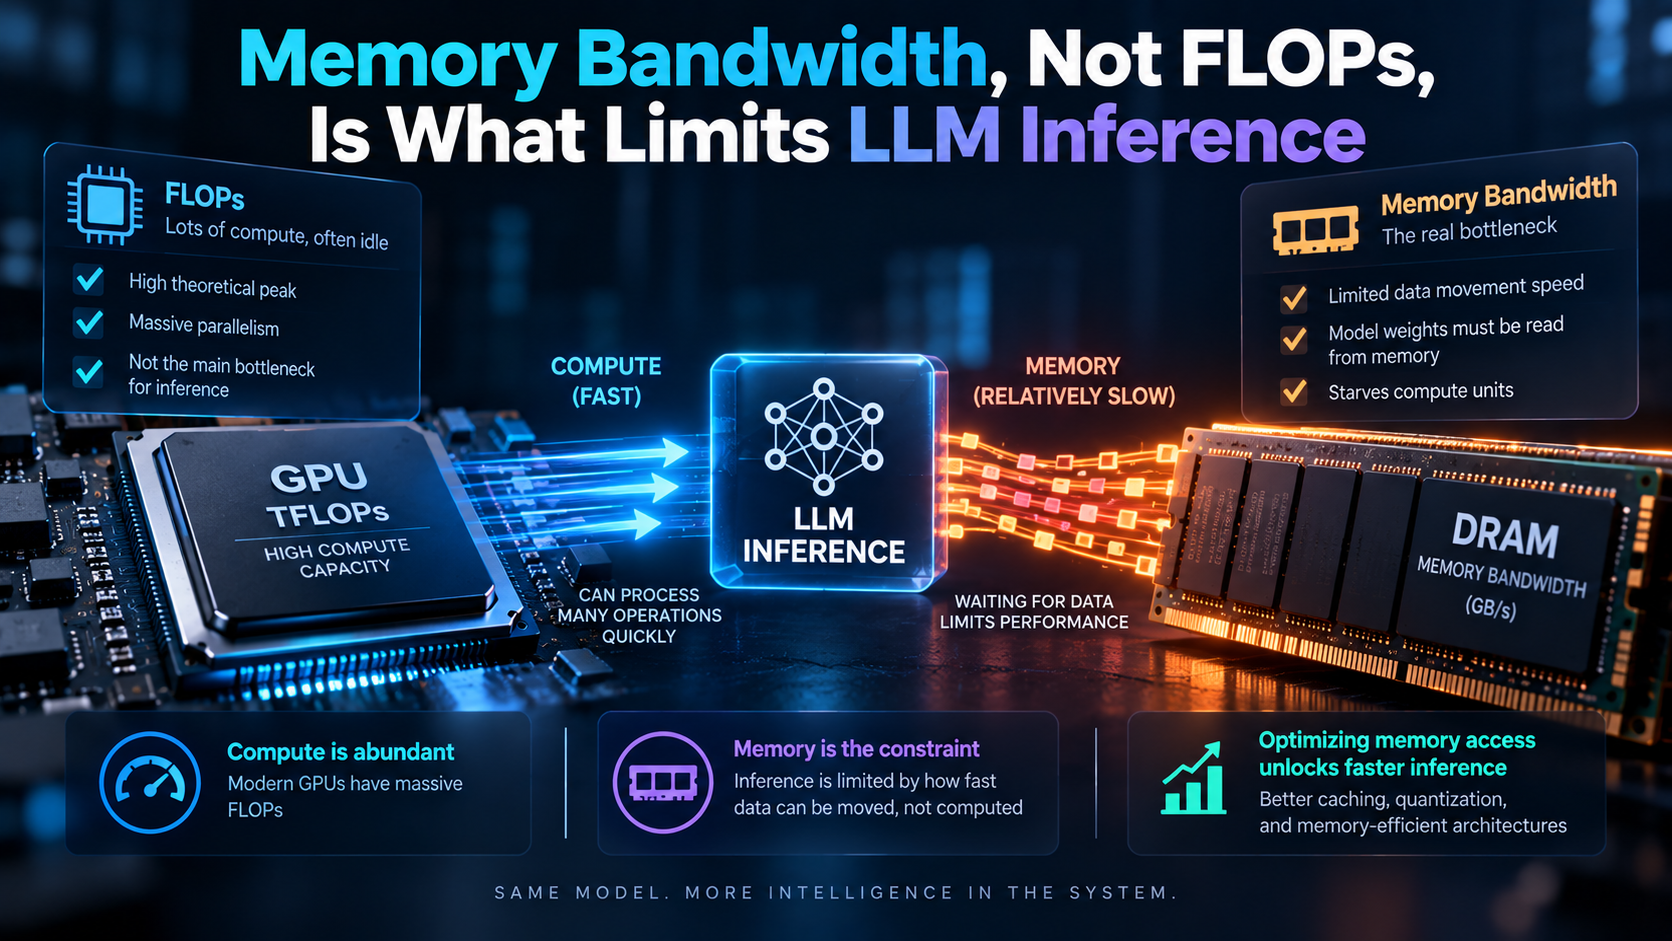
Accelerator marketing is quoted in FLOPs, and FLOPs are the wrong number to care about for most of what an LLM actually does in production. Token generation is bound by how fast weights can be moved out of memory, not by how fast the chip can multiply them.
Two phases, two bottlenecks
Inference splits into prefill — processing the prompt you sent — and decode — emitting the response one token at a time.
Prefill handles every prompt token at once, so it is a dense matrix multiply with plenty of arithmetic per byte loaded. It genuinely uses the compute units, and here FLOPs matter.
Decode is the opposite. Generating one token requires reading the entire set of active weights from memory and doing comparatively little arithmetic with them. The compute units sit largely idle waiting on memory. Then the next token requires reading all those weights again.
This is why the ceiling on single-stream generation speed is close to a division problem: memory bandwidth divided by the bytes of weights touched per token. Doubling a chip’s FLOPs while leaving bandwidth alone barely moves that number.
Why batching changes the picture
Load the weights once and run many sequences through them together, and the cost of that memory traffic is shared across every request in the batch. Arithmetic per byte loaded goes up, the compute units start earning their keep, and throughput rises far faster than latency for any individual user.
Hence the split personality of inference economics. Serving many concurrent users is a throughput problem where batching does the heavy lifting. Making one user’s response arrive faster is a bandwidth problem, and batching does not help at all — it usually hurts.
What the KV cache does to memory
Attention needs the keys and values of every previous token, so they are cached rather than recomputed. That cache grows with sequence length and with batch size, and it is read on every single decode step.
Two consequences follow. Long contexts cost bandwidth continuously, not just once at prefill. And the cache competes with the weights for the same finite memory, which is why the maximum batch size a deployment can sustain falls as context length rises. Much of the architectural work of recent years — grouped-query attention, multi-query attention, paged cache allocation — exists to make this cache smaller or cheaper to read.
Reading a spec sheet
If you are sizing hardware for serving rather than training, the numbers worth comparing are memory capacity, memory bandwidth, and interconnect bandwidth if the model will not fit on one device. Capacity decides whether you can hold the model and a useful cache at all; bandwidth decides how fast tokens come out; interconnect decides how much you lose to splitting the model across chips.
Peak FLOPs belongs further down that list than its position in the marketing suggests. It is the number that sells accelerators, and the one least likely to determine what your deployment feels like.
