
LLM benchmarks
-
Mistral AI valuation and coding benchmark reality
Mistral AI reached a $24 billion valuation following a €3 billion Series D round led by Samsung Electronics. While Mixtral 8x22B shows…
-
Common mistakes with Cognition’s $2B Devin AI deployment
Cognition’s Devin AI achieves only 13.86% on the SWE-Bench test set, struggling with ambiguous tasks and brownfield production systems. While GitHub Copilot…
-
OpenAI o3 vs Google DeepMind Gemini 2.5 Pro reasoning benchmarks
OpenAI o3 leads reasoning benchmarks with an 86.4 score on AIME 2025, while Gemini 2.5 Pro offers superior multimodal input capabilities including…
-
Mistral AI valuation shifts and Llama 4 benchmark disputes
Mistral AI reached a post-money valuation exceeding €21 billion following a September 2026 Series D round led by Samsung Electronics. The company…
-
Runway Gen-4.5 leads video benchmarks as Sora faces discontinuation
Runway’s Gen-4.5 model leads the Artificial Analysis Text to Video benchmark with 1,247 Elo points, outperforming Google and OpenAI. The platform offers…
-
Implementing Codestral 25.01 for Legacy Codebase Migration
Codestral 25.01 features a 256k context window and achieves an 86.6% HumanEval score for Python. This model supports enterprise modernization workflows by…
-
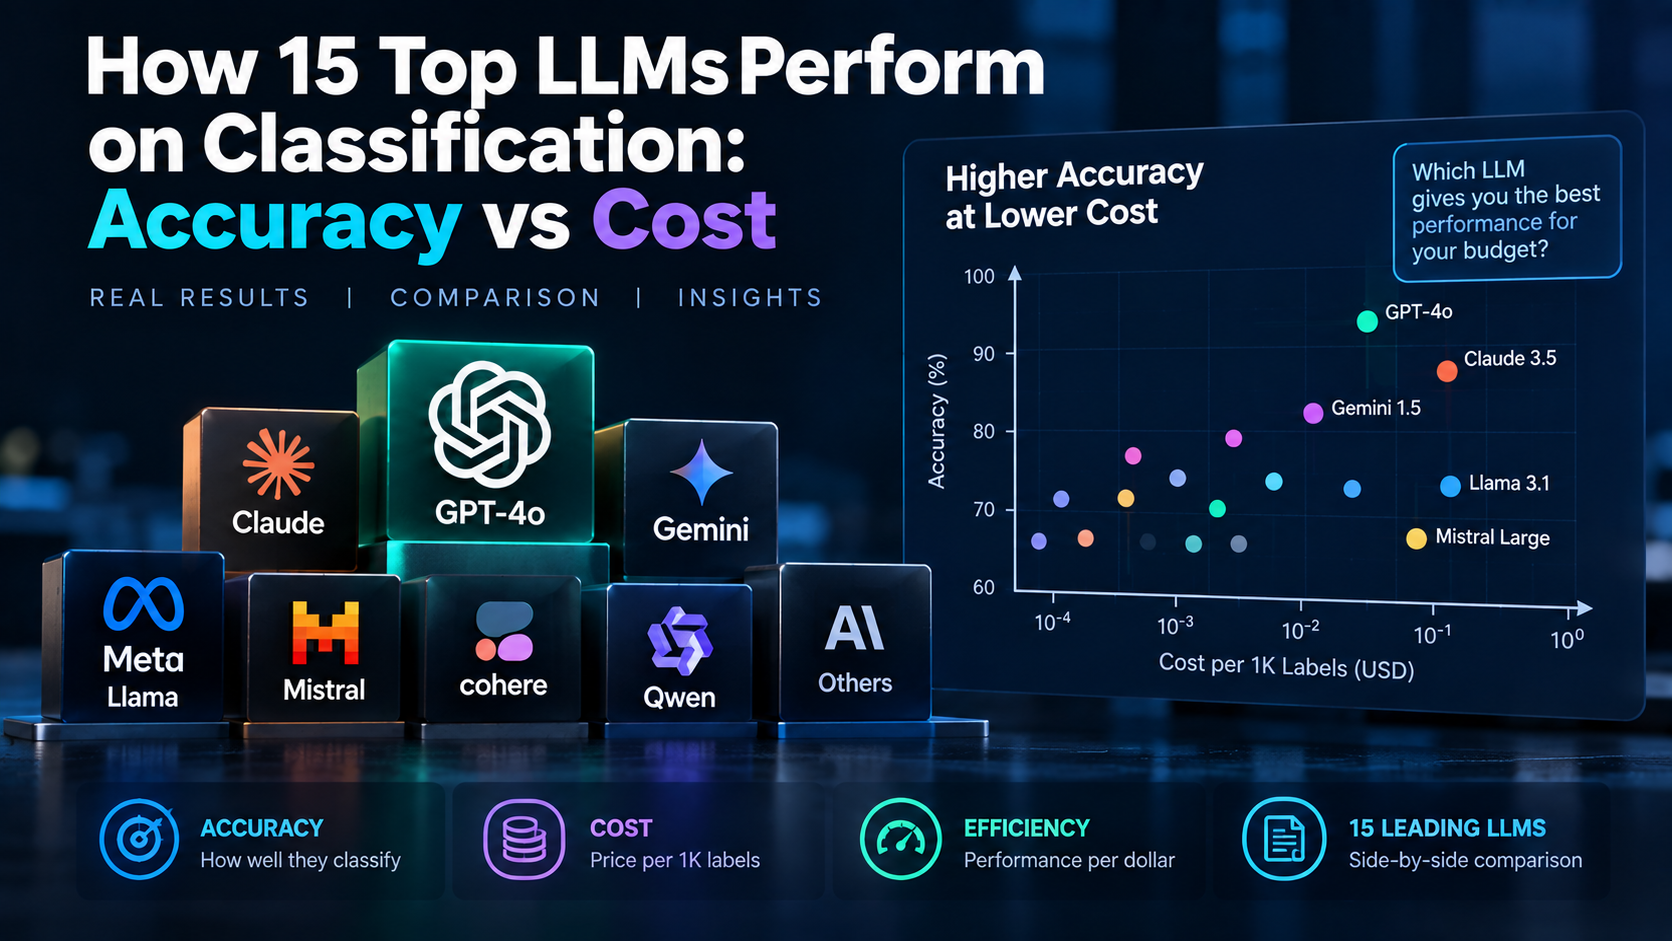
How 15 Top LLMs Perform on Classification: Accuracy vs Cost
Classification is the task most often hiding inside a production system, and the one where per-call cost compounds fastest. How to compare…
Trending Now
- Mistral AI Codestral pricing vs Claude 3.5 Sonnet coding adoption
- Lambda Labs GPU cloud and NVIDIA H100 clusters
- Runway Gen-4 vs Pika Labs 2.0: Comparing AI video models
- Poolside engineers use the $3B coding model to automate software development
- Posit releases version 2026.11.0 for data science workflows