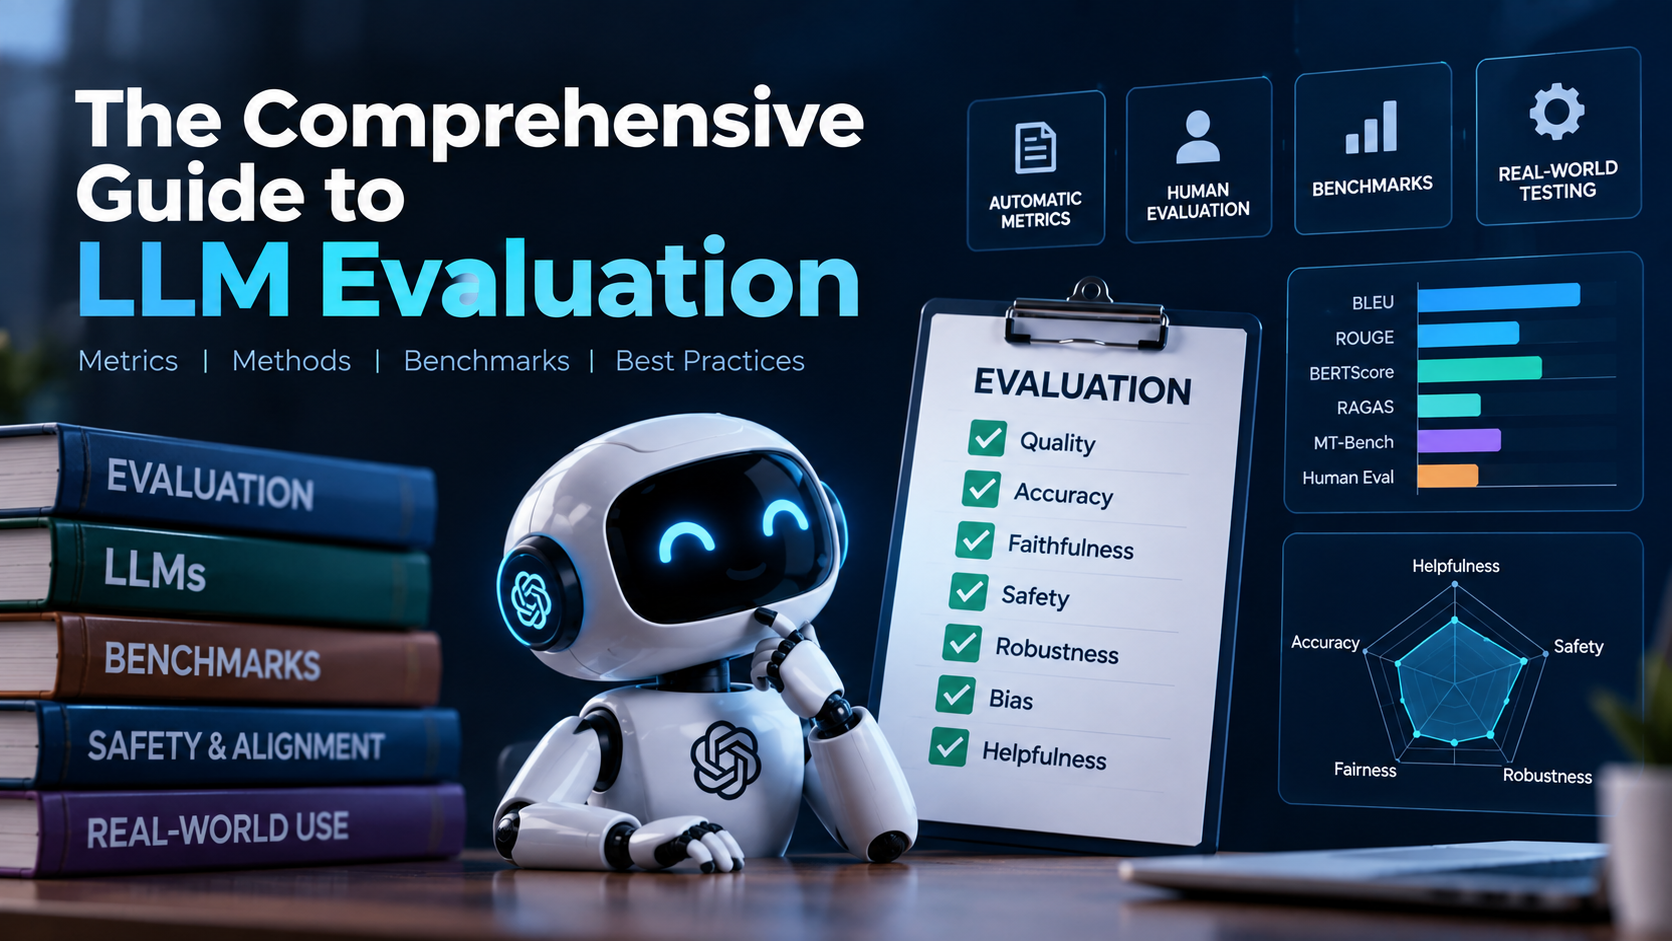
Evaluation is the part of building with language models that teams postpone and then regret postponing. It is unglamorous, it produces no demo, and it is the only thing standing between a prototype that impressed everyone in a meeting and a system you can change without fear. This guide covers the approaches that matter, what each is actually good for, and how to assemble them into something you will keep using.
Four kinds of evaluation
The vibe check
You change the prompt, you try a few inputs, you eyeball the outputs. Everyone does this and everyone should — it is the fastest possible feedback loop and it catches gross failures immediately.
Its failure mode is equally well known. It tests whatever you happened to think of, it cannot detect a regression on the case you fixed three weeks ago, and it is subject to the fact that you wrote the prompt and therefore already know what it is supposed to do. Treat it as development ergonomics, never as evidence.
Batch offline evaluation
A fixed dataset, a scoring function, a number at the end. This is the backbone: it makes changes comparable, it runs in CI, and it turns “I think this prompt is better” into something you can check.
The dataset is the hard part and the part most teams get wrong. It must come from real production traffic rather than from your imagination, it must include the cases that have actually failed, and it must be refreshed as your usage changes. A stale evaluation set gives you a confident number about a distribution you no longer serve.
Online evaluation and monitoring
Offline evaluation tells you about the inputs you collected. Production will show you inputs you did not imagine, and it will show them to you at volume. Monitoring covers the operational signals — latency, cost per request, error and refusal rates, output length distributions — plus sampled quality scoring on live traffic.
The most valuable thing here is usually not a quality score. It is the drift signal: the distribution of what users are asking has moved away from what you tested, and that is the leading indicator of every quality problem you are about to have.
Human evaluation
Expensive, slow, and still the ground truth everything else is calibrated against. Two forms are worth distinguishing. Explicit annotation — people scoring outputs against a rubric — gives you high-quality labels at high cost, and is worth it for a small set you use as a reference. Implicit user feedback — thumbs, edits, retries, abandonment — is nearly free and much noisier, but it comes from real users pursuing real goals, and a user who silently rewrites your output has told you something no rubric captures.
The common mistake is skipping human evaluation because it does not scale. It does not need to scale. A few hundred carefully labelled examples are enough to calibrate everything automatic you build on top.
Metrics
When there is a right answer
Classification, extraction and routing have discrete correct outputs, so use the ordinary supervised metrics: accuracy, and then precision, recall and F1 once you remember that your classes are imbalanced. Decide deliberately whether false positives or false negatives hurt more; that choice is a product decision and it determines which number you optimise.
When there is a reference text
BLEU and ROUGE count n-gram overlap. They are fast and deterministic, and they punish paraphrase, which makes them poor proxies for meaning. Embedding-based metrics such as BERTScore compare contextual token embeddings instead and correlate better with human judgement, at the cost of speed and cross-configuration comparability.
All of them measure similarity to a reference rather than quality, so they are best used as regression detectors — has this change moved the number — rather than as absolute scores.
When there is no reference at all
This is most real generation work, and LLM-as-judge is the practical answer: a strong model scores outputs against an explicit rubric. It scales, it handles open-ended tasks, and it agrees with human raters well enough to be useful when the rubric is good.
It also has known biases that you must design around. Judges prefer longer answers, they prefer their own family’s outputs, and in pairwise comparison they are sensitive to presentation order. Mitigate by randomising order, keeping rubrics concrete and narrow rather than asking for a holistic score out of ten, and periodically checking judge agreement against your human-labelled set. A judge you have never calibrated is a number generator.
Assembling it
A setup that works for most teams, in the order worth building it:
- Collect real inputs from day one. Log everything. You cannot reconstruct this later, and it is the raw material for every other step.
- Label a few hundred by hand. Painful, non-negotiable, and the calibration reference for everything automatic.
- Write assertions before you write scores. Deterministic checks — valid JSON, required fields present, no leaked system prompt, within length bounds — catch a large share of real failures at zero cost and never drift.
- Add automatic scoring on top. Judge or reference-based, depending on the task.
- Put it in CI. An evaluation you run manually is an evaluation you stop running by the third week.
- Close the loop from production. Every real failure becomes a test case. This is what makes the suite get better rather than staler.
The failure modes to watch for
Optimising the metric instead of the product. Any measure you push hard enough stops measuring the thing you wanted. Keep a human-reviewed set outside the optimisation loop as your check against it.
Evaluating the model instead of the system. Your users experience retrieval, prompt, model, parsing and fallbacks as one thing. A benchmark score for the model in isolation tells you little about the system that wraps it.
One number for everything. A single score hides that you improved the common case and broke the rare one. Report per-segment results, and make sure the segments that matter to the business are among them.
Building the harness and never revisiting it. The value is in the loop, not the artefact. A suite that has not gained a test case in two months has stopped tracking your product.