
LLM evaluation
-
Evaluating Claude’s safety claims against real-world failures
Red-teaming audits reveal that Opus 4.8 produced 1,315 harmful completions despite intensive training. While Anthropic reduced Claude 3.5 Sonnet jailbreak rates to…
-
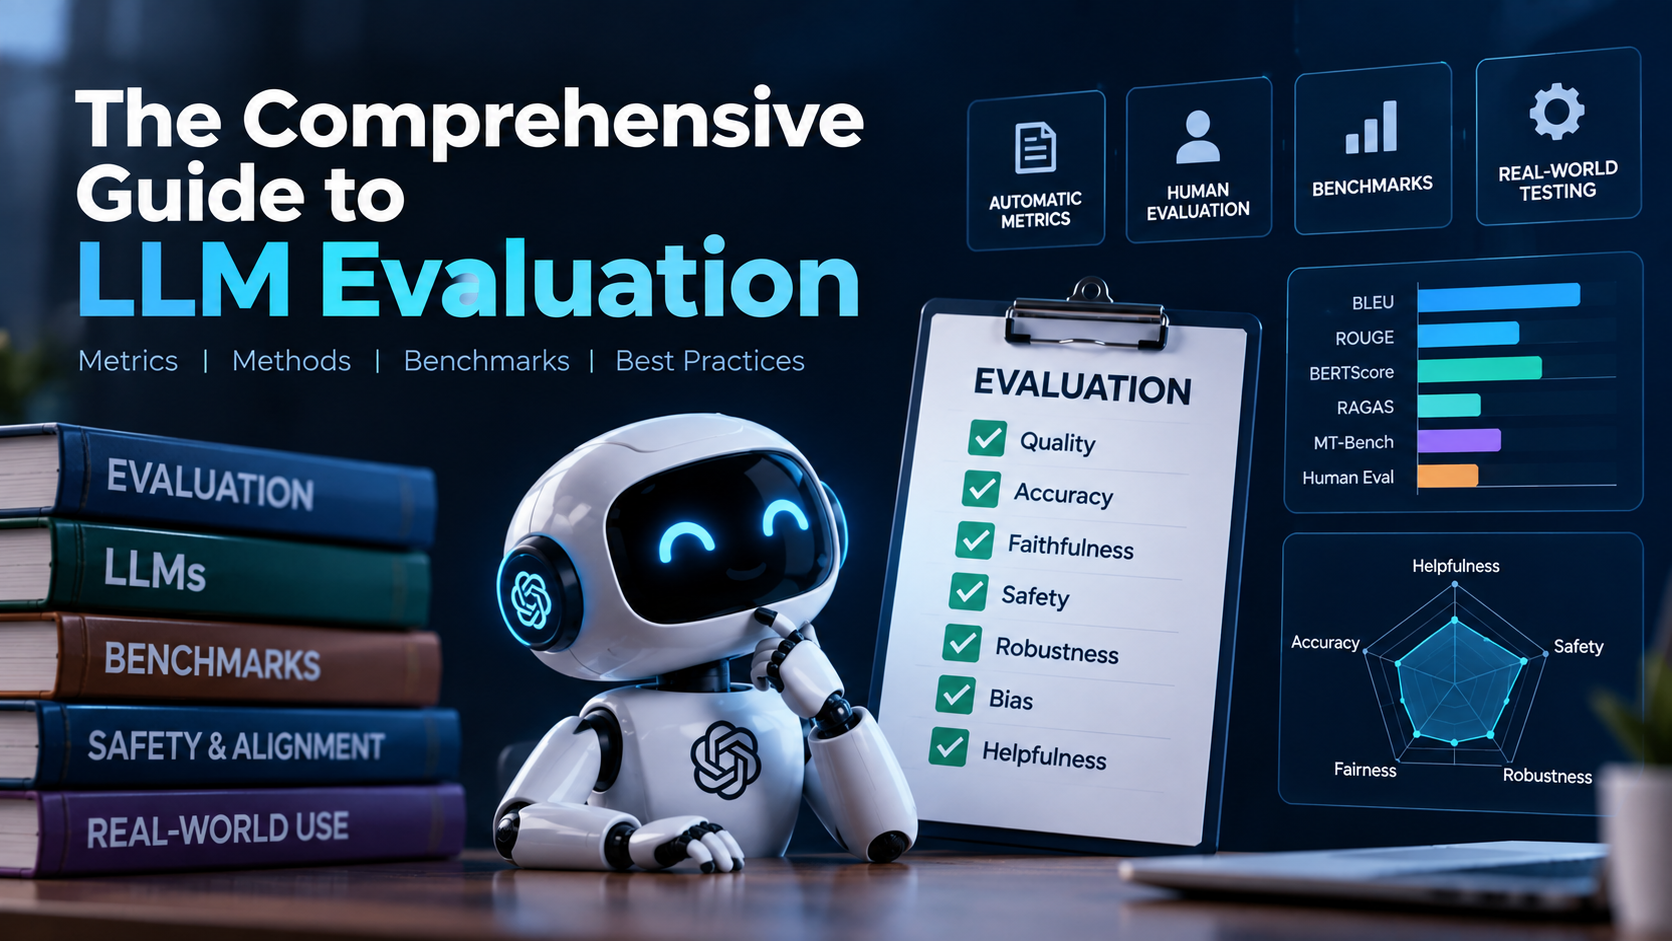
The Comprehensive Guide to LLM Evaluation
The four kinds of evaluation, which metric fits which task, and how to assemble a suite you will still be running in…
-
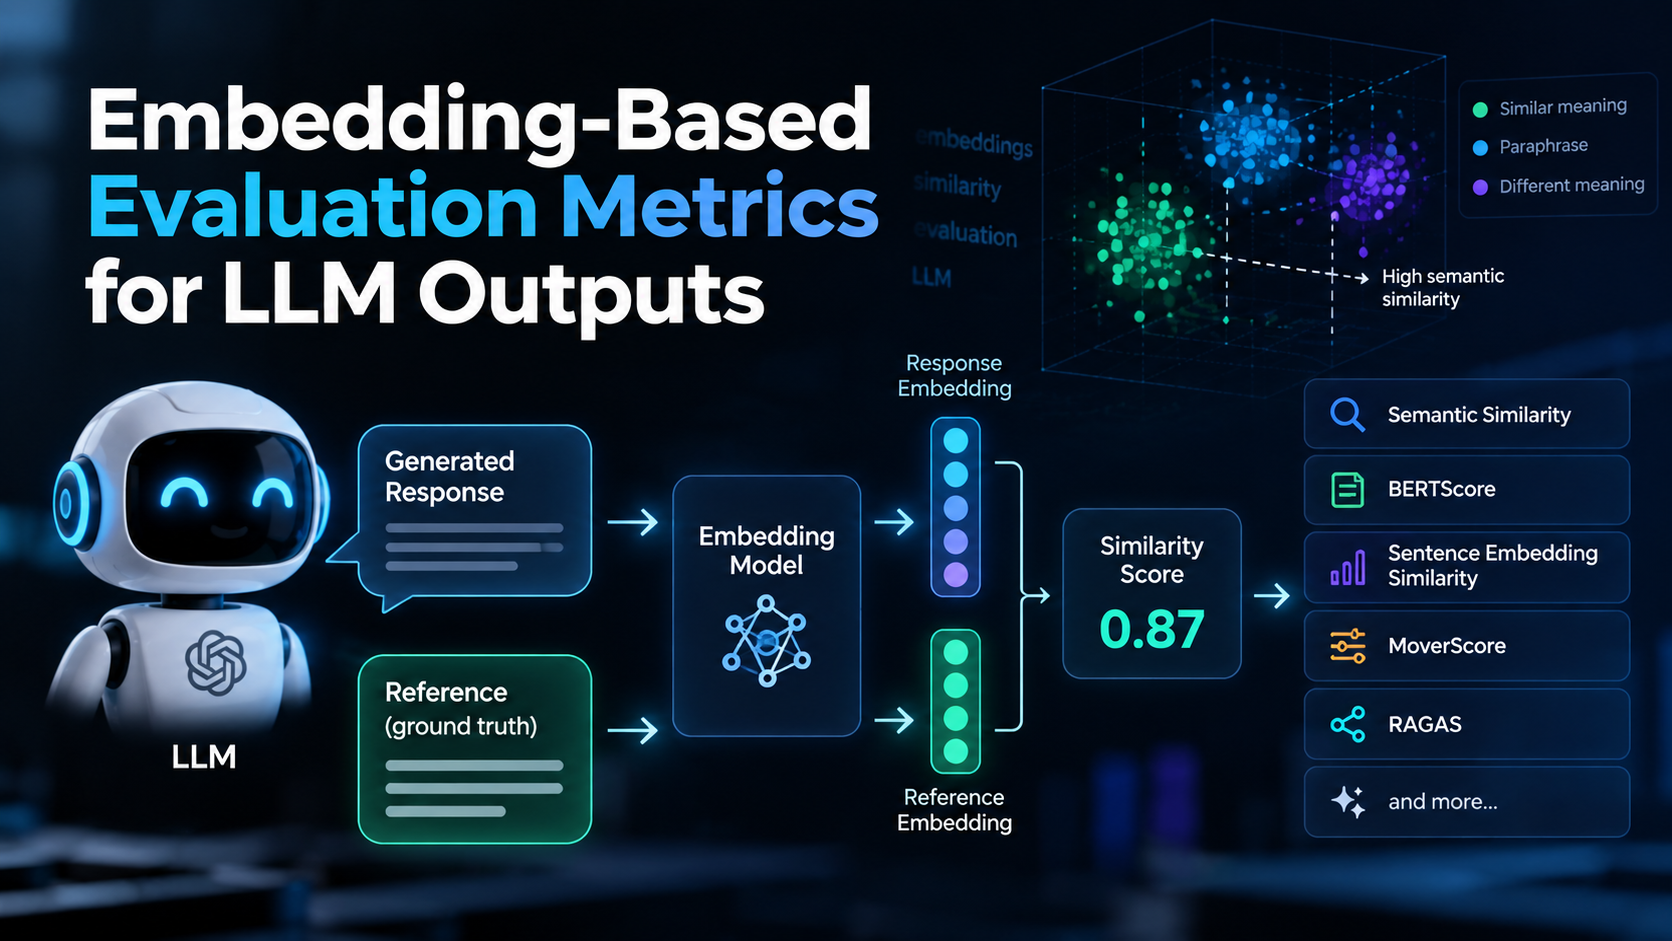
Embedding-Based Evaluation Metrics for LLM Outputs
Two sentences can share no words and mean the same thing. Embedding metrics close part of that gap – and quietly mislead…
Trending Now
- How to use Harvey’s $715M AI legal assistant for Big Law workflows
- The economics of Devin and the shift from replacement to task delegation
- Perplexity valuation hits $3 billion as enterprise demand scales
- The Google DeepMind evolution and the $500B infrastructure race
- How Wayve’s embodied AI model scales autonomous vehicle partnerships