Excessive HBM fragmentation and parameter spikes
HBM fragmentation in TPU v5p clusters can exceed 50%, which prevents models that theoretically fit in 16GB from running. In one observed case, the system converted all parameters from f32 to bf16 in one block at the beginning of the run. This conversion process consumed an additional 1.4GB of memory. Large HLO temp space also contributes to these memory shortages. Engineers can try jax.lib.xla_bridge.get_backend().defragment() to clear these buffers, although this method waits for all JAX operations to finish. Does the HLO scheduler provide enough relief for these massive parameter shifts? You should check if the HLO temp space is absorbing your available capacity.
The memory requirements for Gemini 2.5 Pro fine-tuning depend on the specific parameter precision and the allocated headroom. When the system performs mass conversions of parameters, it creates large, contiguous memory needs that often lead to allocation failures.
The VMEM to HBM bandwidth bottleneck
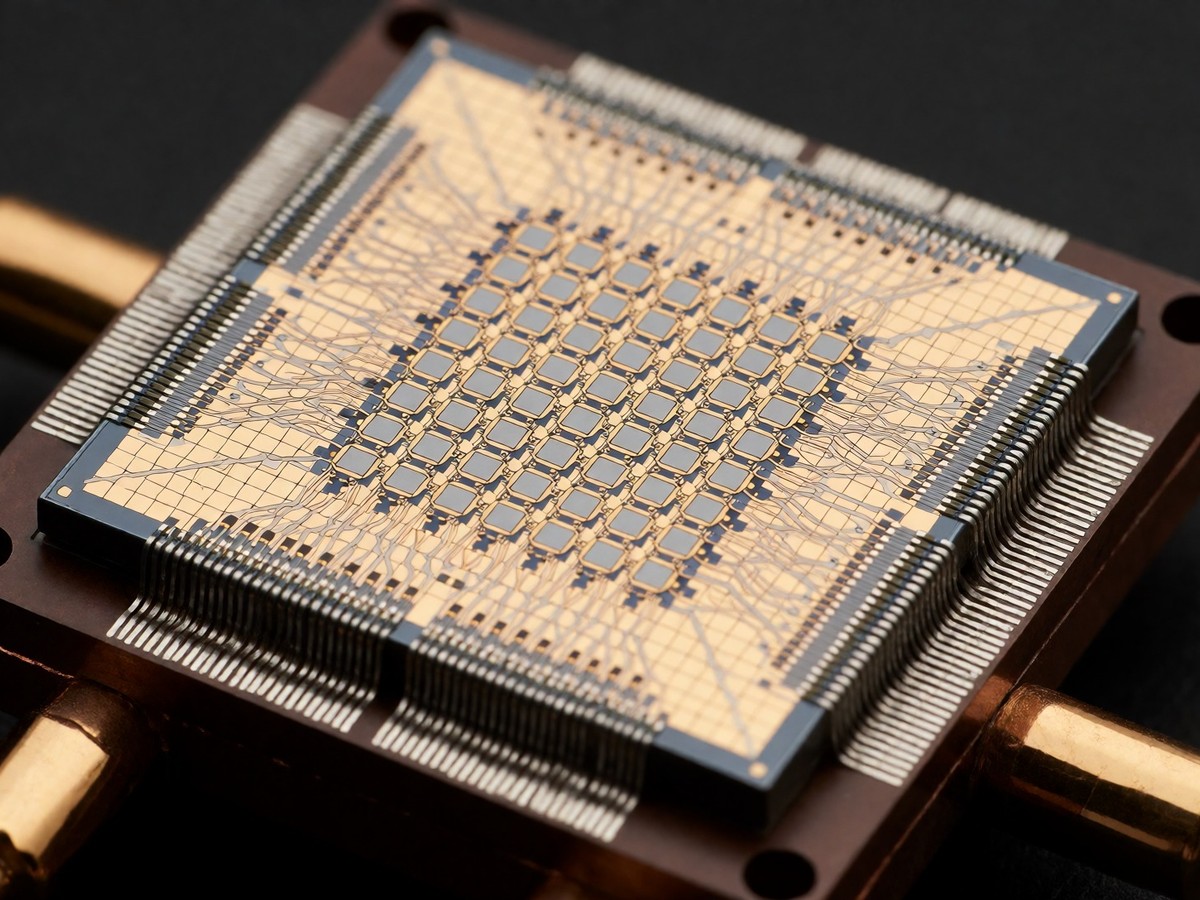
The TPU v5p architecture requires a specific data flow to maintain high performance. Data travels from HBM to VMEM, then into the systolic array of the MXU. VMEM on a TPU v5p chip contains 64 MiB of space. The HBM to VMEM bandwidth must stay ahead of the VPU or MXU FLOPs. If the HBM to VMEM load is slower than the compute speed, the chip becomes bandwidth bound. To avoid starving the MXU, engineers must manage the arithmetic intensity of the workload. VMEM is much smaller than HBM but has much higher bandwidth to the MXU. If an algorithm fits all inputs and outputs in VMEM, it avoids communication bottlenecks. VMEM bandwidth on the TPU v5p is roughly 7 times higher than the HBM bandwidth. An MXU operation reading from or writing to VMEM requires a 7x lower arithmetic intensity than an operation using HBM to achieve peak FLOPs utilization. This difference becomes important when training Gemini 2.5 Pro. The TPU v5p architecture uses a 3D torus topology where optical circuit switches manage 13,824 optical ports across 48 units to provide high-speed connectivity between chips in massive 16x20x28 superpods. This interconnect capacity reaches 4,800 Gbps per chip.
The system uses ICI for communication between chips in a slice, while DCN handles communication between different slices. ICI is much faster than DCN, which provides 12.5 GB/s of egress bandwidth per chip. The MXU performs 16,000 multiply-accumulate operations per cycle using 128×128 arrays. The VPU performs general mathematical operations like ReLU activations or pointwise addition. All multiplies take bfloat16 inputs, while accumulations are performed in FP32.
Scaling Gemini 2.5 Pro across multi-node slices
Scaling Gemini 2.5 Pro requires matching model size to chip capacity. A 70B parameter model in bf16 uses 140 GB for weights. Adding 30 percent for the key value cache and runtime overhead brings the total requirement to 182 GB. TPU v5p provides 95 GB of HBM per chip. This means a single chip cannot hold the model. A single TPU v5p chip provides 4.8 TB/s of HBM bandwidth.
The TPU v5p also includes four SparseCores per chip to handle embedding-intensive workloads. These SparseCores have 512 KiB of VMEM each. These specialized processors can provide 5-7x speedups for models with massive vocabulary embeddings. You should evaluate your capacity against these requirements to avoid multi-node stalls. TPU v5p compute outperforms TPU v4 by 2X. The v5p provides 95 GB of HBM, while v4 provides 17 GB. While the NVIDIA H100 provides 80 GB of HBM, the TPU v5p shows higher Model FLOPs Utilization for specific LLM workloads. In testing, the H100 showed a lead in raw per-chip throughput for smaller batches, but the TPU v5p memory bandwidth of 4.8 TB/s provides better efficiency at larger batch sizes.