
model training
-
Mosaic AI capabilities and the reality of ML model governance
Databricks integrates Mosaic AI for the full generative AI lifecycle, including training and fine-tuning. While Snowflake Cortex AI offers SQL-based inference, Databricks…
-
AMD MI350X challenges Blackwell in training clusters
AMD’s Instinct MI355X delivers 1.3X higher inference throughput than the NVIDIA B200 on Llama 3.1 405B workloads. The new CDNA 4 architecture…
-
The risks in Cerebras’ WSE-3 rollout
Cerebras faces significant market volatility after OpenAI chose NVIDIA GPUs for its GPT-6.1 Sol Ultrafast mode, causing Cerebras stock to drop nearly…
-

Poolside’s $3B AI coding agent and PipelineRL technical framework
Poolside leverages its PipelineRL framework to achieve learning speeds twice as fast as conventional baselines by overlapping sequence generation and model training.…
-
HBM fragmentation and bandwidth bottlenecks in TPU v5p clusters
HBM fragmentation in TPU v5p clusters can exceed 50%, causing allocation failures during Gemini 2.5 Pro fine-tuning. Performance also depends on managing…
-
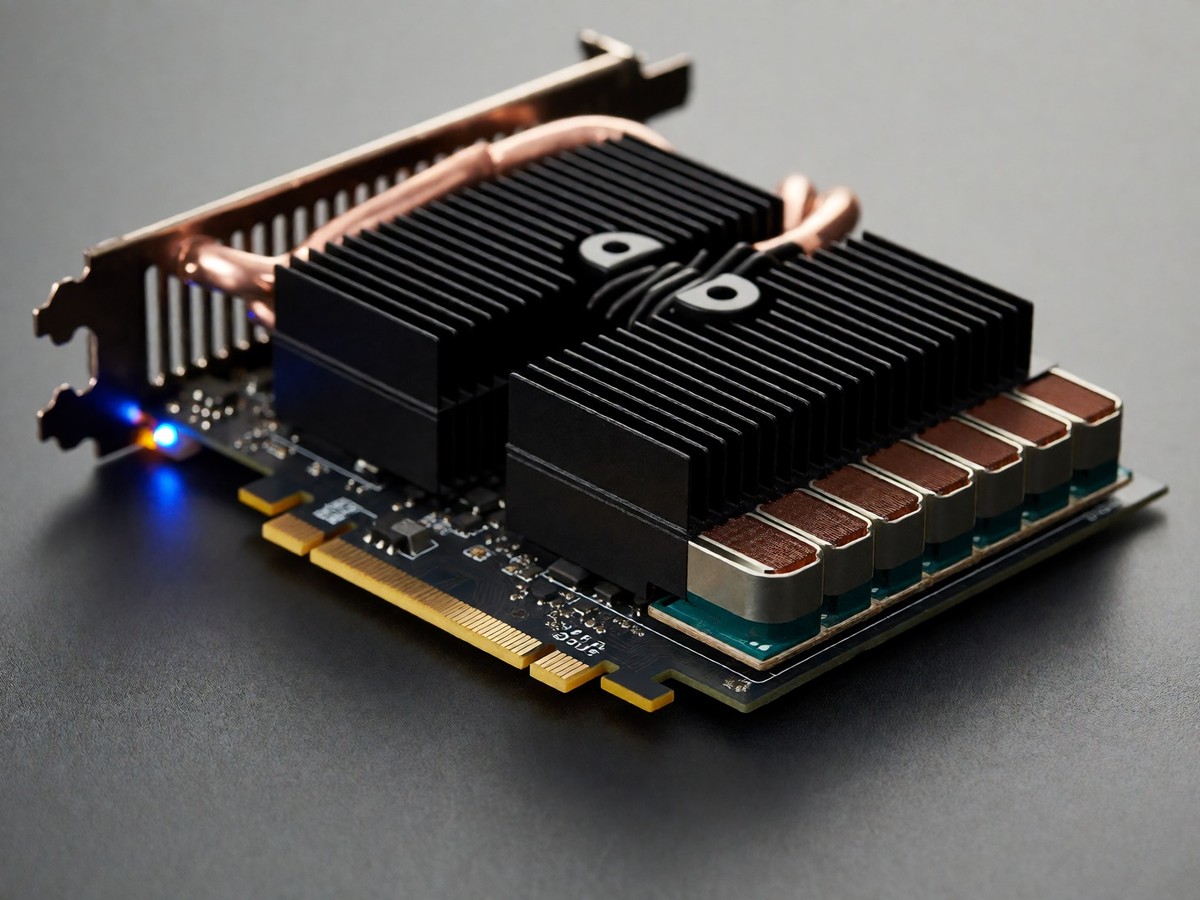
Avoiding HBM bottlenecks in Gaudi 3 LLaMA 405B clusters
Intel Gaudi 3 provides 3.7 TB/s of HBM bandwidth, but failing to use dynamic memory allocation can cause a 20% drop in…
-
VRAM Waste and Routing Failures in MI300X MoE Fine-Tuning
Engineers provisioning AMD Instinct MI300X clusters often face memory failures by using inference-only sizing for MoE training. Proper provisioning for a 235B…
-
H200 memory bandwidth inefficiencies in distributed training
Improper NUMA settings and hardware selection can waste the 4.8 TB/s memory bandwidth of the NVIDIA H200. Communication errors with the Power…
-
Scaling Llama 3.3 70B on Lambda Labs 8x H100 instances
Training Llama 3.3 70B requires significant VRAM, with full fine-tuning demanding 1,158 GB. Lambda Labs provides 8x H100 SXM nodes with 3200…
-
Cerebras CS-3 wafer-scale engine and sparse MoE training explained
The Cerebras WSE-3 integrates 4 trillion transistors and 900,000 AI cores onto a single 300mm silicon wafer. This monolithic design delivers 125…
-
Databricks’ $1.3B MosaicML acquisition shifts LLM training costs
Databricks leverages its $1.3 billion MosaicML acquisition to enable enterprises to train custom large language models up to 7x faster. The platform…
-
Fine-tuning Llama 3.3 70B on Together AI
Together AI provides an OpenAI-compatible API for fine-tuning Llama 3.3 70B using LoRA or full fine-tuning methods. Developers can access serverless endpoints…