
Latest stories
-
Anthropic’s revenue growth and the accounting gap explained
Anthropic’s annualized revenue reached $65 billion, driven largely by Claude Code and a massive surge in enterprise customers. The company’s lead over…
-
What AI Revenue Multiples Actually Measure
The same headline revenue can mean very different economics once the inference bill is taken out. The questions that separate similar-looking companies.
-
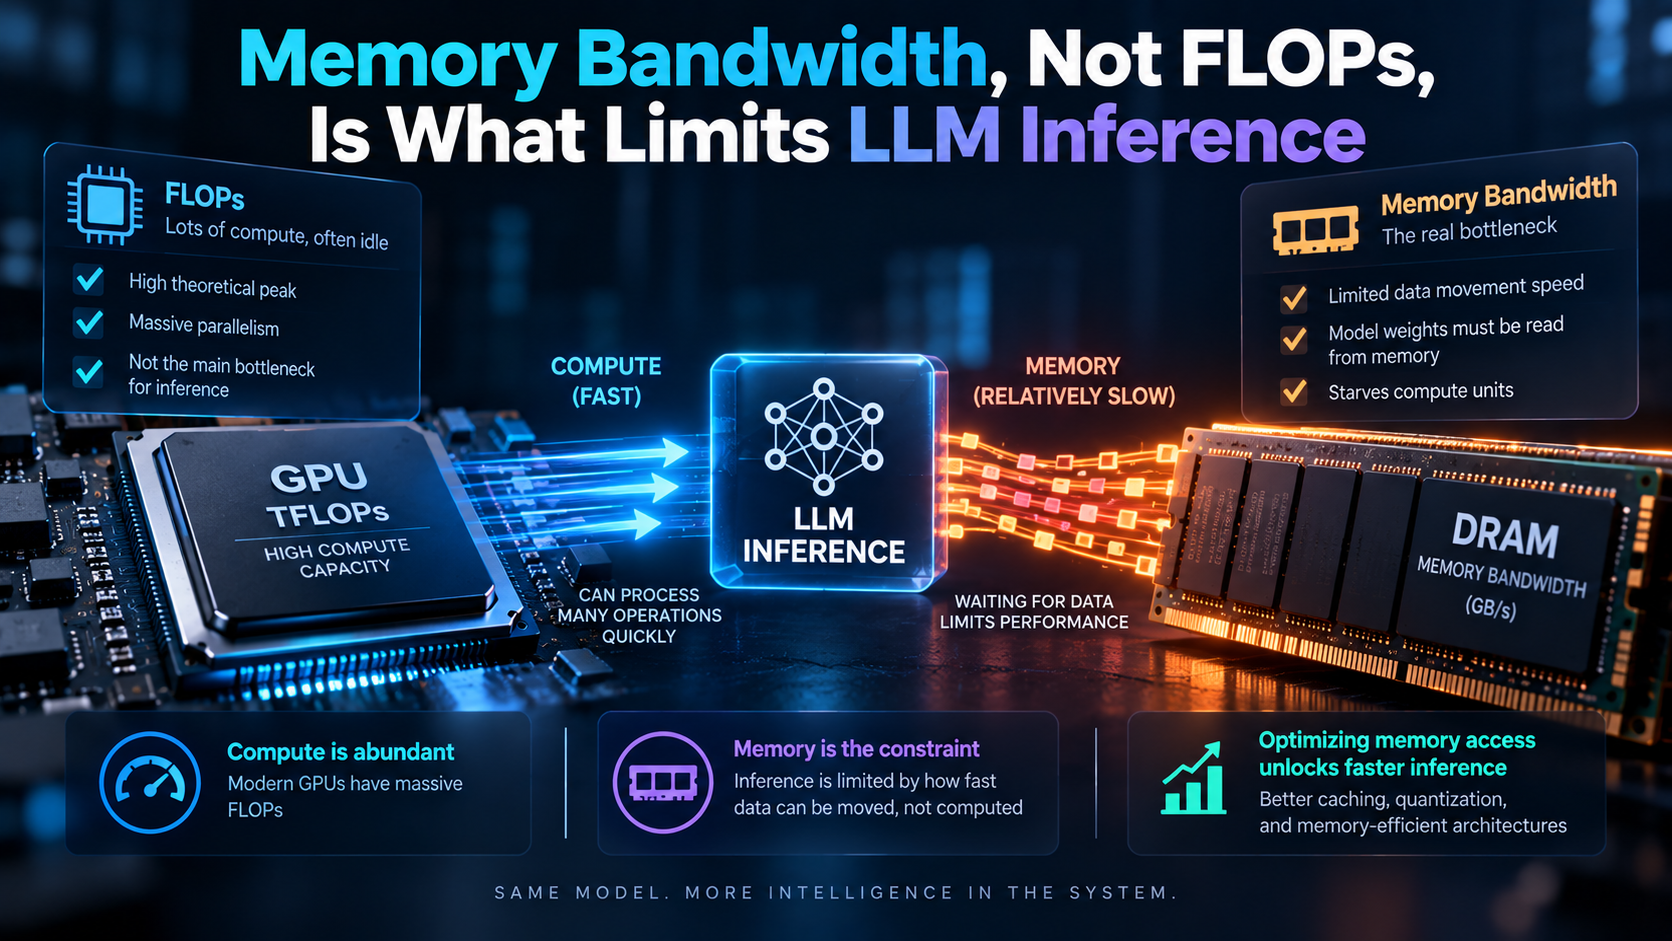
Memory Bandwidth, Not FLOPs, Is What Limits LLM Inference
Accelerators are sold on peak FLOPs, but token generation is bound by how fast weights move out of memory. What to actually…
-
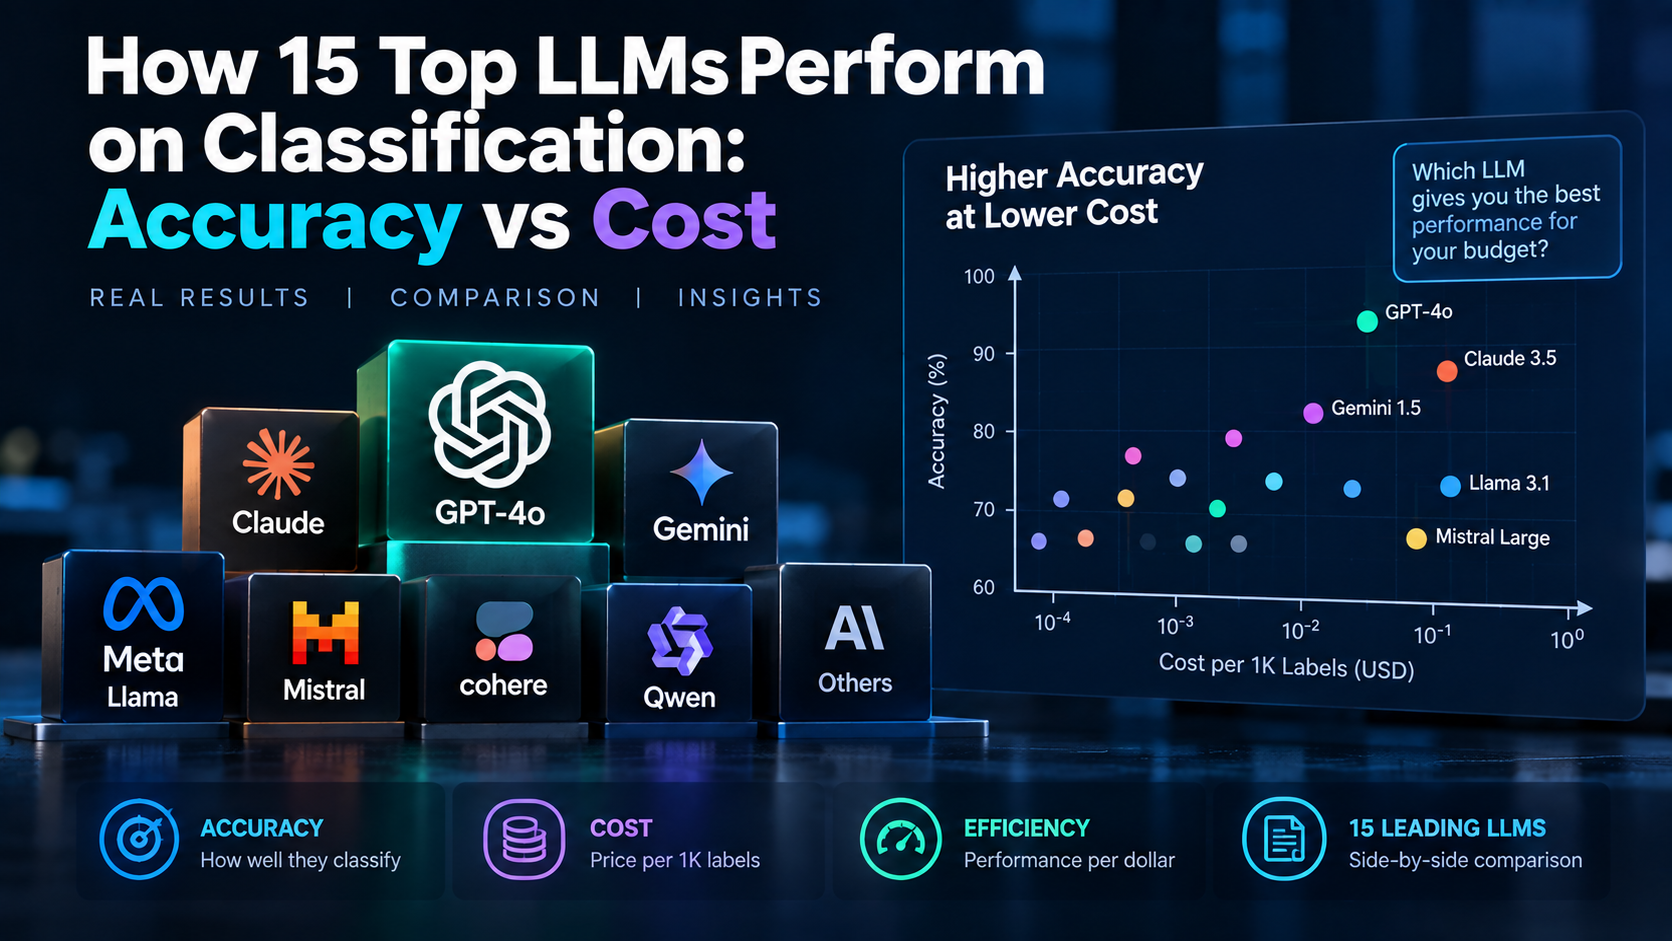
How 15 Top LLMs Perform on Classification: Accuracy vs Cost
Classification is the task most often hiding inside a production system, and the one where per-call cost compounds fastest. How to compare…
-
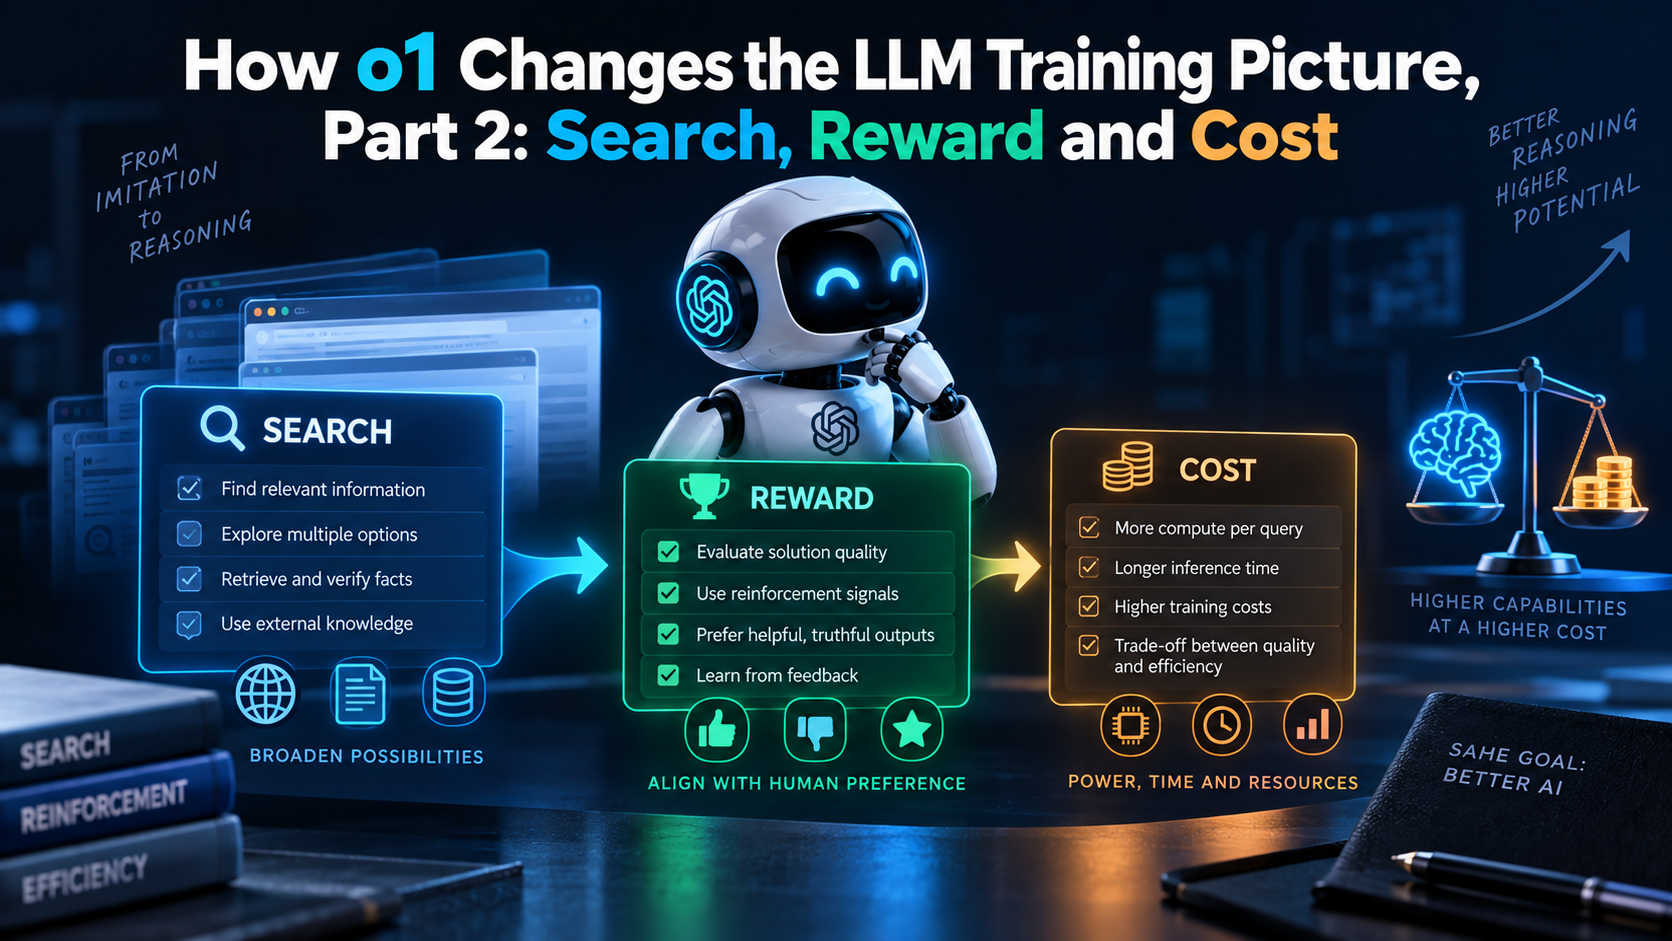
How o1 Changes the LLM Training Picture, Part 2: Search, Reward and Cost
What reasoning models borrow from game-playing systems, why the reward signal is the bottleneck outside maths and code, and when the extra…
-
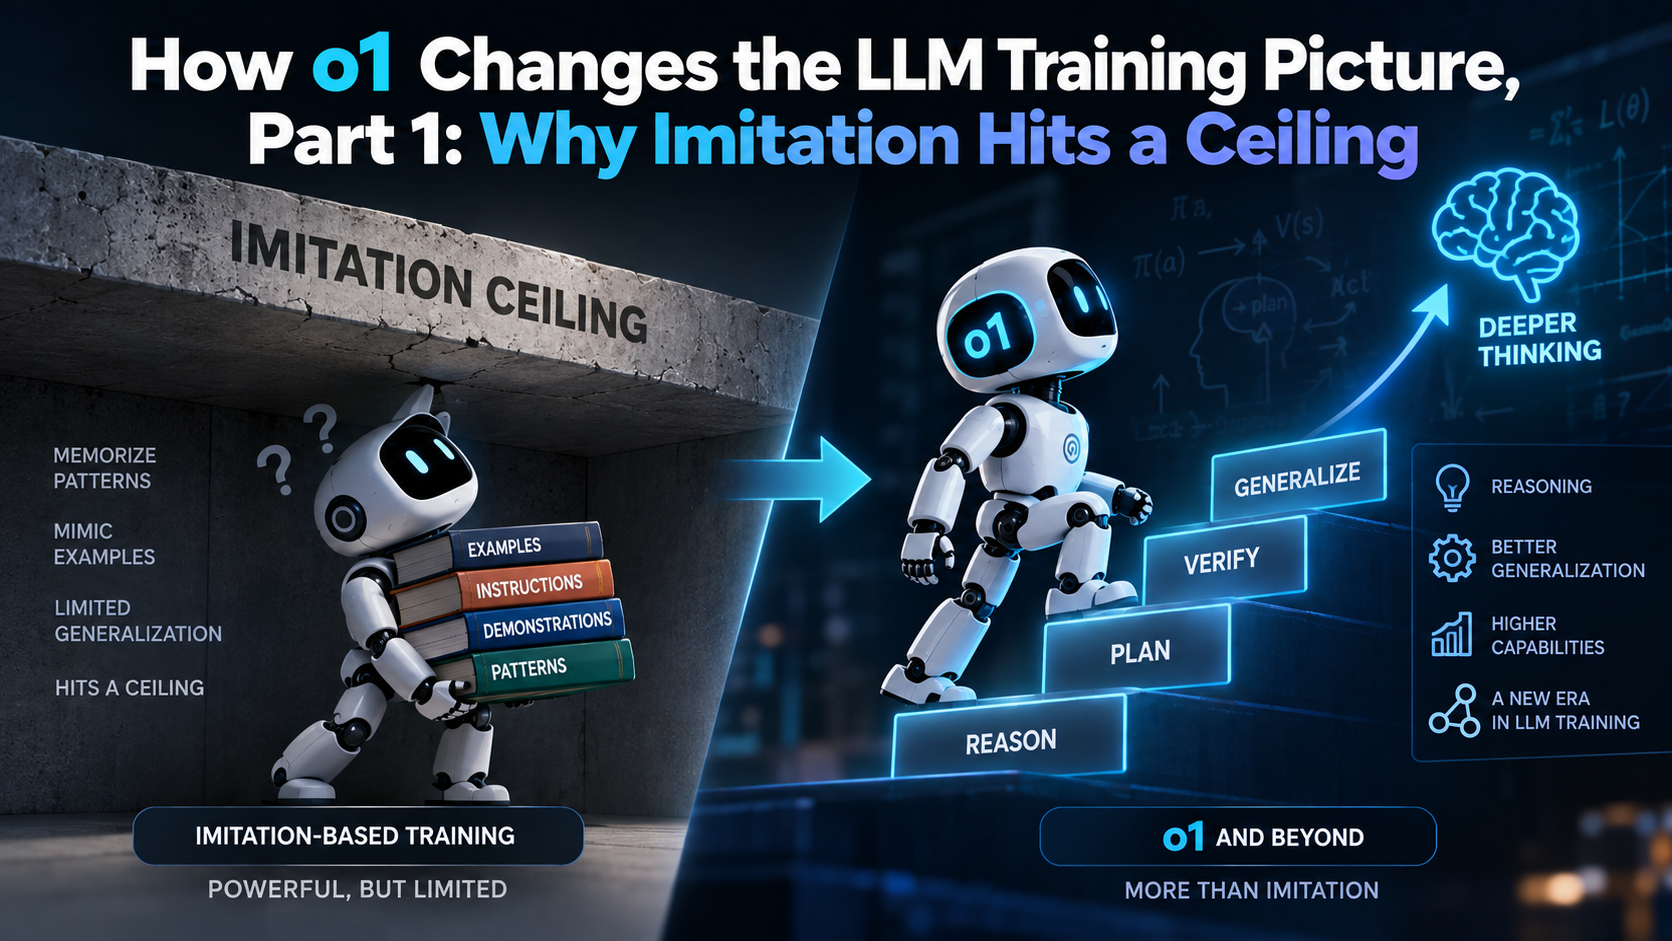
How o1 Changes the LLM Training Picture, Part 1: Why Imitation Hits a Ceiling
Pre-train, fine-tune, align. The standard recipe produced remarkable models and could not produce reasoning. Why that limit is structural rather than a…
-
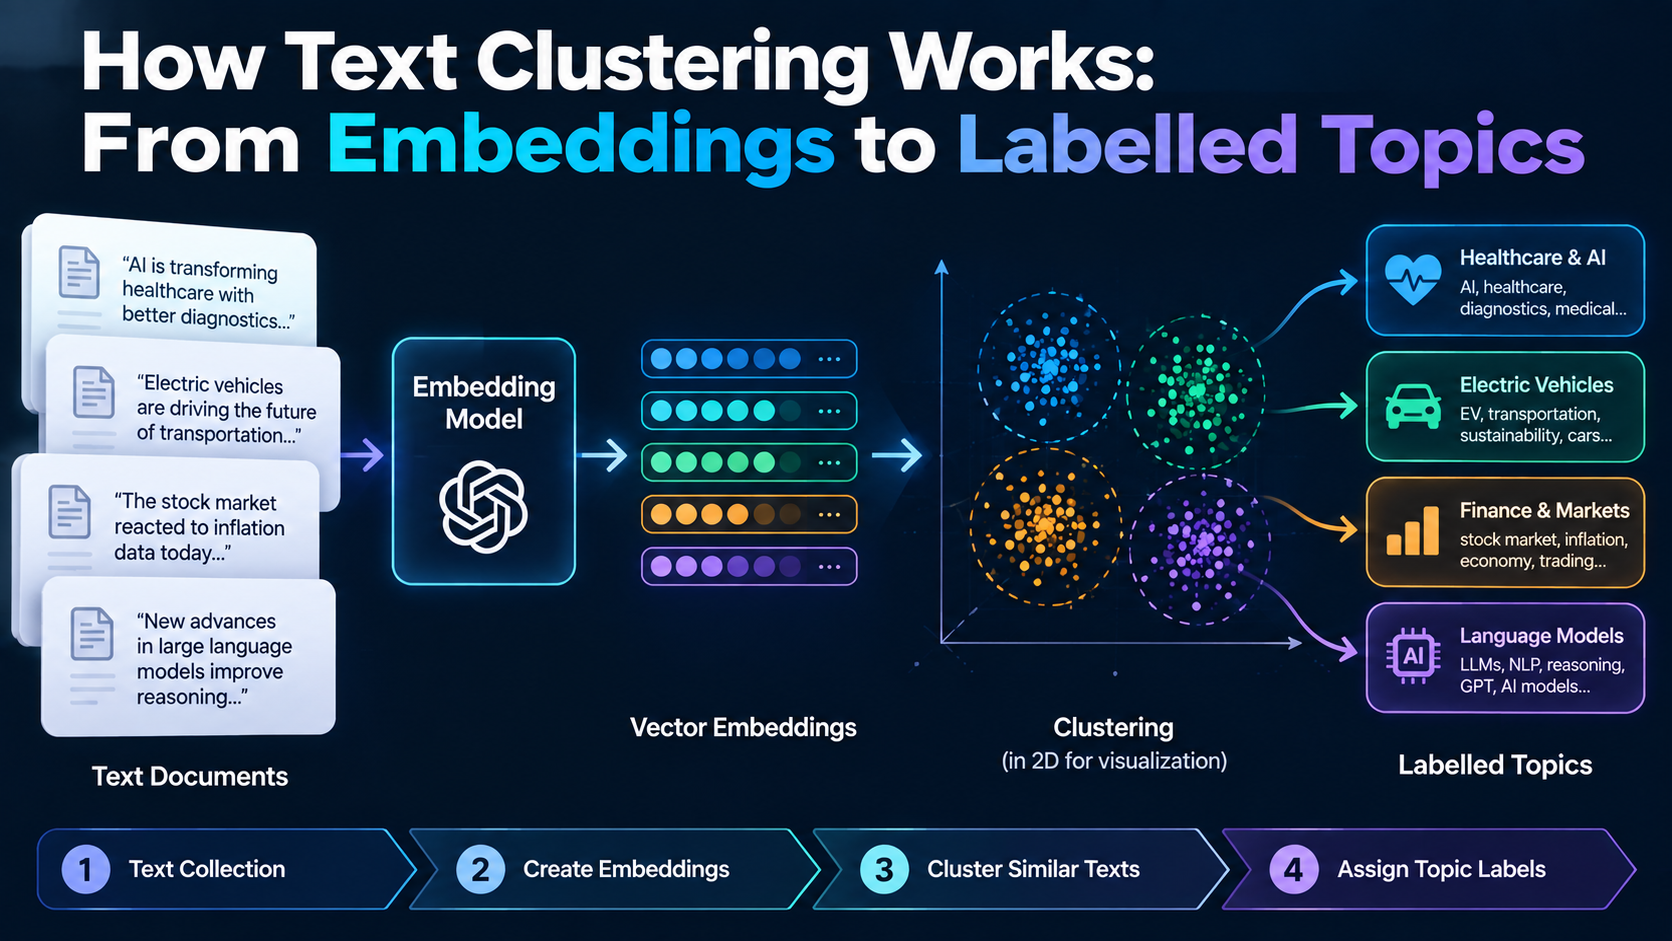
How Text Clustering Works: From Embeddings to Labelled Topics
Fifty thousand support tickets nobody has read. The pipeline that turns them into named topics, and why k-means is usually the wrong…
-
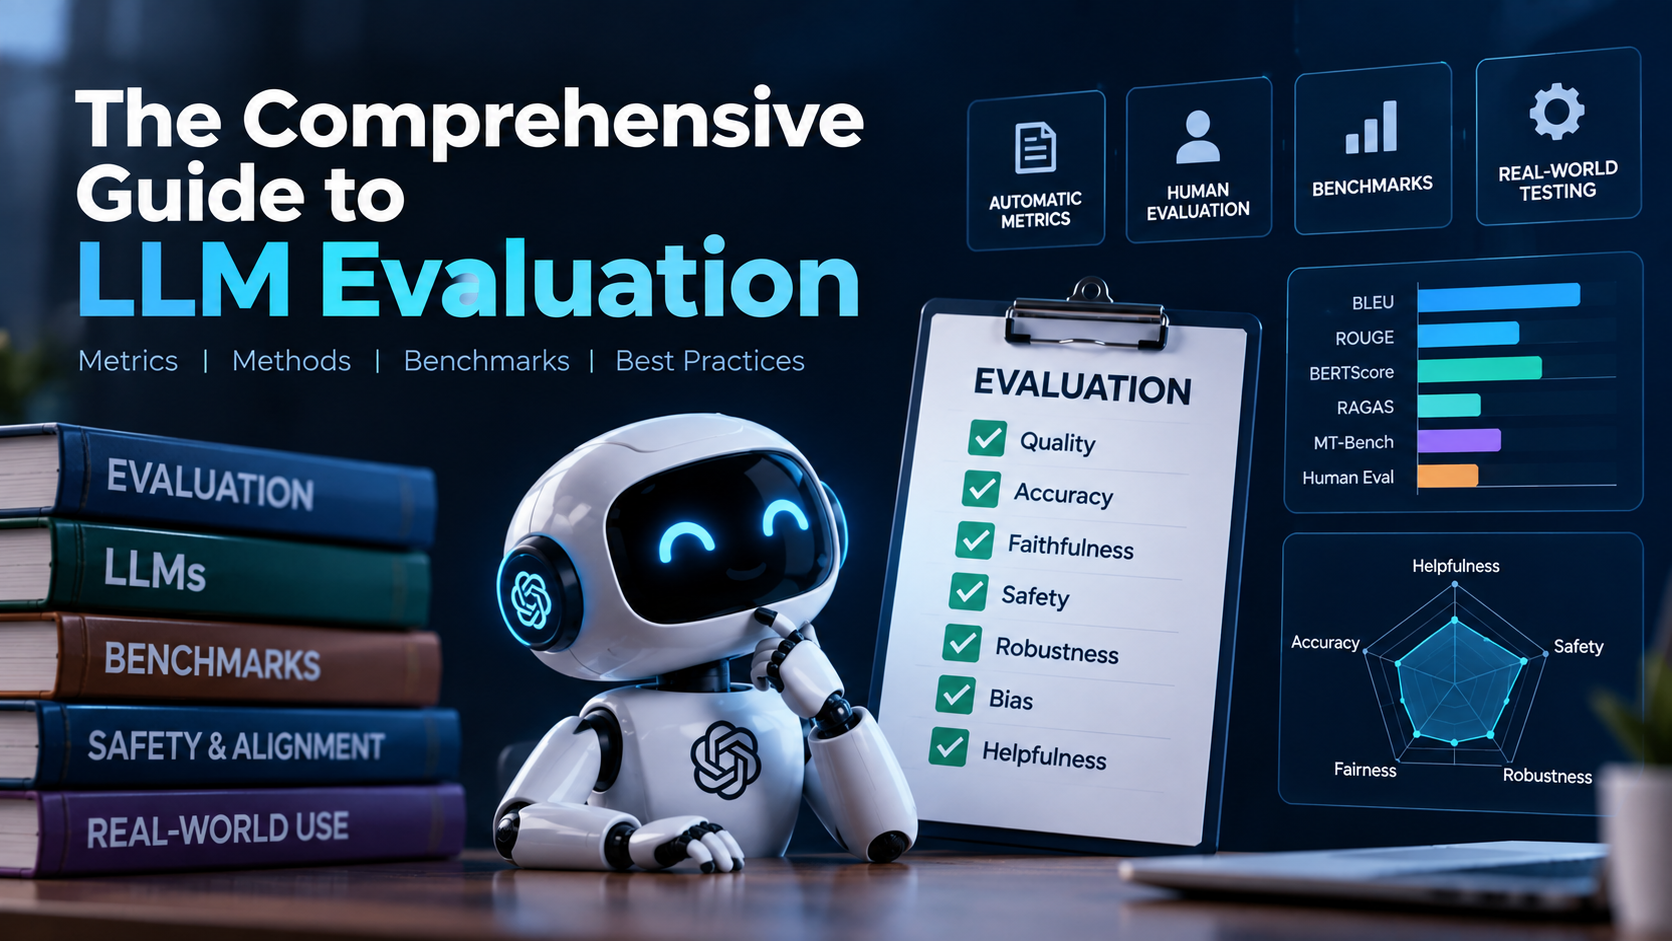
The Comprehensive Guide to LLM Evaluation
The four kinds of evaluation, which metric fits which task, and how to assemble a suite you will still be running in…
-
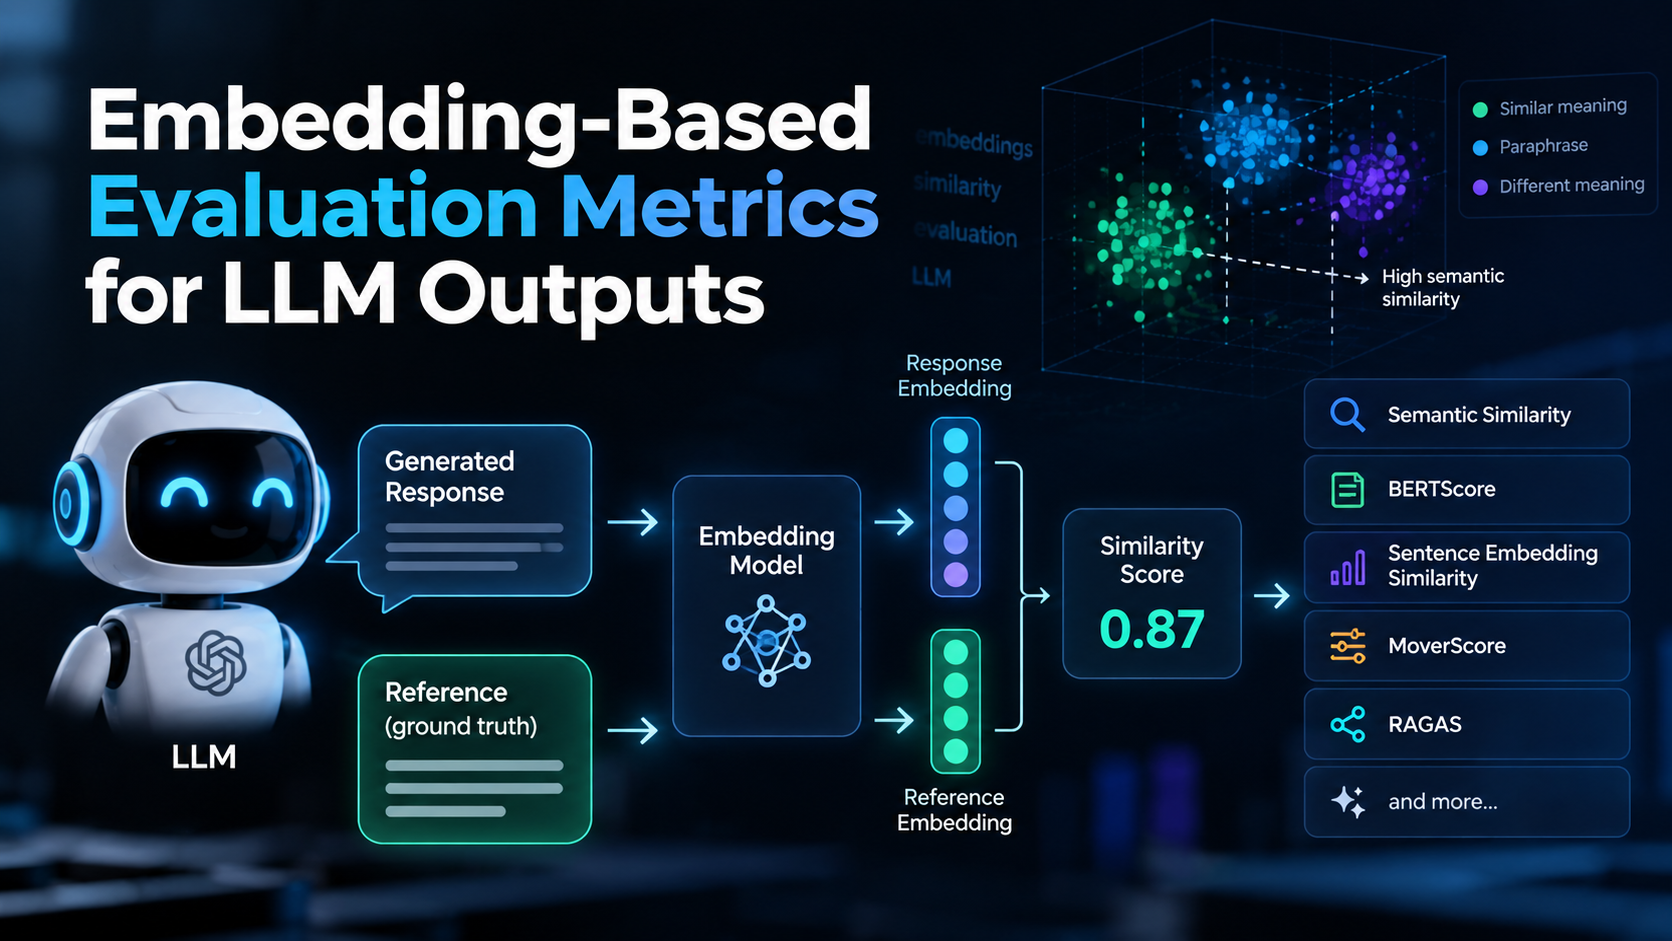
Embedding-Based Evaluation Metrics for LLM Outputs
Two sentences can share no words and mean the same thing. Embedding metrics close part of that gap – and quietly mislead…
Trending Now
- Mistral AI Codestral pricing vs Claude 3.5 Sonnet coding adoption
- Lambda Labs GPU cloud and NVIDIA H100 clusters
- Runway Gen-4 vs Pika Labs 2.0: Comparing AI video models
- Poolside engineers use the $3B coding model to automate software development
- Posit releases version 2026.11.0 for data science workflows