
Cerebras
-
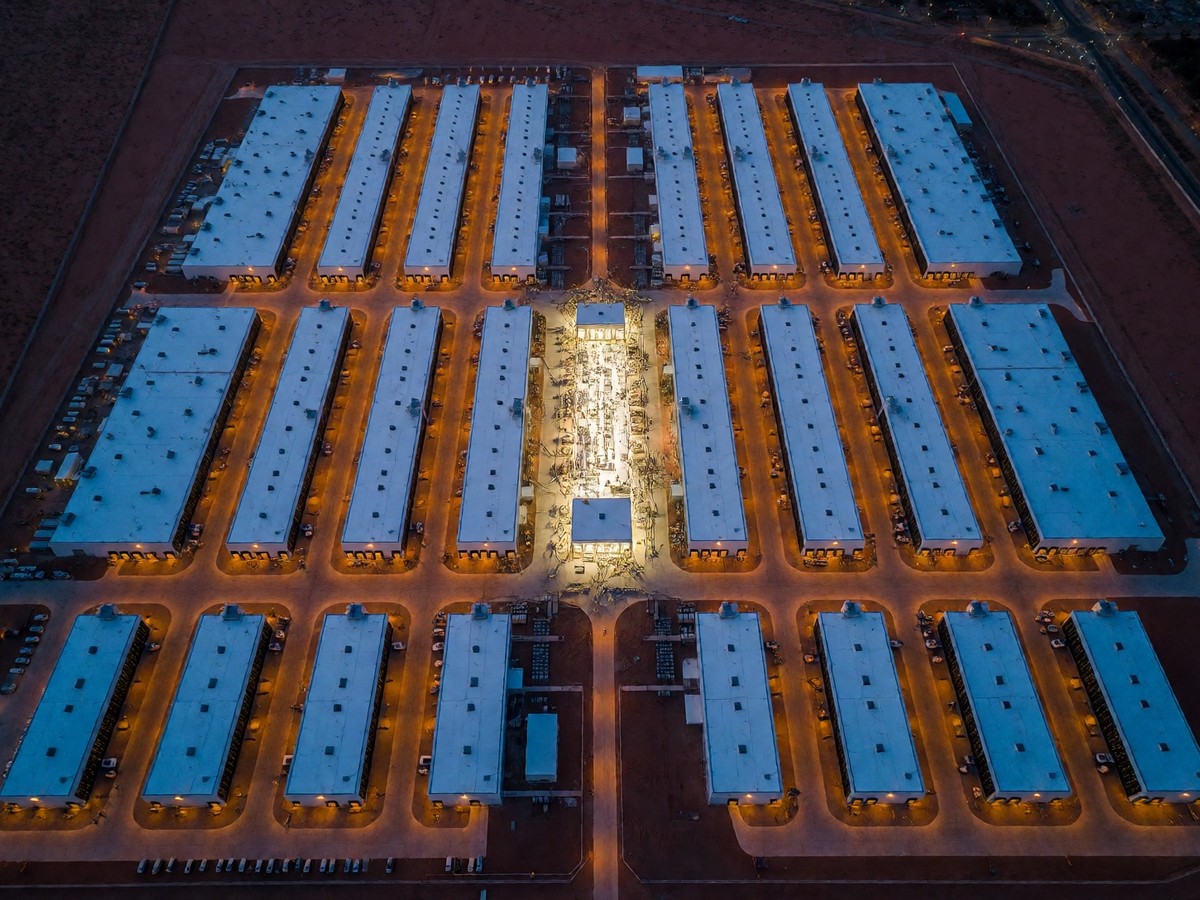
Cerebras CS-3 clusters scale AI inference and training
Cerebras CS-3 systems deliver 125 peak AI petaflops using the Wafer Scale Engine 3 with 900,000 AI cores. Cloud services revenue grew…
-
Cerebras Systems history from wafer-scale startup to AI training challenger
Cerebras Systems evolved from a 2015 startup into a major AI hardware provider by developing wafer-scale processors. The company raised $5.55 billion…
-
Common Mistakes with Cerebras CS-3 and PyTorch Distributed Training
Cerebras CS-3 wafer-scale clusters often underperform due to incorrect PyTorch wrapping and ignored mixed precision settings. A 70B model checkpoint requires 980…
-
SambaNova DataScale SN30R vs Cerebras Wafer-Scale Pricing
SambaNova’s DataScale SN30R offers a modular alternative to Cerebras’ wafer-scale systems for enterprise LLM fine-tuning.
-
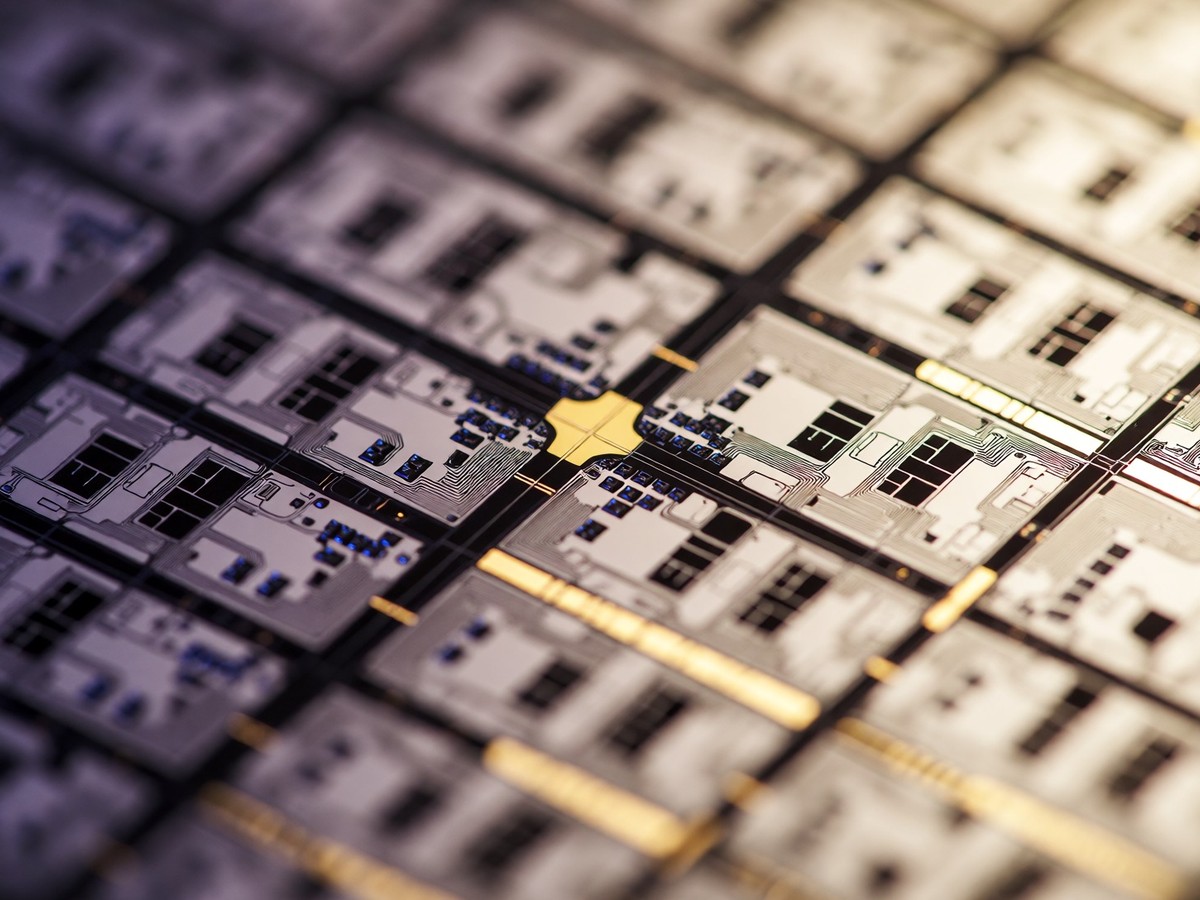
Why Cerebras’s wafer-scale chips matter now for AI data center independence
Cerebras’s WSE-3 chip uses a 300mm wafer as a single processor to deliver 21 PB/s memory bandwidth, solving the memory wall for…
-
Financial and structural hurdles for Cerebras wafer-scale deployment
Cerebras Systems faces significant manufacturing dependencies on TSMC and high capital requirements to support its $7.92 billion cash reserve. While the CS-4…
-
Yield advantage and packaging limits in wafer-scale AI
Cerebras achieves 93% silicon utilization on its WSE-3 wafer-scale chip through advanced defect tolerance. However, massive 23 kW power draws and TSMC…
-

Cerebras WSE-3 vs SambaNova SN40L performance comparison
Cerebras runs Moonshot AI’s Kimi 2.6 trillion-parameter model at 981 tokens per second, outperforming the next-best GPU cloud provider by 6.7x. The…
-
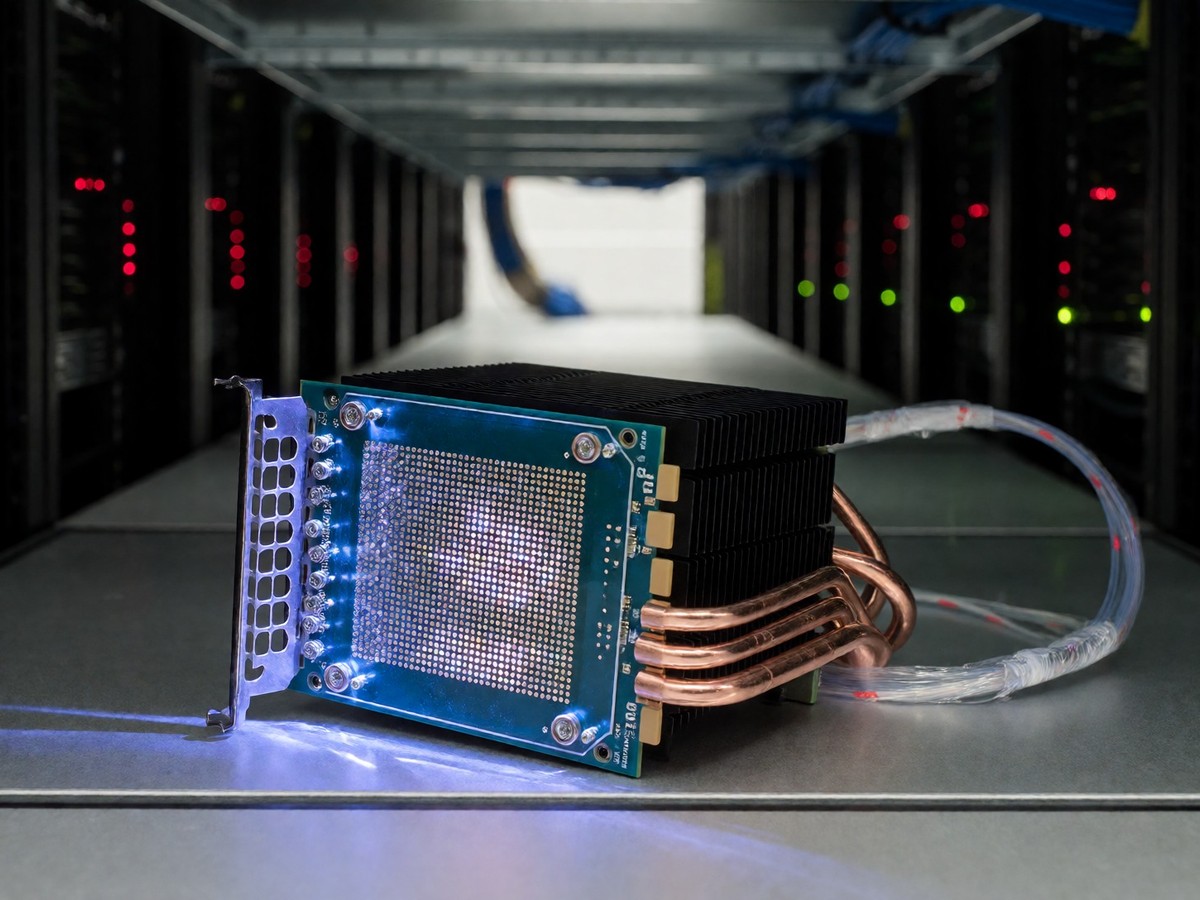
The risks in Cerebras’ WSE-3 rollout
Cerebras faces significant market volatility after OpenAI chose NVIDIA GPUs for its GPT-6.1 Sol Ultrafast mode, causing Cerebras stock to drop nearly…
-
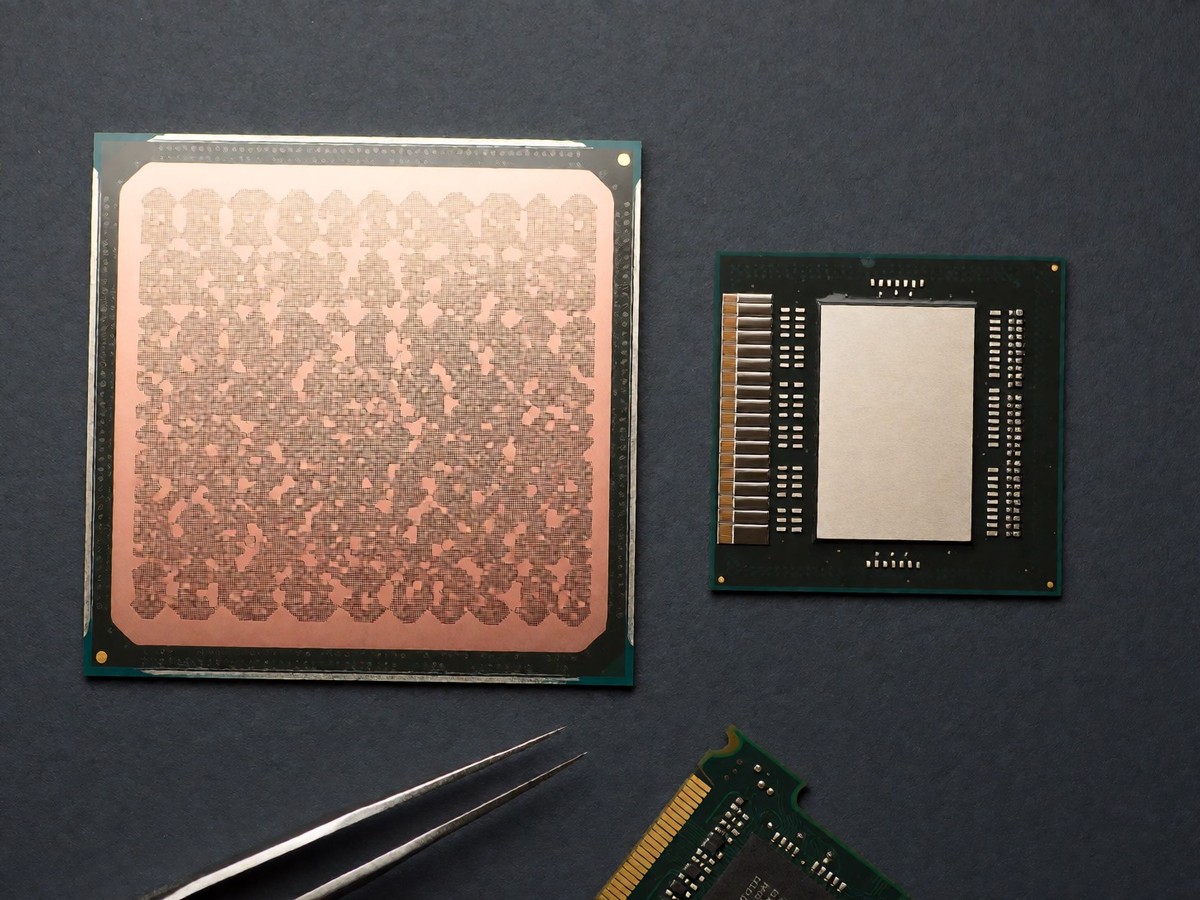
Cerebras CS-3 vs SambaNova DataScale SN40L comparison
Cerebras generates 4,400 tokens per second on the GPT-OSS 120B model using a single CS-4 rack, significantly outperforming SambaNova’s 708 tokens per…
-
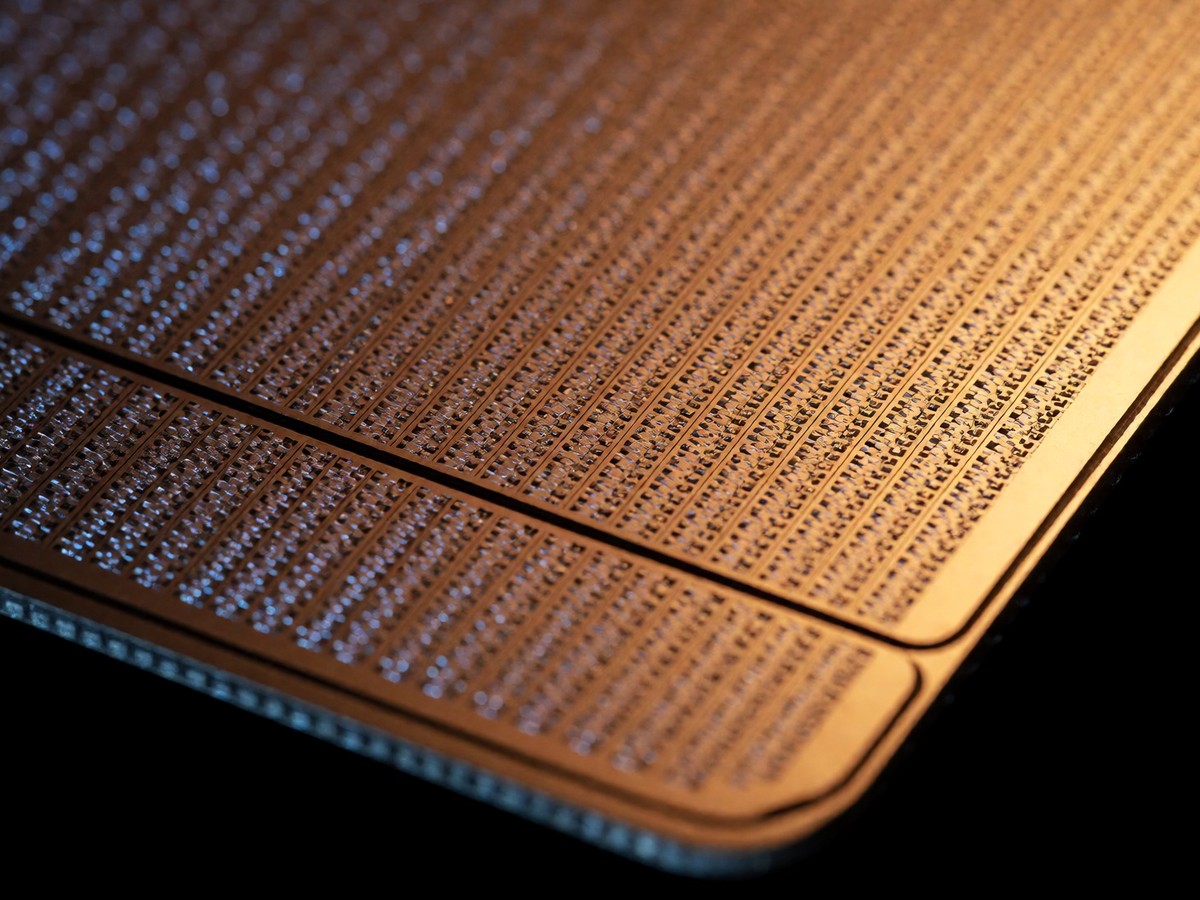
The Cerebras CS-3 delivers 2,500 tokens per second for Llama 4 Maverick
Cerebras CS-3 delivers Llama 4 Maverick inference at 2,500 tokens per second per user, significantly outperforming the NVIDIA DGX B200. The WSE-3…
-
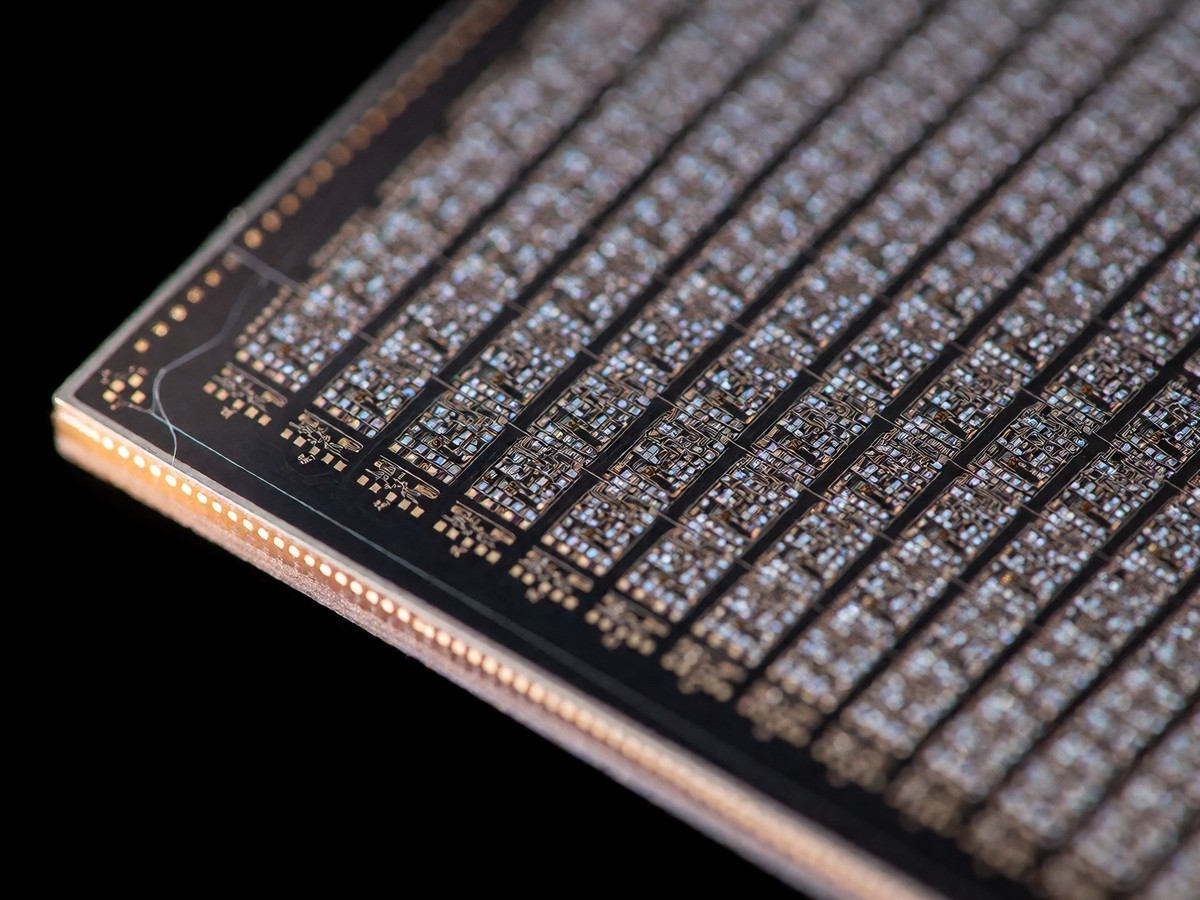
Cerebras undercuts GPU tokens through wafer-scale speed
Cerebras Inference delivers Llama 3.1 70B at 446 tokens per second for $0.6 per 1M tokens, significantly outperforming H100 clusters. The company’s…