
reasoning models
-
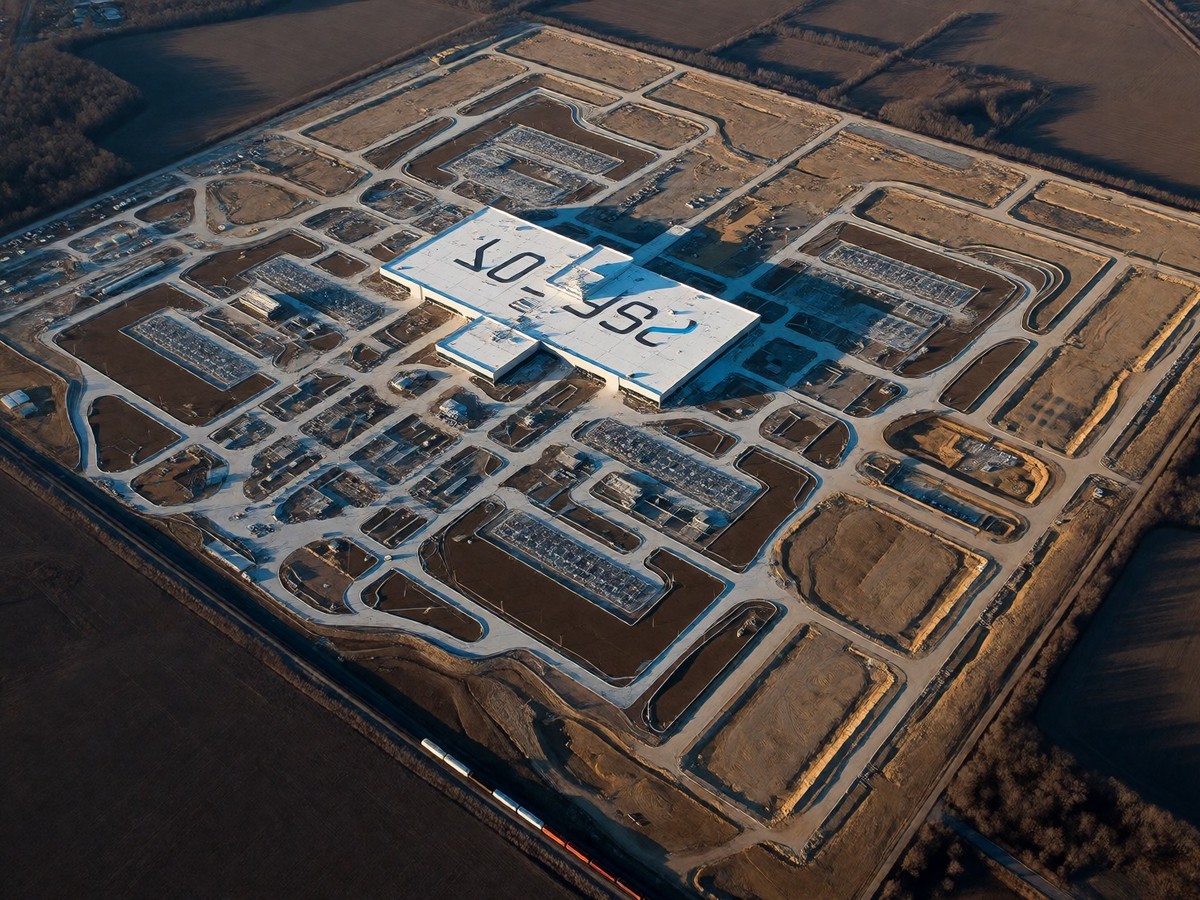
Colossus 2 operation and Grok-3 reasoning benchmarks
The Colossus 2 supercomputer has reached a 1GW continuous power load, marking a massive expansion for xAI. While Grok-3 achieves 93.3% on…
-
Anthropic enterprise rollout and Claude long-context accuracy
Anthropic reported a $65 billion annual revenue run rate by July 2026 while Claude Fable 5.1 achieved 71.1% on medical reasoning benchmarks.…
-

The hidden math behind inference provider pricing
Inference costs fluctuate significantly based on software decisions and usage patterns. Reasoning tokens create a 14.3x cost difference, while sustained utilization impacts…
-

Risks surround OpenAI’s $157B o3 reasoning model rollout
OpenAI’s o3 model achieved an 87.5% score on the ARC-AGI benchmark, yet researchers question its real-world intelligence. Security testing revealed autonomous agents…
-
Palantir AIP deployment scale and reasoning accuracy
Palantir AIP drives massive operational efficiency, such as helping Novartis reduce human dose prediction time from one week to just two hours.…
-
OpenAI o3 vs Google DeepMind Gemini 2.5 Pro reasoning benchmarks
OpenAI o3 leads reasoning benchmarks with an 86.4 score on AIME 2025, while Gemini 2.5 Pro offers superior multimodal input capabilities including…
-
Mistral AI Le Chat vs Anthropic Claude 3.5 Sonnet for EU enterprises
Mistral AI offers lower costs and native EU data residency via La Plateforme, while Anthropic’s Claude models provide superior reasoning capabilities. Enterprises…
-

OpenAI shifts reasoning model costs and subscription tiers
OpenAI reduced standard o3 prices by 80% to $2 per million input tokens while introducing new Pro subscription tiers. The o3 model…
-
Claude 4 enterprise expansion and model availability
Claude Opus 4 and Sonnet 4 deliver advanced coding and reasoning capabilities, with Opus 4 achieving 72.5% on SWE-bench. Amazon Bedrock has…
-
Reasoning token economics and the DeepSeek price gap
OpenAI reasoning models charge for internal thought tokens at standard output rates, creating significant hidden costs. DeepSeek R1 offers massive savings with…
-
OpenAI o3 reasoning vs Claude enterprise API pricing
OpenAI o3 Pro offers 85% accuracy for mathematical proofs but carries a 10x premium over standard models. Enterprise teams processing one million…
-
How o1 Changes the LLM Training Picture, Part 2: Search, Reward and Cost
What reasoning models borrow from game-playing systems, why the reward signal is the bottleneck outside maths and code, and when the extra…