
SambaNova
-
SambaNova on-premise LLM deployment and edge inference
SambaNova’s SN40L chip supports models up to 5 trillion parameters and sequence lengths exceeding 256k tokens. The hardware stack integrates Reconfigurable Dataflow…
-
SambaNova scales deployment through Intel and Supermicro
SambaNova is expanding its infrastructure footprint through partnerships with Intel and Supermicro, delivering the SN50 RDU which offers a 3x throughput advantage…
-
Common mistakes with SambaNova SN40L RDU memory and PyTorch DDP
SambaNova SN40L RDUs use a three-tier memory system and streaming dataflow to achieve 688 FP16 Tflop/s for training. Developers must avoid placing…
-
SambaNova vs Groq: Enterprise LLM Inference at Scale
SambaNova hosts the 405-billion-parameter Llama-3.1 model at over 100 tokens per second, a capacity Groq cannot match due to its 230 MB…
-
SambaNova DataScale SN30R vs Cerebras Wafer-Scale Pricing
SambaNova’s DataScale SN30R offers a modular alternative to Cerebras’ wafer-scale systems for enterprise LLM fine-tuning.
-
SambaNova valuation reaches $11 billion as enterprise AI shifts
SambaNova reached an $11 billion valuation following a $1 billion Series F round to support its Reconfigurable Dataflow Unit architecture. The SN40L…
-

Cerebras WSE-3 vs SambaNova SN40L performance comparison
Cerebras runs Moonshot AI’s Kimi 2.6 trillion-parameter model at 981 tokens per second, outperforming the next-best GPU cloud provider by 6.7x. The…
-
SambaNova RDU scaling and composition-of-experts
SambaNova’s SN40L RDU achieves 132 tokens per second for Llama 3.1 405B while consuming only 10KW per rack. This power-efficient architecture uses…
-
Memory Exhaustion and Communication Bottlenecks in Llama 3.1 405B
Llama 3.1 405B requires 810 GB of memory for FP16 precision, necessitating distribution across multiple SambaNova SN40L RDUs. Improper sharding in feedforward…
-
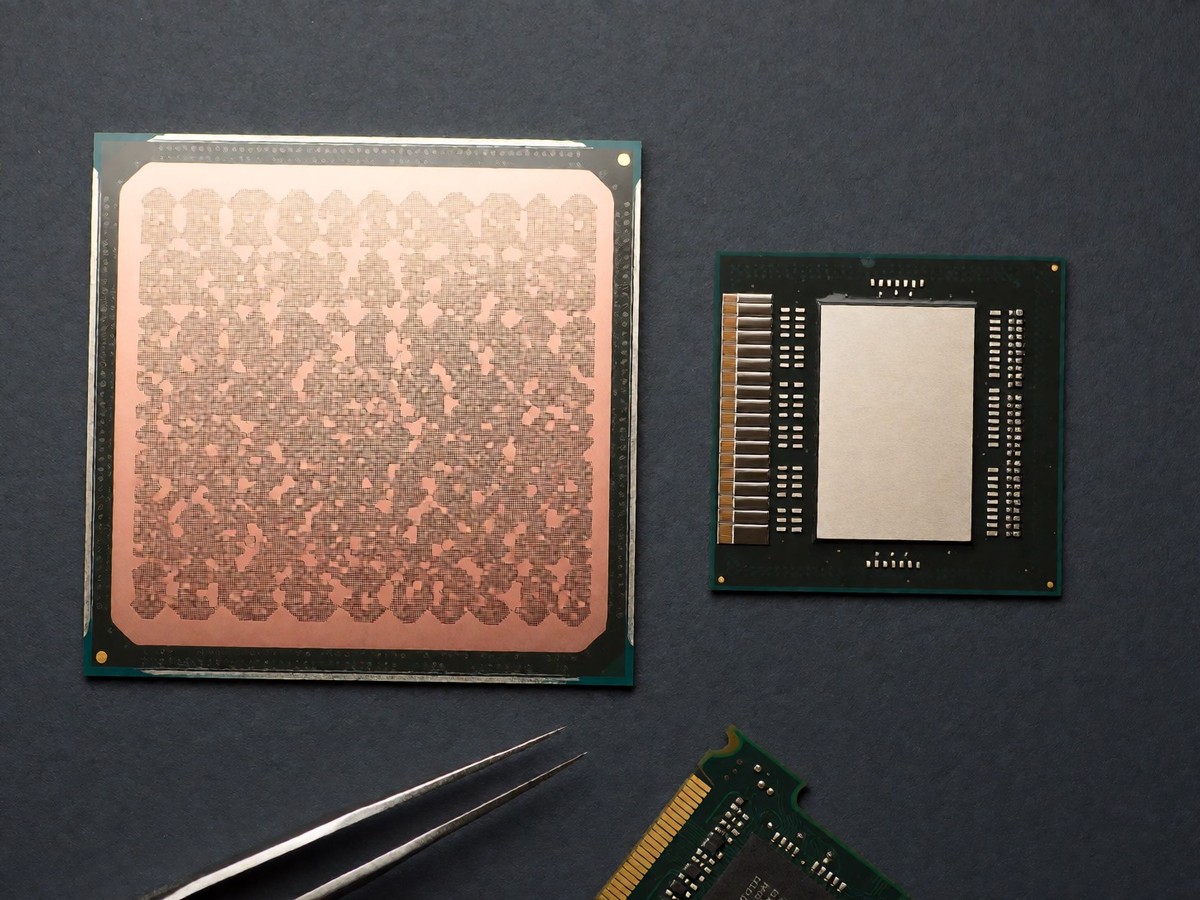
Cerebras CS-3 vs SambaNova DataScale SN40L comparison
Cerebras generates 4,400 tokens per second on the GPT-OSS 120B model using a single CS-4 rack, significantly outperforming SambaNova’s 708 tokens per…
-
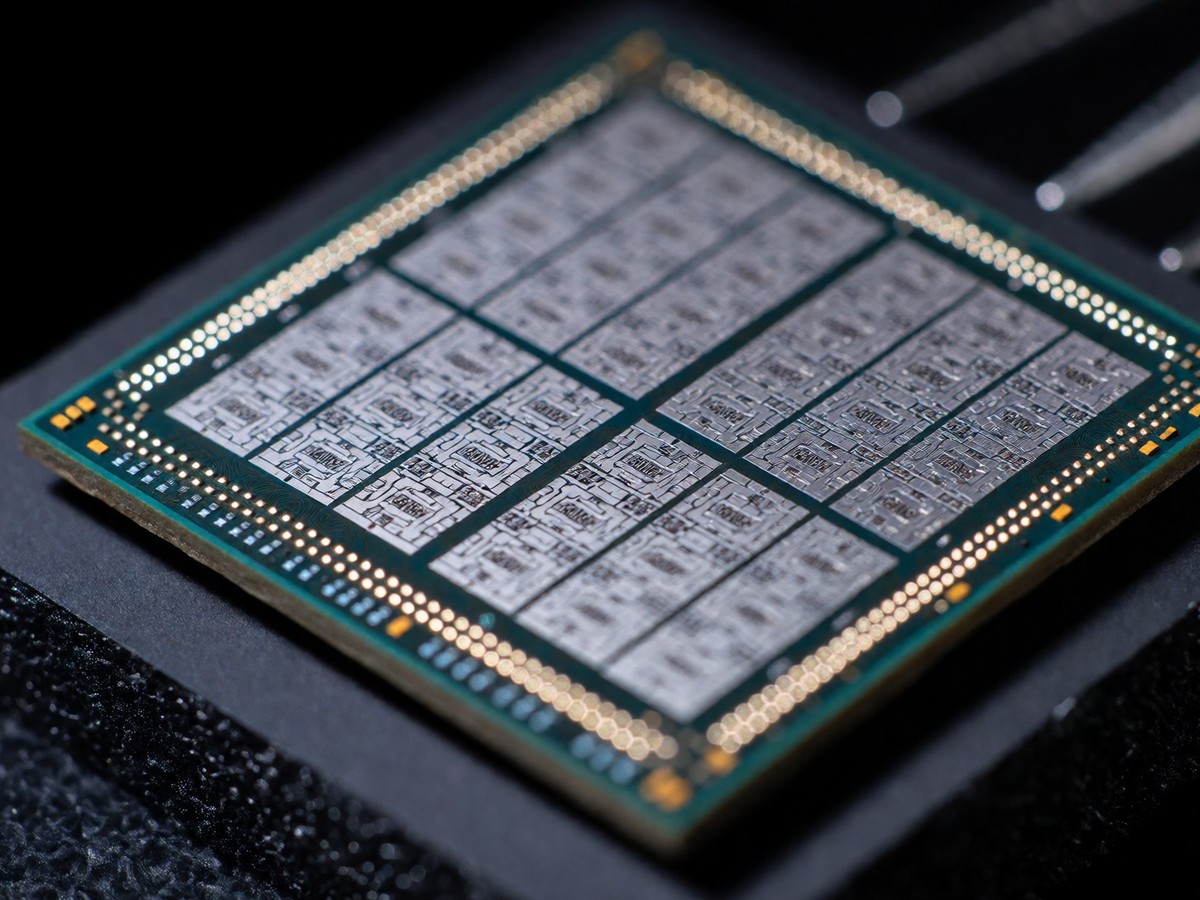
Deploying Llama 3.2 90B Vision on SambaNova SN40L
SambaNova’s SN40L RDU provides enterprise infrastructure for Llama 3.2 90B Vision, delivering a 3.7x speedup over the DGX H100. The hardware uses…
-
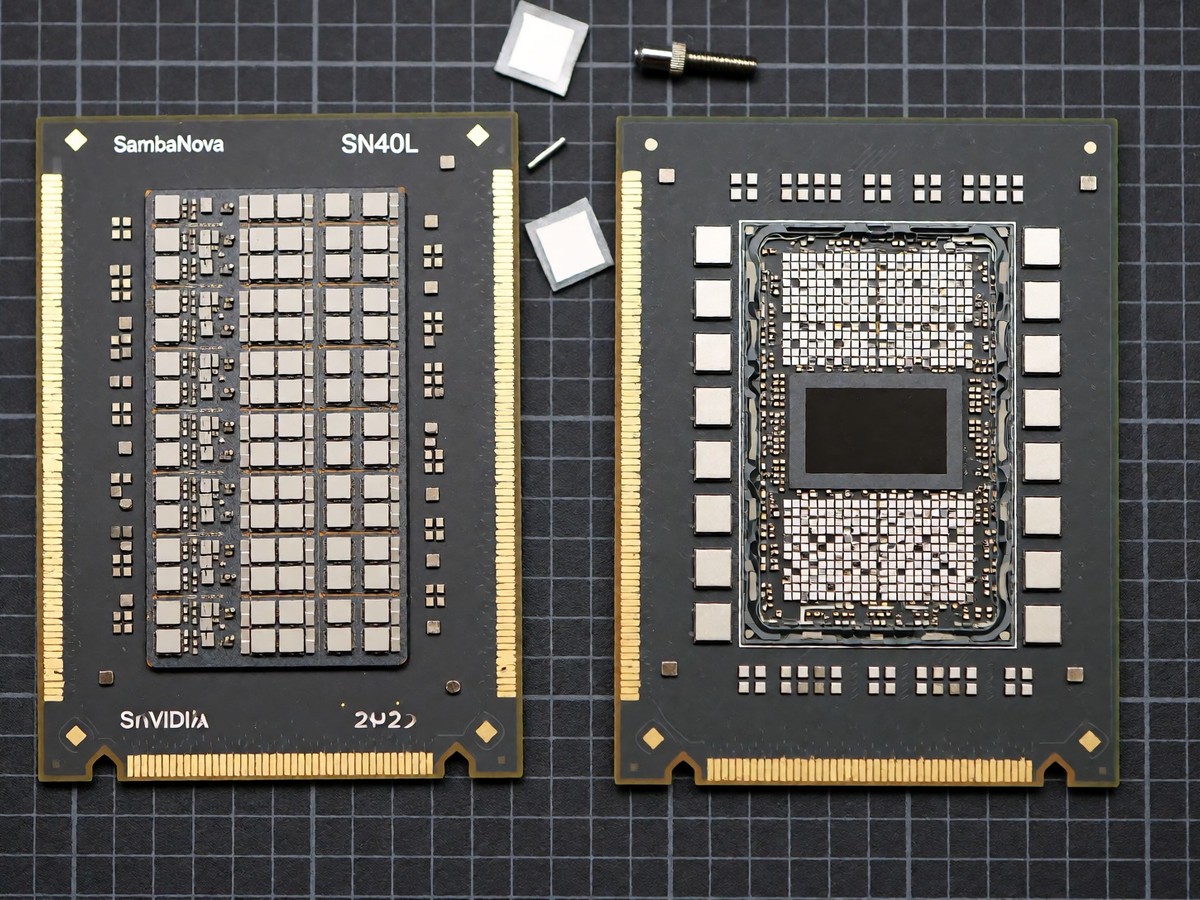
Why the SambaNova SN40L RDU beats the NVIDIA H200 on inference economics
SambaNova’s SN40L RDU delivers 9x greater performance and 5.6x more energy efficiency than the NVIDIA H200 for Llama 3.3 70B at low…