
Latest stories
-
The reality of AI news errors
A study by the European Broadcasting Union and BBC found that 81% of AI news responses contained errors, with sourcing failures accounting…
-
Character.AI financial reality and the Disney bid
Character.AI faces a monthly deficit of up to $9 million as compute costs outpace revenue. Disney has submitted a $20 million stalking…
-
Adept AI reaches $1 billion valuation as Salesforce expands workflows
Adept AI achieved a $1 billion valuation following a $350 million Series B round led by General Catalyst. Meanwhile, Salesforce expanded its…
-
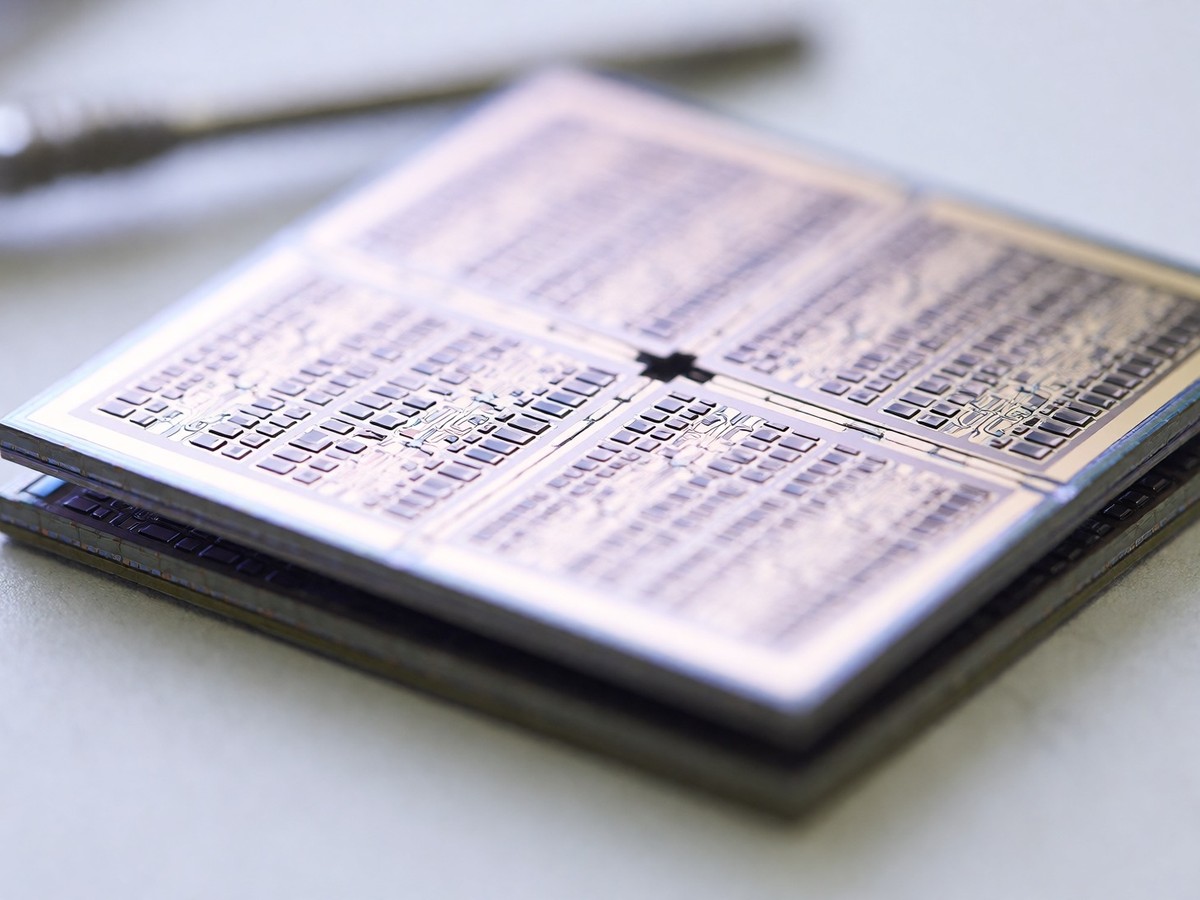
Graphcore Bow IPU: The 350W push against NVIDIA dominance
Graphcore’s Bow IPU utilizes wafer-on-wafer technology to deliver 350 trillion floating point per second of AI arithmetic. The BOW POD-16 offers a…
-
Stability AI faces leadership fragmentation and a compute-to-revenue cliff
Stability AI struggles with a massive 9:1 compute-to-revenue gap and leadership instability following Emad Mostaque’s resignation. The company faces $300M in future…
-
The economic scale of AI infrastructure and research resources
AI infrastructure costs for a 1 GW compound reach between $60 billion and $80 billion, according to Jensen Huang. The National Science…
-
Mojo and the MAX engine bring AI performance to Apple M4 Max
Mojo achieves speeds 35,000 times faster than Python on Mandelbrot set benchmarks by providing direct control over memory and SIMD operations. The…
-
Deploying Mistral AI Codestral 22B on Azure AI Foundry
Azure AI Foundry provides Serverless API and managed compute paths for deploying Mistral AI’s Codestral 22B. This 22B parameter model achieves an…
-
The economics of Scale AI’s $13.8B data labeling empire
Scale AI reached a $14 billion valuation as the data labeling market grew to $6.12 billion in 2026. AI companies face unique…
-
Lambda capitalizes on debt markets as CoreWeave faces earnings pressure
Lambda secured a $1.008 billion senior secured loan to fund GPU infrastructure while CoreWeave reported a second-quarter adjusted loss of 27 cents…
-
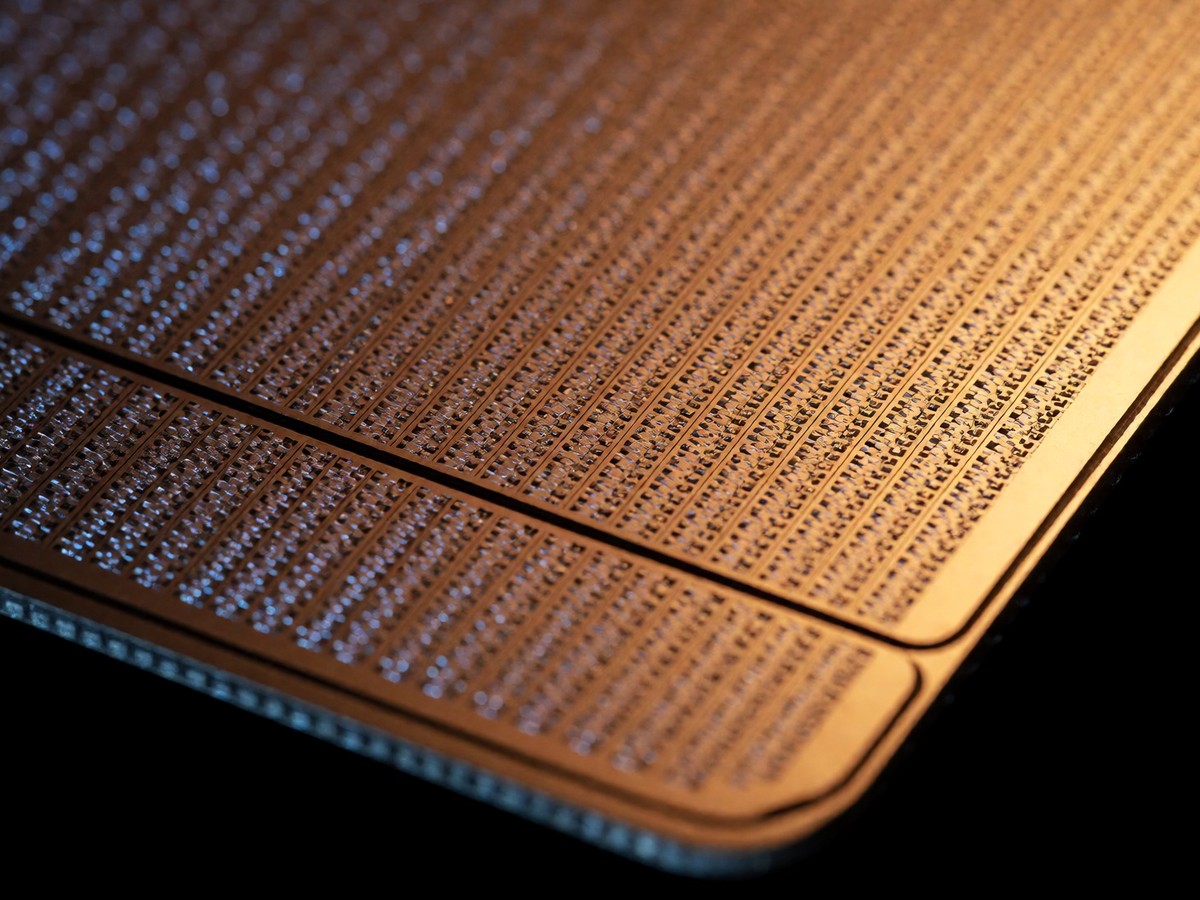
The Cerebras CS-3 delivers 2,500 tokens per second for Llama 4 Maverick
Cerebras CS-3 delivers Llama 4 Maverick inference at 2,500 tokens per second per user, significantly outperforming the NVIDIA DGX B200. The WSE-3…
-
Tesla FSD v13 hardware barriers and the sensor safety debate
Tesla’s FSD v13 rollout requires Hardware 4 vehicles to utilize the Cortex GPU cluster for high-resolution video processing. Meanwhile, Waymo has completed…