
Latest stories
-
Positron AI scales inference infrastructure with Asimov chip
Positron AI secured $875 million to scale its Asimov photonic AI chip, which offers 3.5x better performance per dollar than Nvidia H100…
-
Databricks scales to $43B as DBRX rollout targets enterprises
Databricks reached a $43 billion valuation following a $500 million funding round led by T. Rowe Price. The company is expanding its…
-
Avoiding HBM bottlenecks in Gaudi 3 LLaMA 405B clusters
Intel Gaudi 3 provides 3.7 TB/s of HBM bandwidth, but failing to use dynamic memory allocation can cause a 20% drop in…
-
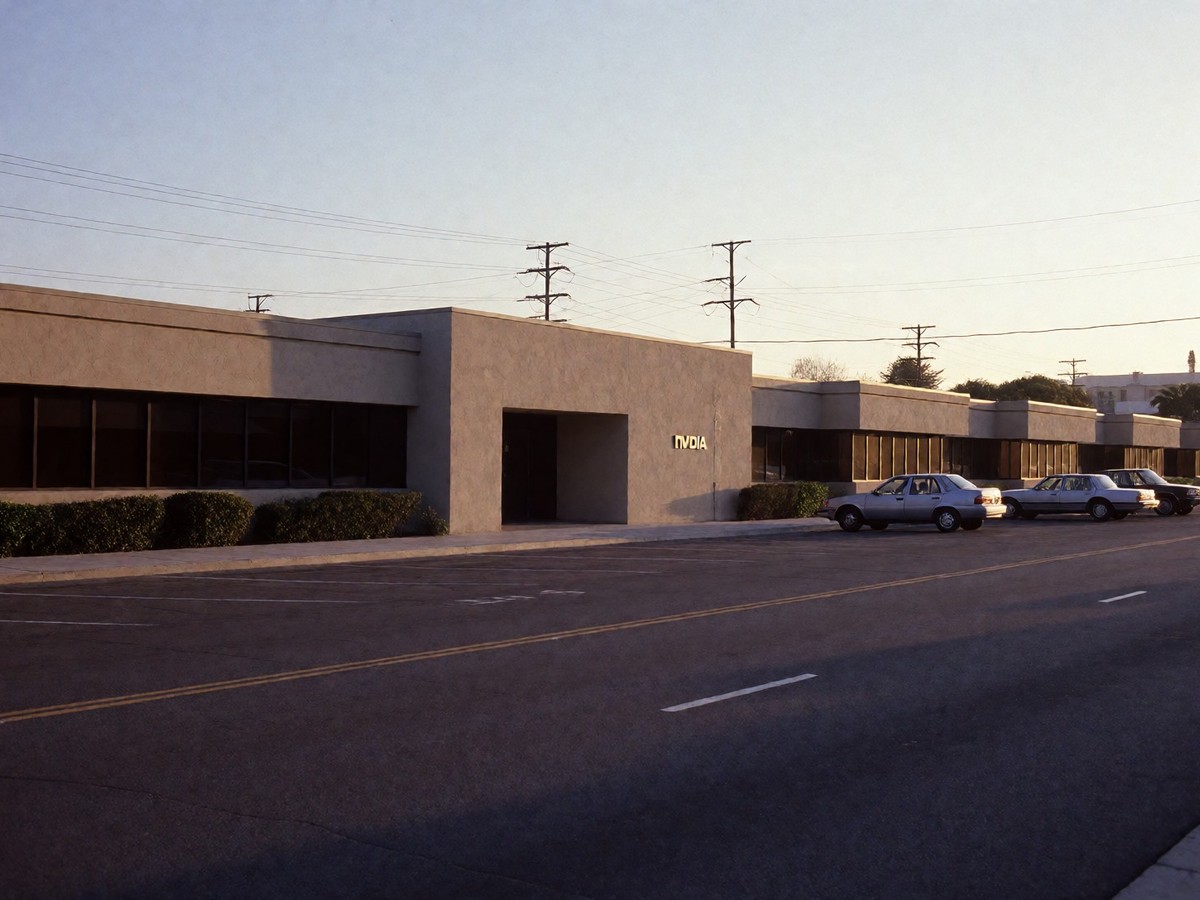
NVIDIA history from 1993 founding to the CUDA AI revolution
NVIDIA transitioned from a gaming chip manufacturer to an AI powerhouse following the 2006 launch of CUDA. This parallel computing platform enabled…
-
DeepL’s $2B Neural Engine Faces Google and Microsoft in API Market
DeepL’s proprietary neural network architecture outperformed Google Translate in professional evaluations, producing only 10 errors compared to 25. The company is now…
-
Groq’s inference growth and Meta’s Llama 4 deployment
Groq’s Language Processing Unit delivers over 750 tokens per second on Llama 3 70B by utilizing on-chip SRAM to bypass memory bottlenecks.…
-
Deploying Llama 3.2 90B Vision on SambaNova SN40L
SambaNova’s SN40L RDU provides enterprise infrastructure for Llama 3.2 90B Vision, delivering a 3.7x speedup over the DGX H100. The hardware uses…
-
The hardware economics of Tenstorrent Blackhole AI chips
Tenstorrent Galaxy Blackhole systems achieve $6 per million tokens for DeepSeek R1 671B, significantly undercutting NVIDIA’s implied $30 per million token cost.…
-
Anthropic financial and safety exposure after Amazon deal
Anthropic faces a $42 billion net loss for 2025 and significant safety risks after the UK AI Safety Institute found autonomous agents…
-
Metis delivers high throughput for edge vision
Axelera AI’s Metis platform utilizes a quad-core RISC-V architecture and Digital In-Memory Computing to achieve 15 TOPS/W at INT8 precision. The hardware…
-

OpenAI shifts reasoning model costs and subscription tiers
OpenAI reduced standard o3 prices by 80% to $2 per million input tokens while introducing new Pro subscription tiers. The o3 model…
-
Cerebras undercuts GPU tokens through wafer-scale speed
Cerebras Inference delivers Llama 3.1 70B at 446 tokens per second for $0.6 per 1M tokens, significantly outperforming H100 clusters. The company’s…