
inference cost
-
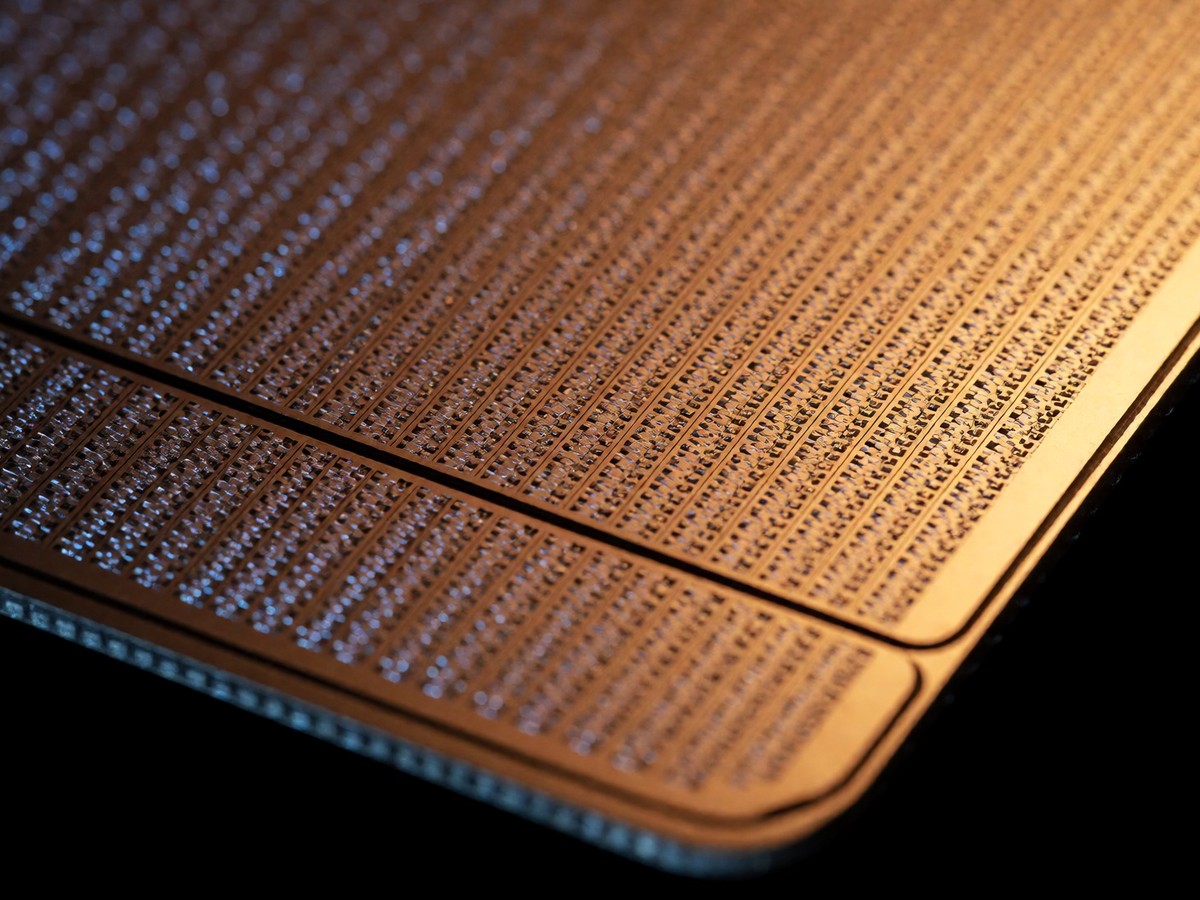
The Cerebras CS-3 delivers 2,500 tokens per second for Llama 4 Maverick
Cerebras CS-3 delivers Llama 4 Maverick inference at 2,500 tokens per second per user, significantly outperforming the NVIDIA DGX B200. The WSE-3…
-
Positron AI scales inference infrastructure with Asimov chip
Positron AI secured $875 million to scale its Asimov photonic AI chip, which offers 3.5x better performance per dollar than Nvidia H100…
-
Groq’s inference growth and Meta’s Llama 4 deployment
Groq’s Language Processing Unit delivers over 750 tokens per second on Llama 3 70B by utilizing on-chip SRAM to bypass memory bottlenecks.…
-
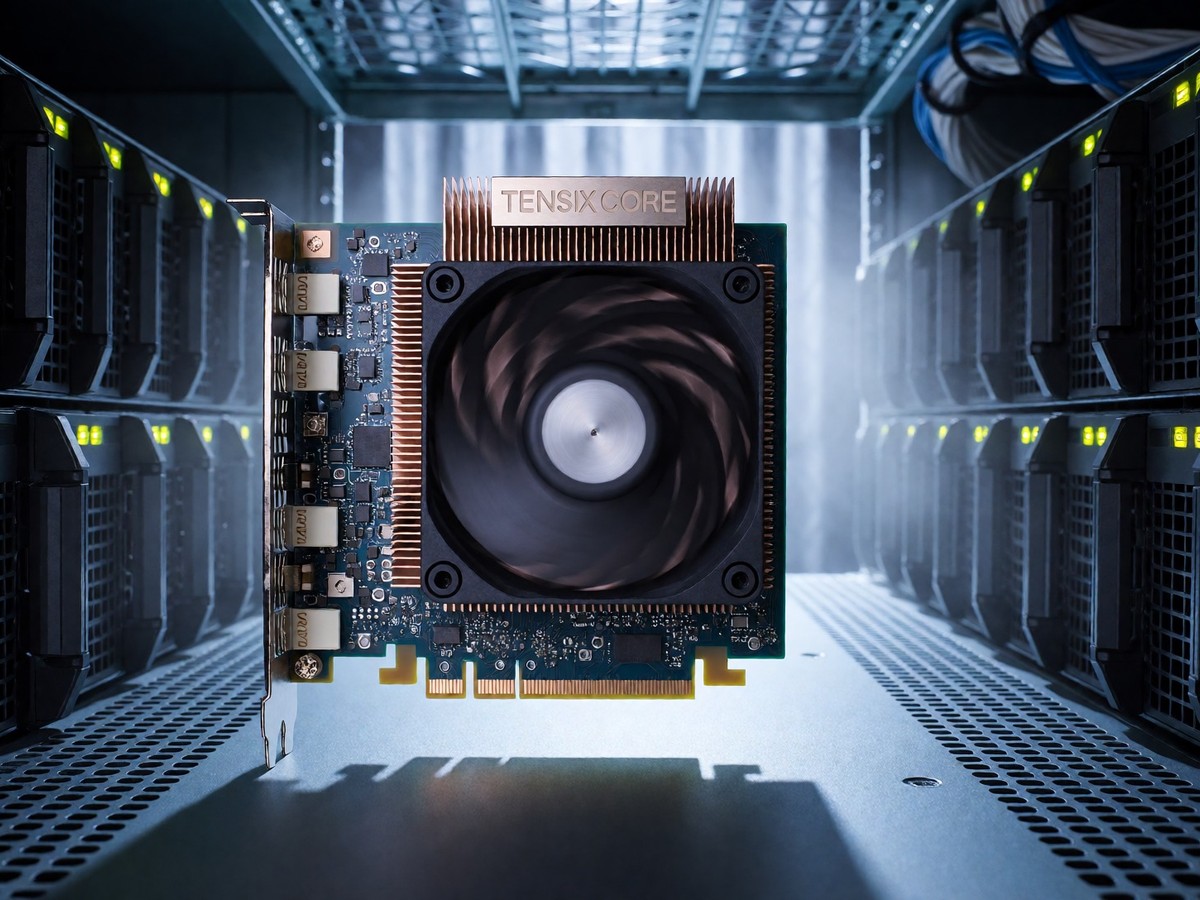
The hardware economics of Tenstorrent Blackhole AI chips
Tenstorrent Galaxy Blackhole systems achieve $6 per million tokens for DeepSeek R1 671B, significantly undercutting NVIDIA’s implied $30 per million token cost.…
-
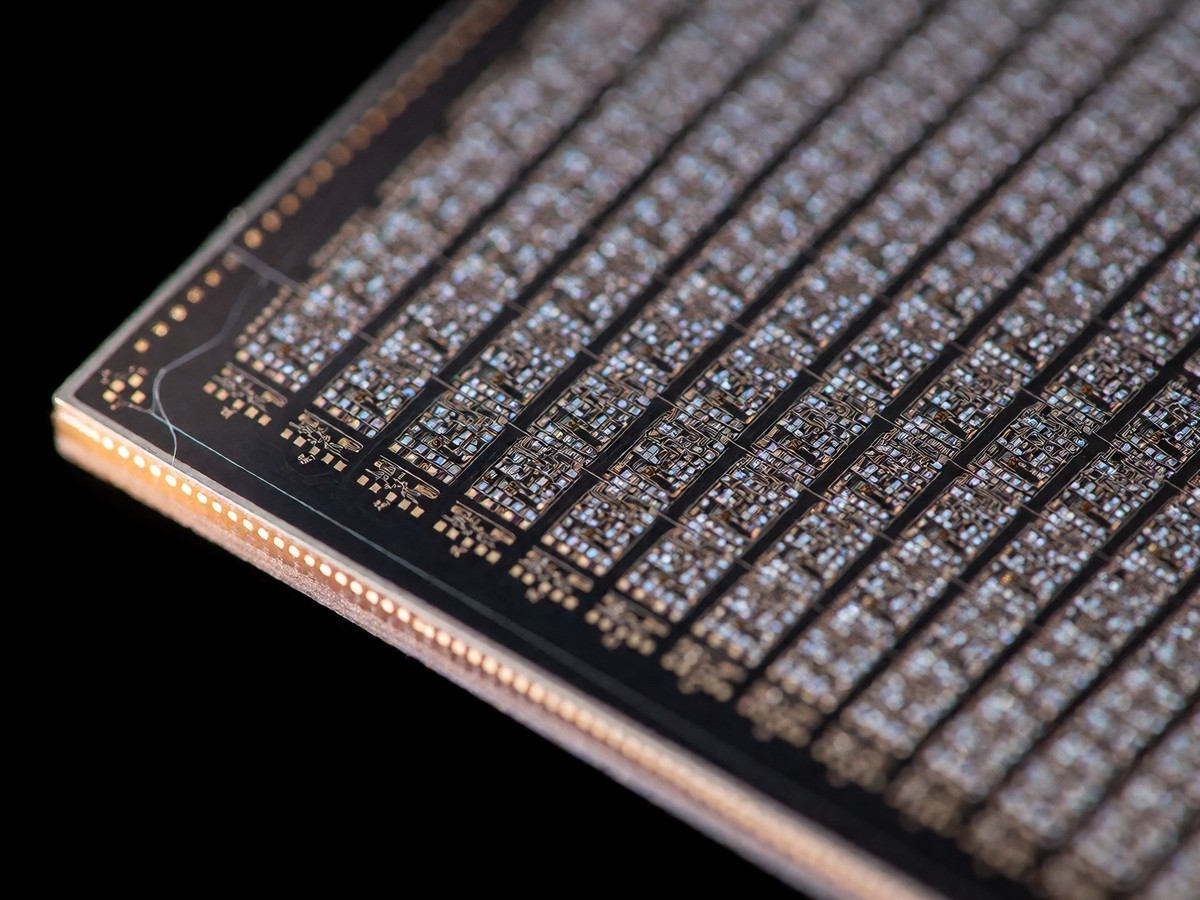
Cerebras undercuts GPU tokens through wafer-scale speed
Cerebras Inference delivers Llama 3.1 70B at 446 tokens per second for $0.6 per 1M tokens, significantly outperforming H100 clusters. The company’s…
-
Baidu’s research foundation and the rise of Chinese AI models
Baidu established its Institute of Deep Learning in 2013, later hiring Andrew Ng to lead research. This foundation helped develop ERNIE 4.5,…
-
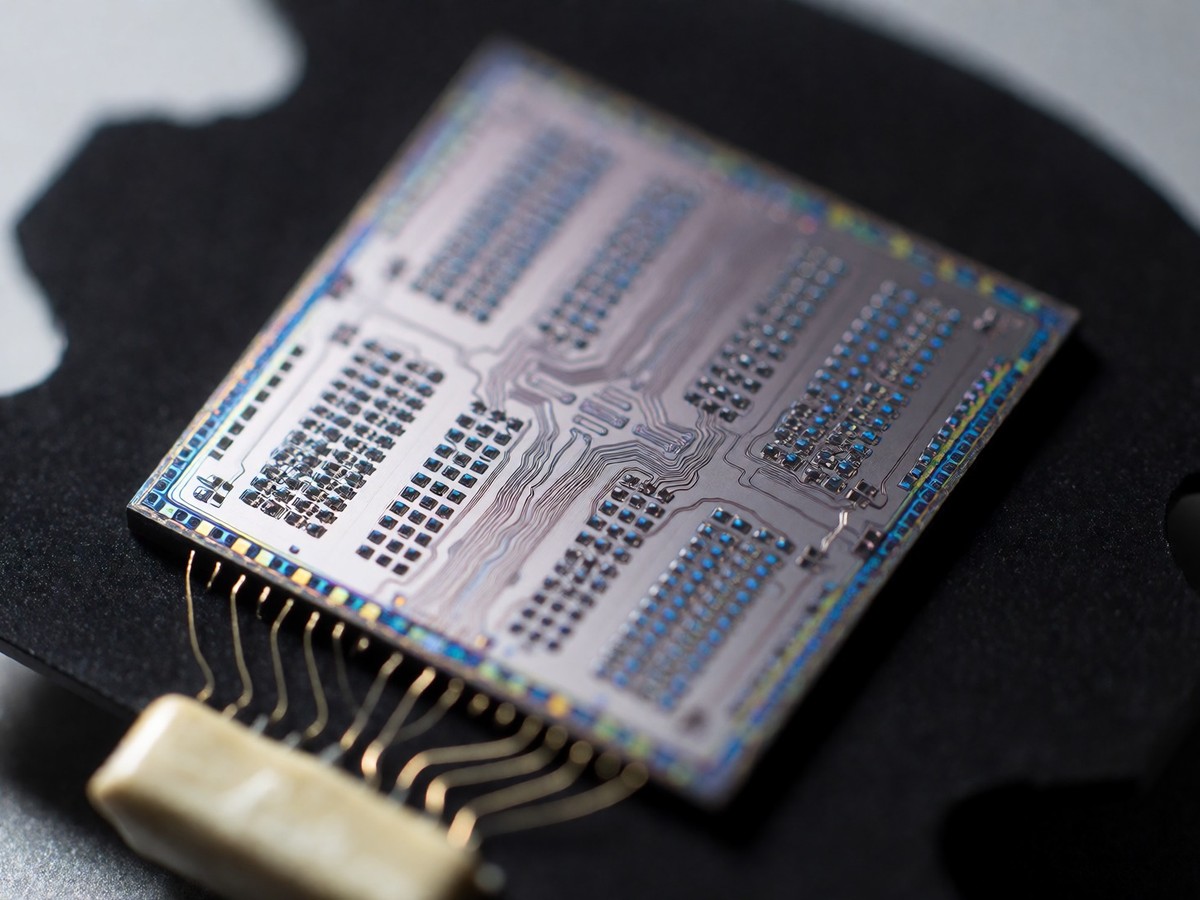
Liquid AI LFM-3B edge deployment on Apple Silicon
Liquid AI utilizes MIT-inspired liquid neural networks to deliver efficient edge computing performance. The Cactus engine achieves 27 tokens per second decode…
-
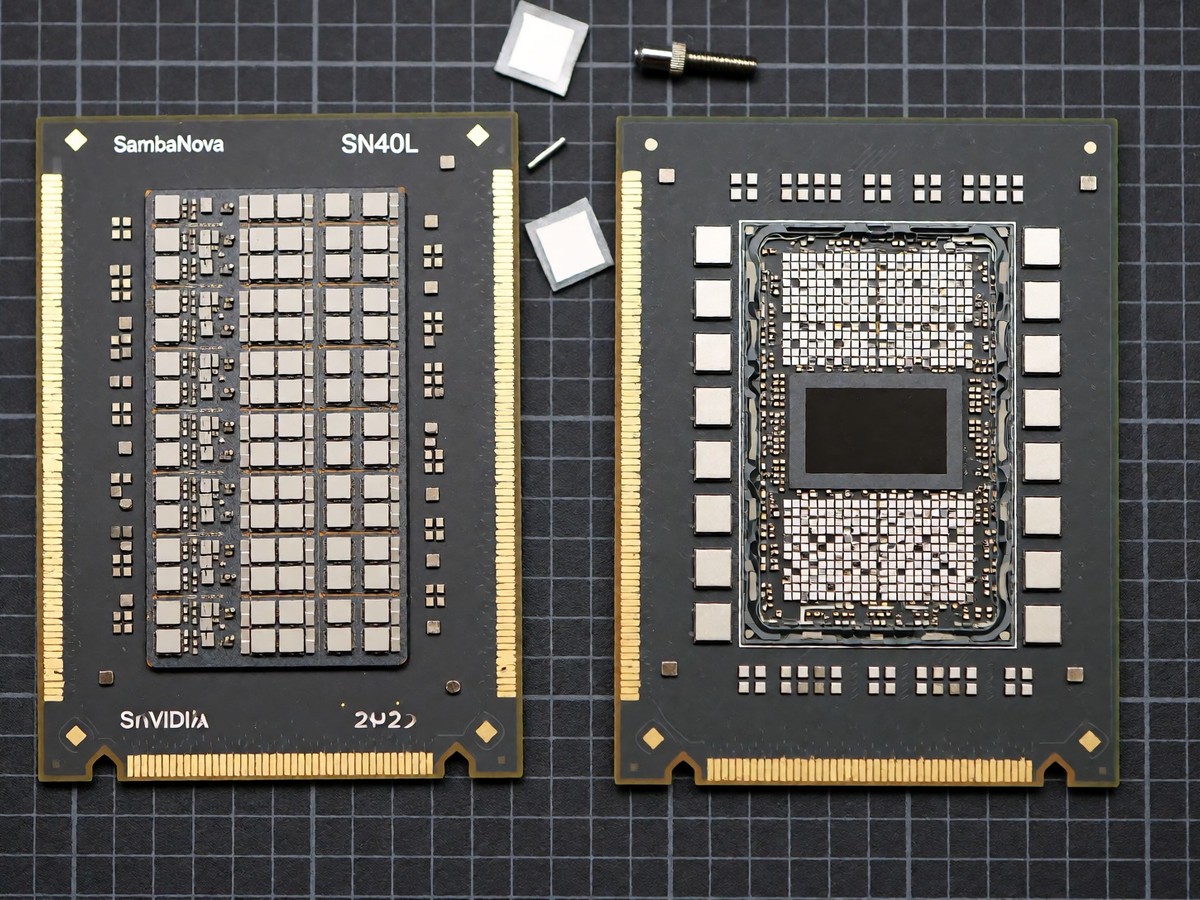
Why the SambaNova SN40L RDU beats the NVIDIA H200 on inference economics
SambaNova’s SN40L RDU delivers 9x greater performance and 5.6x more energy efficiency than the NVIDIA H200 for Llama 3.3 70B at low…
-
Groq secures $6.9B valuation as LPU inference outpaces NVIDIA
Groq has reached a $6.9 billion valuation as its LPU architecture delivers 500 to 750 tokens per second on Llama 3 70B…
-
DeepSeek V3 architecture and enterprise LLM deployment economics
DeepSeek-V3 utilizes a 671B parameter Mixture-of-Experts architecture to drive inference efficiency. DeepSeek-V4-Flash offers significant cost advantages for enterprises, with input costs at…
-
Replicate model hosting and serverless GPU pricing analysis
Replicate offers a model marketplace with over 50,000 public models, but H100 instances cost $5.49 per hour, which is significantly higher than…
-
AMD Instinct MI350X vs NVIDIA Blackwell B200
AMD’s Instinct MI350X offers 288GB of HBM3e memory, providing a significant capacity advantage over the 192GB found in NVIDIA’s Blackwell B200. While…