
inference cost
-
Reasoning token economics and the DeepSeek price gap
OpenAI reasoning models charge for internal thought tokens at standard output rates, creating significant hidden costs. DeepSeek R1 offers massive savings with…
-
d-Matrix moves Corsair into production to meet AI inference demand
d-Matrix has launched its Corsair inference accelerator platform to support massive AI workloads, delivering 30,000 tokens per second for Llama 70B models.…
-
SN40L performance and trillion-parameter expert scaling
SambaNova’s SN40L RDU node achieves a 3.7x speedup over DGX H100 when running 150 7B experts totaling over 1 trillion parameters. The…
-
DeepSeek’s efficiency advantage in Chinese enterprise cloud deployments
DeepSeek-V3 utilizes a Mixture-of-Experts architecture with 671 billion parameters to achieve high performance at a low cost. This design allows for a…
-
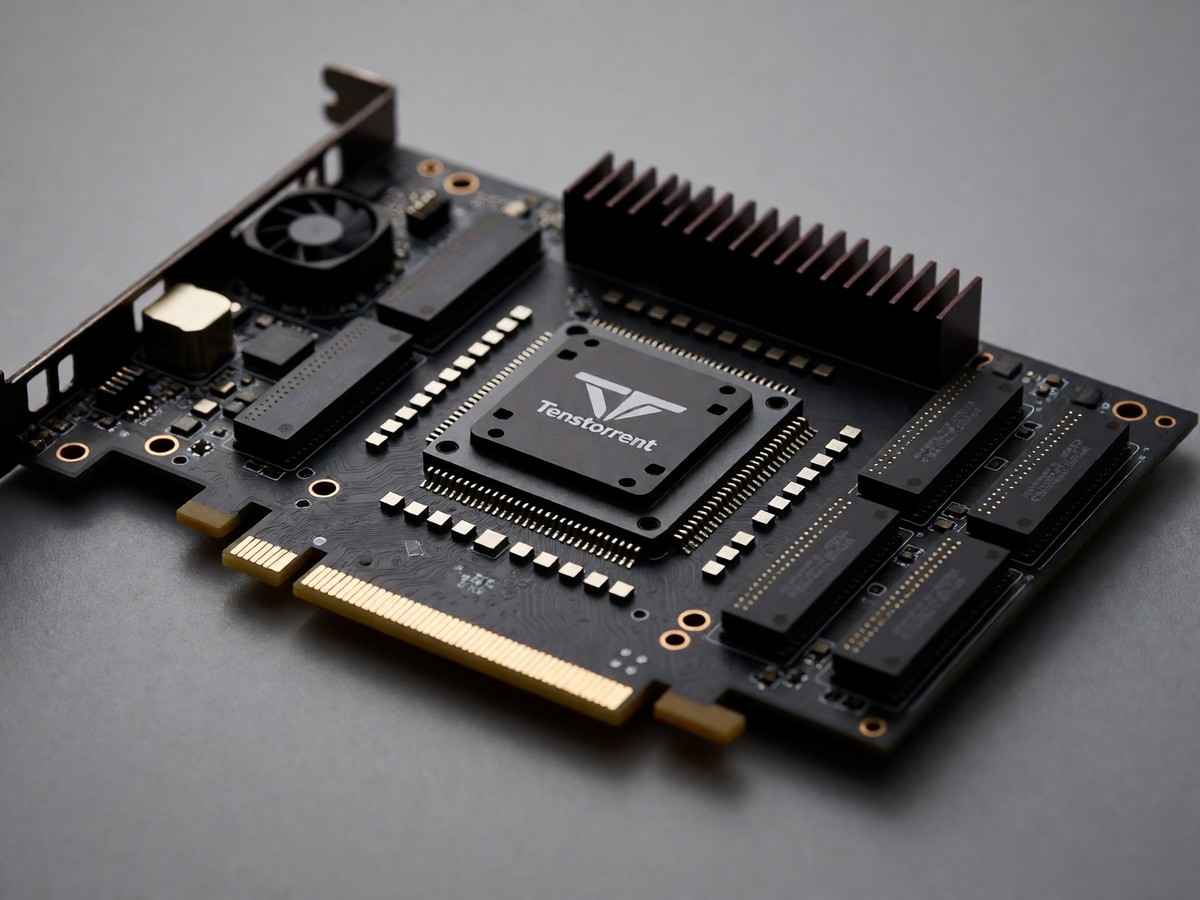
Tenstorrent Blackhole architecture and AI inference economics
Tenstorrent’s Blackhole architecture offers scalable AI inference for edge deployments, providing a cost-effective alternative to Nvidia hardware. Strategic investments from LG and…
-
OpenAI o3 reasoning vs Claude enterprise API pricing
OpenAI o3 Pro offers 85% accuracy for mathematical proofs but carries a 10x premium over standard models. Enterprise teams processing one million…
-
Scaling open source intelligence with Together AI and MoE
Together AI utilizes Mixture-of-Experts architecture and over 20 exaflops of compute power to offer cost-effective inference for over 450,000 users. The platform…
-
The economics of Physical Intelligence’s pi0 robot foundation model
Physical Intelligence’s pi0 model reduces new robot task application costs to $10,000, significantly undercutting traditional custom programming. This 3 billion parameter model…
-
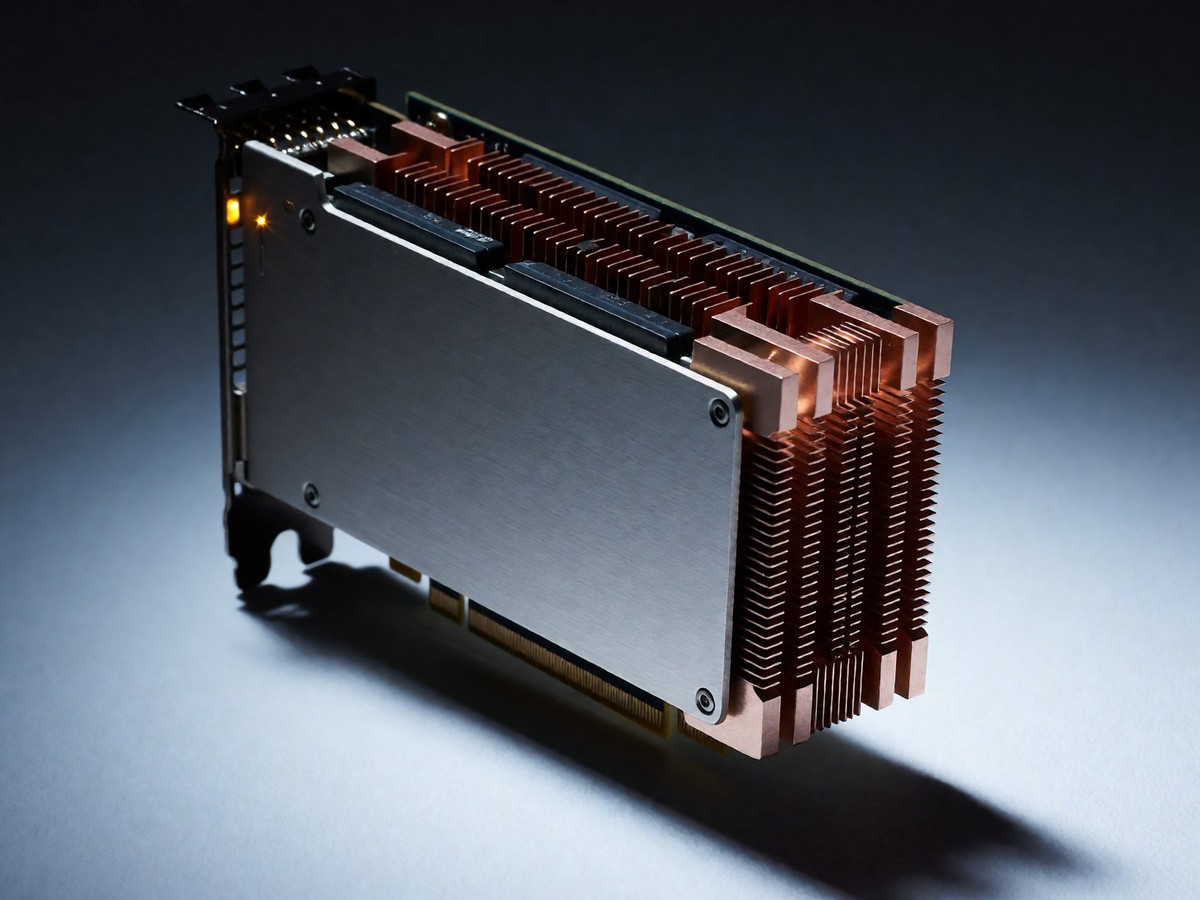
Enterprise context windows and the AI21 Jamba strategy
AI21 Labs utilizes a hybrid Mamba-Transformer architecture in its Jamba model family to provide efficient 256K token context windows. This design allows…
-

SmolVLM versus Phi-4-multimodal for on-device retail vision
SmolVLM-500M offers low-cost scanning for simple product labels on low-power hardware, while Phi-4-multimodal provides superior reasoning for complex invoices and math tasks.…
-

DeepSeek-V4-Pro architecture and the competitive coding frontier
DeepSeek-V4-Pro utilizes a Mixture-of-Experts architecture with 256 routed experts to achieve a 55.4 percent score on SWE-bench Pro. This model provides significant…
-
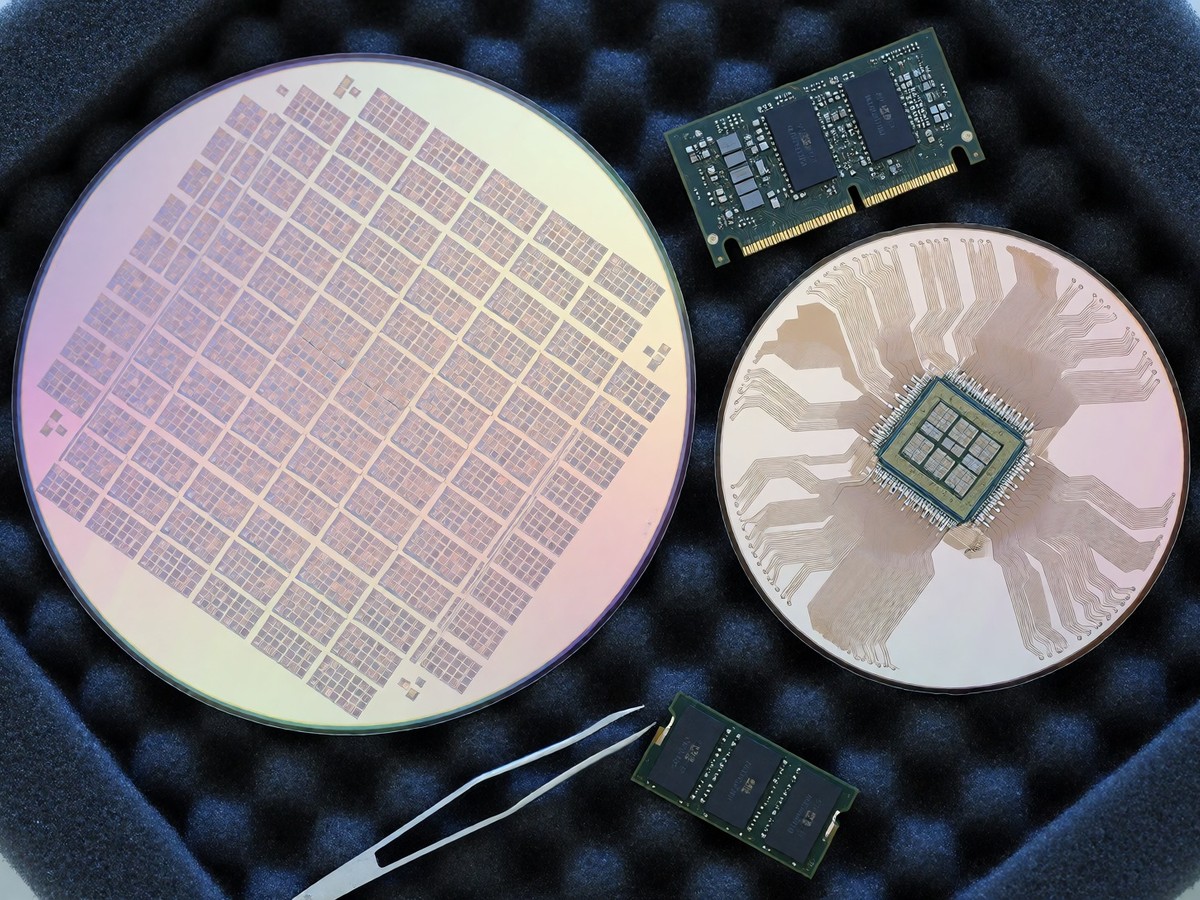
SambaNova SN50 vs Cerebras WSE-3 for large scale inference
SambaNova SN50 delivers 5x the maximum speed and 3x the throughput for agentic inference compared to Blackwell B200 GPUs. Cerebras WSE-3 provides…