
inference cost
-
How DeepSeek’s $14B V3 model changes LLM cost efficiency
DeepSeek-V3 training required only 2.788 million H800 GPU-hours costing $5.576 million, shifting the cost curve for enterprise AI. This efficiency impacts cloud…
-

The hidden math behind inference provider pricing
Inference costs fluctuate significantly based on software decisions and usage patterns. Reasoning tokens create a 14.3x cost difference, while sustained utilization impacts…
-
How to get started with Replicate’s model hosting and GPU inference
Replicate offers over 1,000 community models with Nvidia T4 compute at $0.000225 per second. Startups can evaluate various providers like Runware for…
-
The economics of token-based inference and AWS Trainium2
Together AI scales its inference platform with annual bookings exceeding $1.15 billion while offering competitive per-token pricing. AWS Trainium2 instances provide 30%…
-
Positron AI’s $5 billion valuation and the shift to LPDDR5X inference
Positron AI reached a $5 billion valuation following an $875 million funding round to develop its Asimov chip. The company’s Atlas system…
-
The economics of Groq’s LPU and the NVIDIA inference price war
Groq’s LPU architecture delivers 750 tokens per second for Llama 3.1 8B, providing 21x more value per dollar than NVIDIA H100 hosting.…
-
Perplexity shifts to modular API pricing after $9B valuation
Perplexity introduces a tiered API structure separating Search from generation, offering a Search API at $5 per 1,000 requests. This modular approach…
-
Tenstorrent Wormhole vs AMD MI300X: Sparse LLM Inference Comparison
Tenstorrent’s architecture offers superior scaling for sparse LLM inference by addressing memory and networking bottlenecks. Jim Keller claims his Galaxy servers can…
-
Character.AI financial reality and the Disney bid
Character.AI faces a monthly deficit of up to $9 million as compute costs outpace revenue. Disney has submitted a $20 million stalking…
-
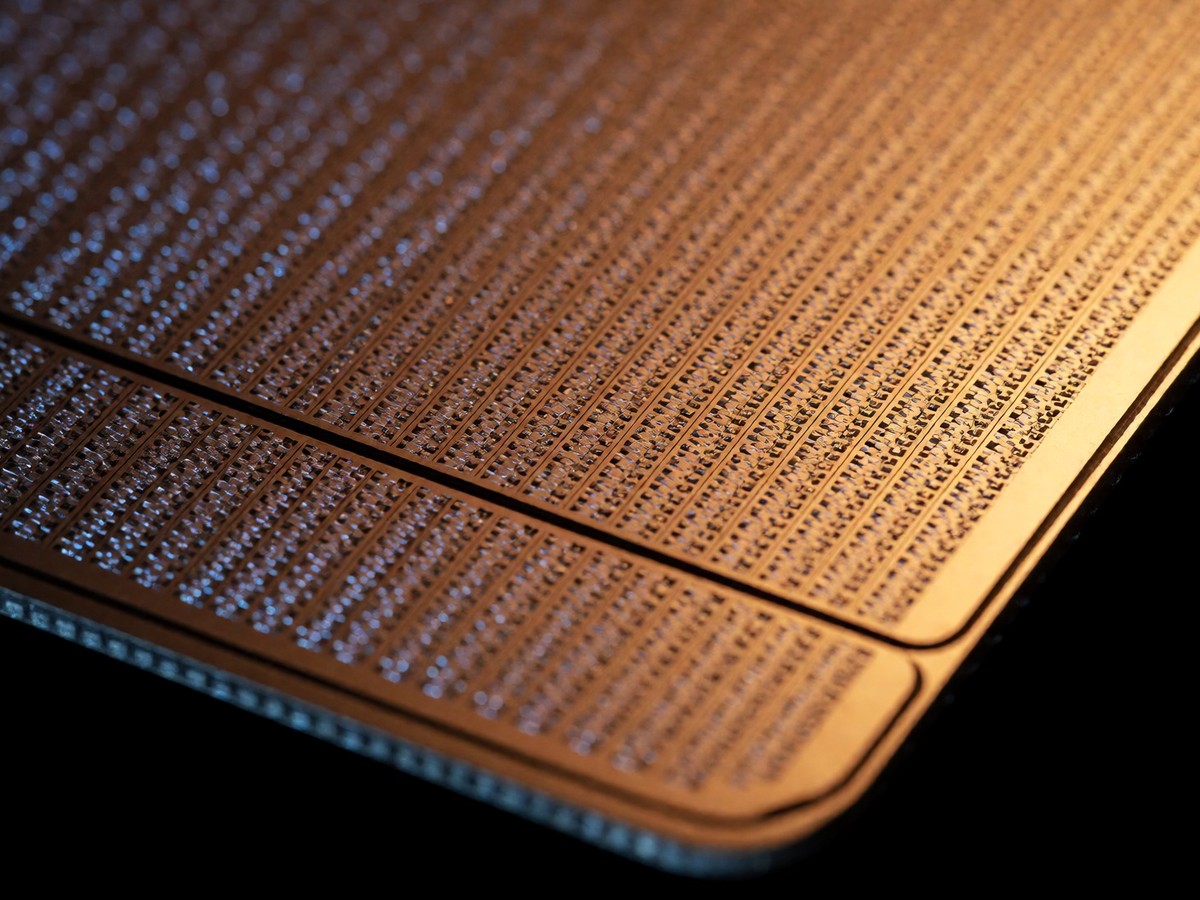
The Cerebras CS-3 delivers 2,500 tokens per second for Llama 4 Maverick
Cerebras CS-3 delivers Llama 4 Maverick inference at 2,500 tokens per second per user, significantly outperforming the NVIDIA DGX B200. The WSE-3…
-
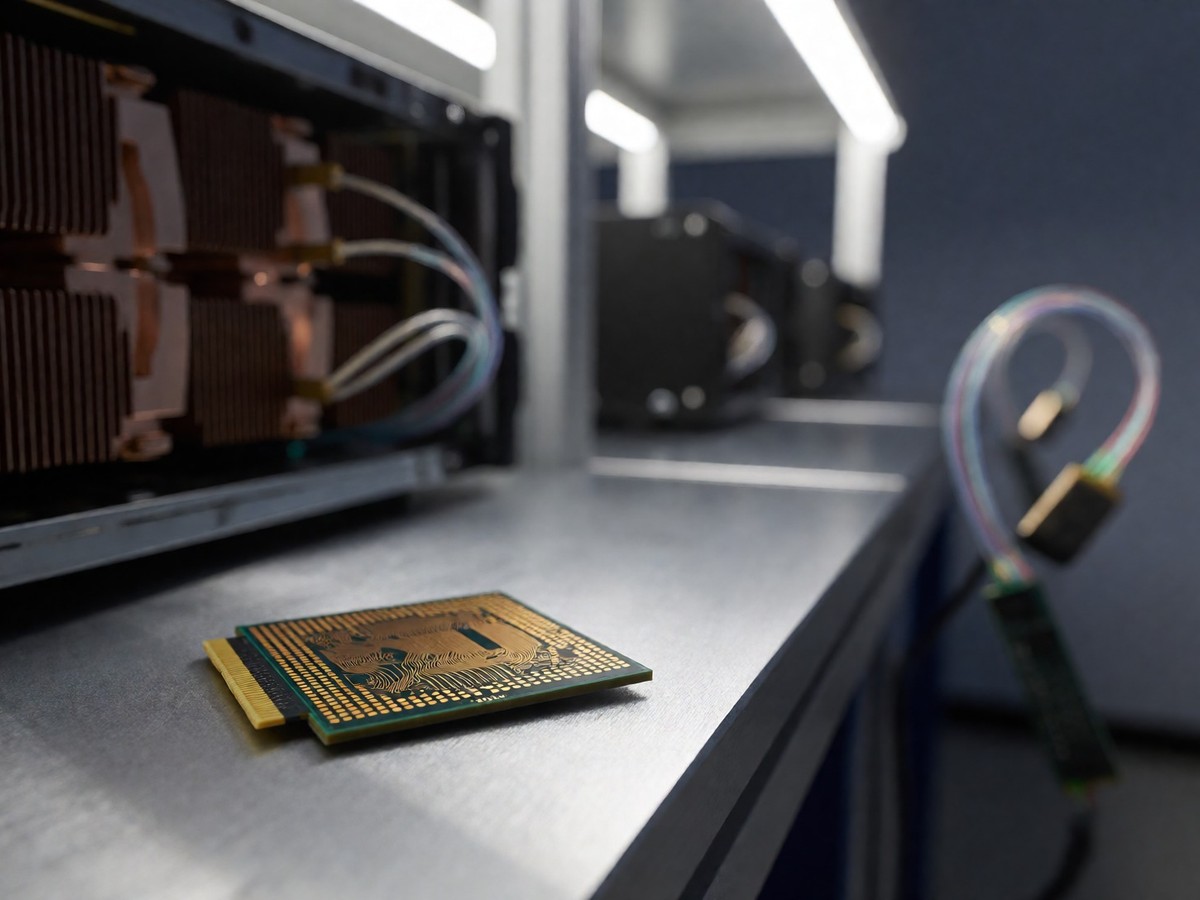
Positron AI scales inference infrastructure with Asimov chip
Positron AI secured $875 million to scale its Asimov photonic AI chip, which offers 3.5x better performance per dollar than Nvidia H100…
-
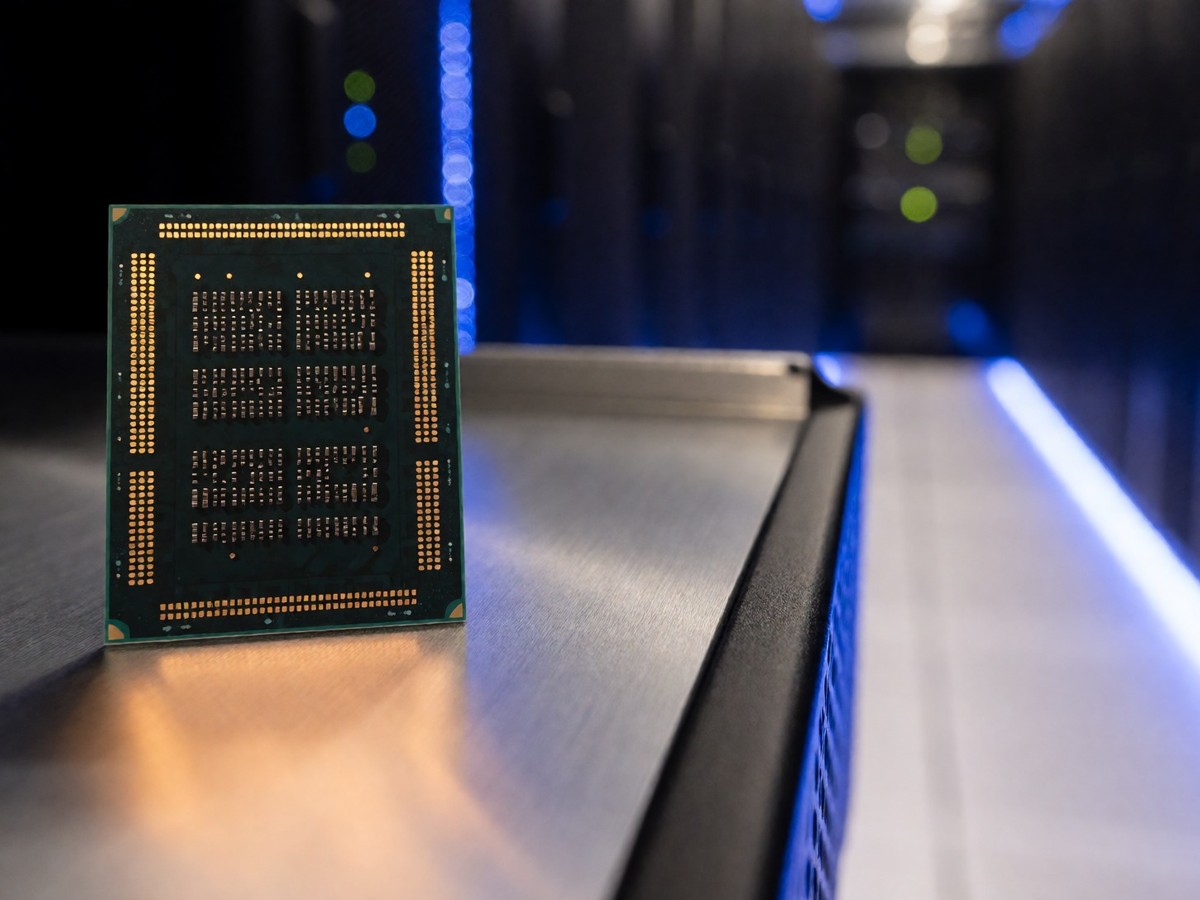
Groq’s inference growth and Meta’s Llama 4 deployment
Groq’s Language Processing Unit delivers over 750 tokens per second on Llama 3 70B by utilizing on-chip SRAM to bypass memory bottlenecks.…
Trending Now
- How Tenstorrent’s Blackhole chip scales RISC-V AI for smart factories
- Anthropic enterprise rollout and Claude long-context accuracy
- Cursor raises $2 billion to scale AI coding infrastructure
- D-Matrix Corsair chip delivers 10x faster inference than NVIDIA
- CoreWeave expands OpenAI contract as infrastructure demand grows