
Latest stories
-
Mistral AI hits 21 billion euro valuation as enterprise focus scales
Mistral AI secured 3 billion euros in Series D funding led by Samsung Electronics to support its enterprise-first strategy. The company targets…
-
The DeepMind acquisition and the rise of AI safety research
Demis Hassabis, Shane Legg, and Mustafa Suleyman founded DeepMind in 2010, leading to a Google acquisition valued up to $650 million. This…
-
Scaling Llama 3.3 70B on Lambda Labs 8x H100 instances
Training Llama 3.3 70B requires significant VRAM, with full fine-tuning demanding 1,158 GB. Lambda Labs provides 8x H100 SXM nodes with 3200…
-
NVIDIA Blackwell Ultra supply chain shifts toward memory and substrate constraints
NVIDIA’s Blackwell supply chain faces new bottlenecks in organic substrates from Ajinomoto and Ibiden following TSMC yield recoveries. While TSMC reports stable…
-
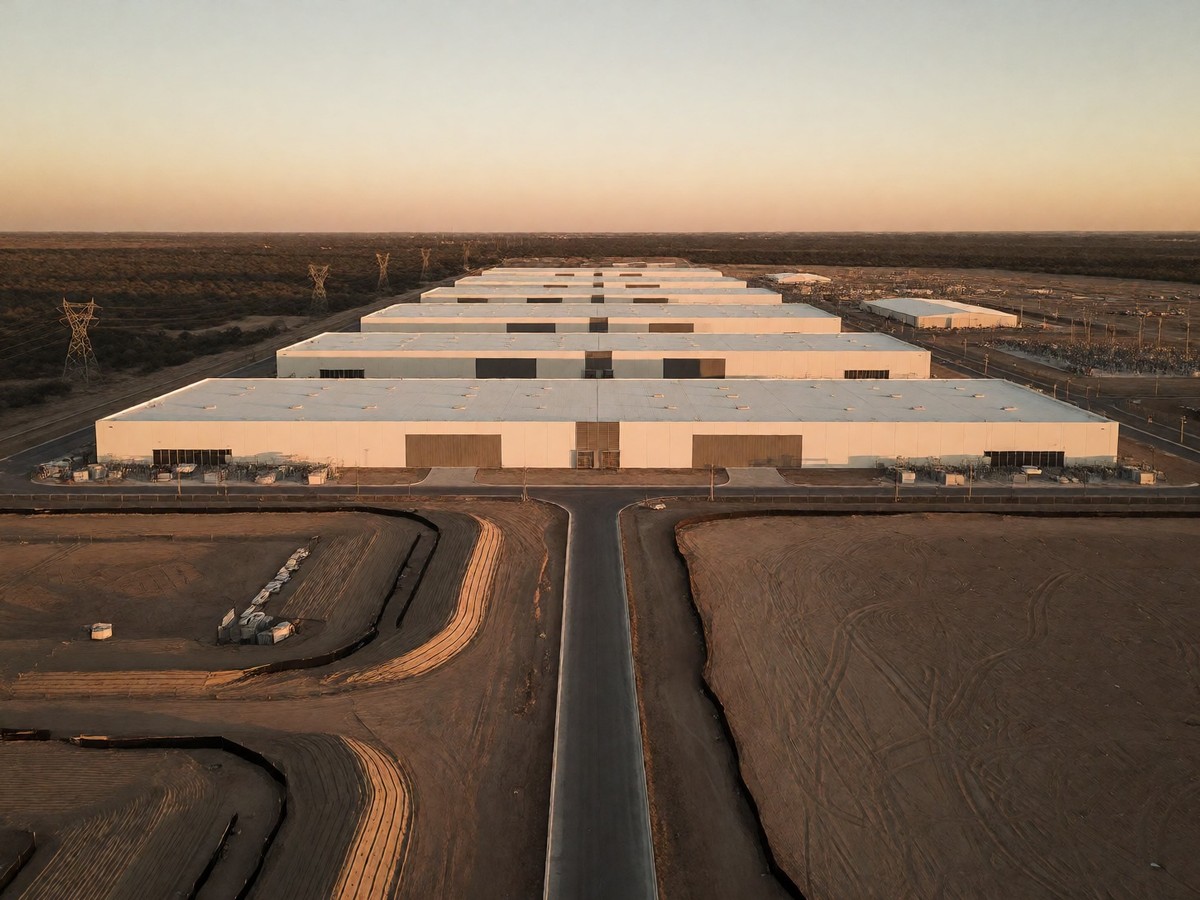
The Stargate $500 billion AI infrastructure buildout
Sam Altman, Larry Ellison, and Masayoshi Son announced the Stargate joint venture to invest $500 billion in US AI infrastructure. The project…
-
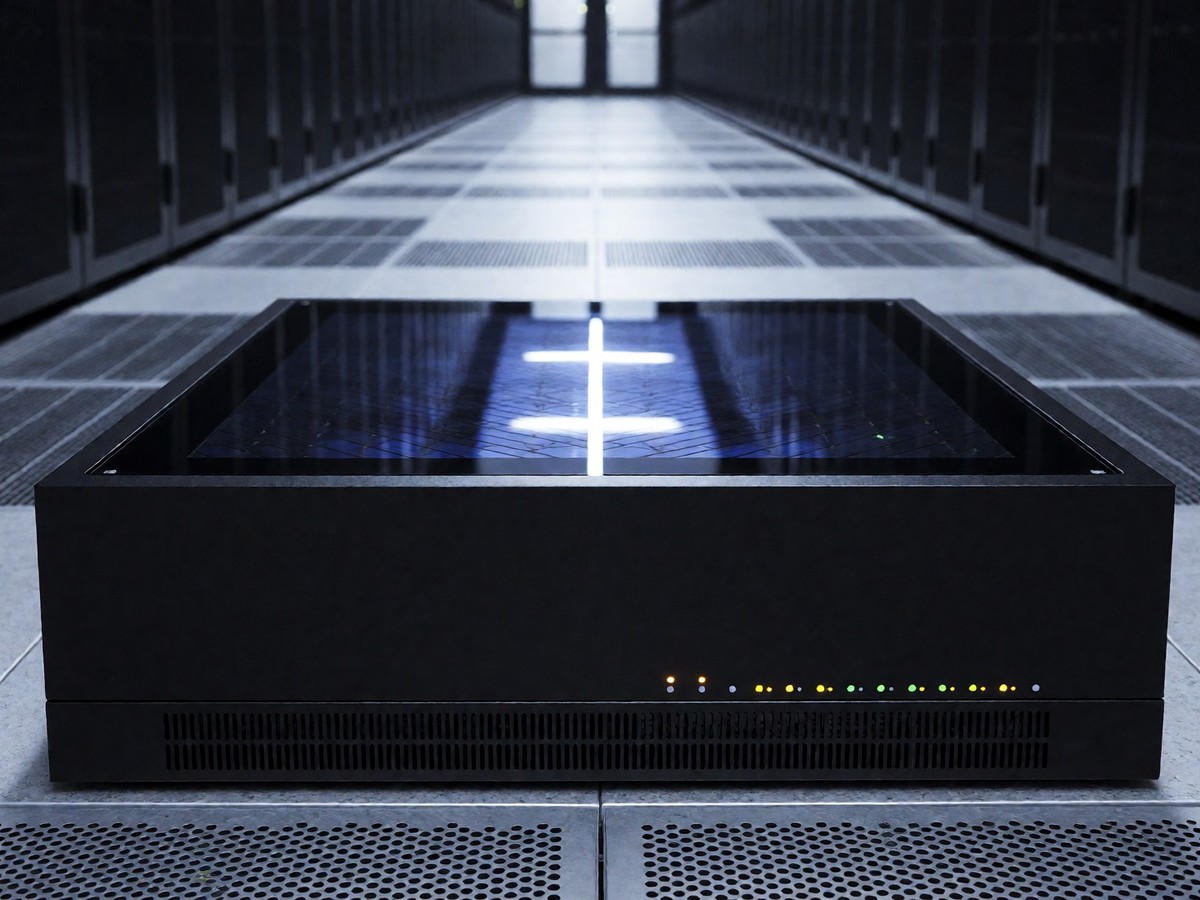
Cerebras CS-3 wafer-scale engine and sparse MoE training explained
The Cerebras WSE-3 integrates 4 trillion transistors and 900,000 AI cores onto a single 300mm silicon wafer. This monolithic design delivers 125…
-
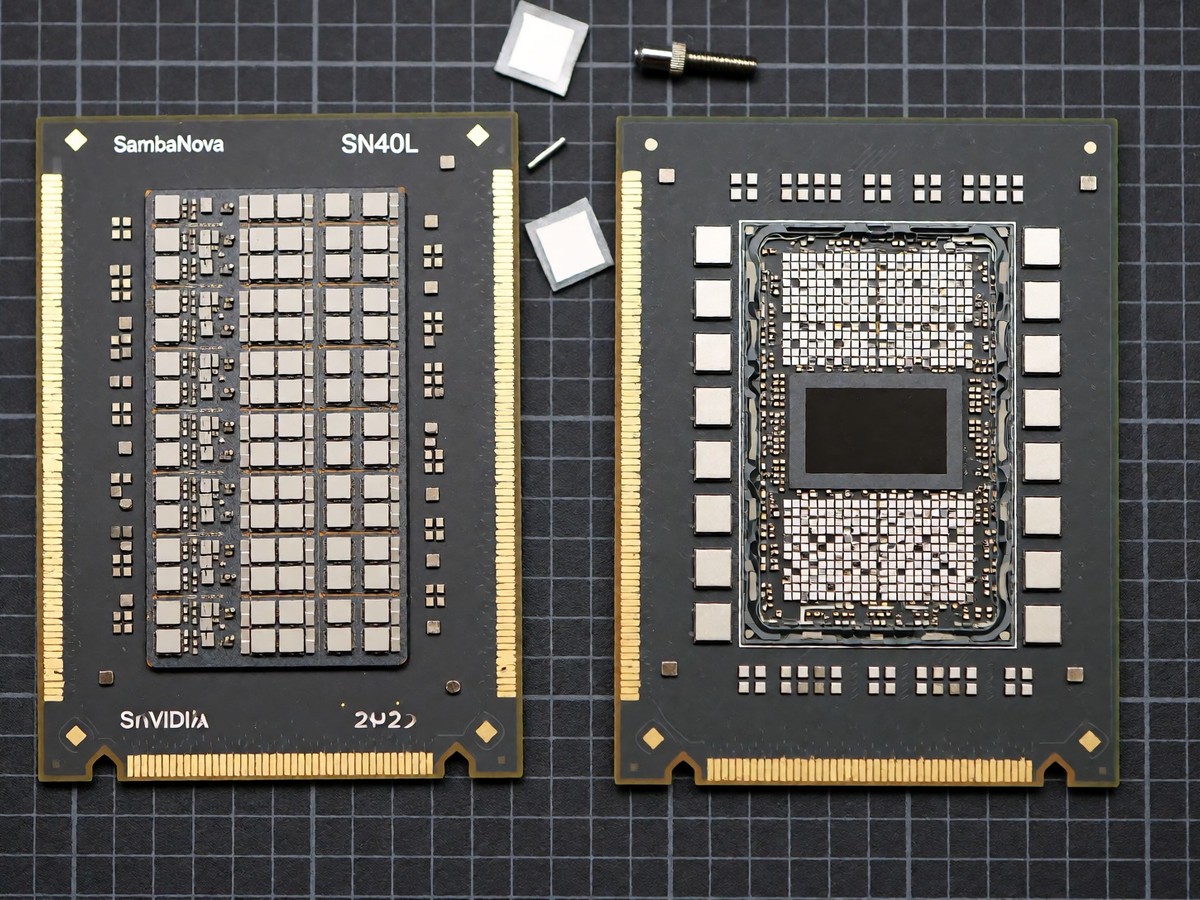
Why the SambaNova SN40L RDU beats the NVIDIA H200 on inference economics
SambaNova’s SN40L RDU delivers 9x greater performance and 5.6x more energy efficiency than the NVIDIA H200 for Llama 3.3 70B at low…
-
Databricks’ $1.3B MosaicML acquisition shifts LLM training costs
Databricks leverages its $1.3 billion MosaicML acquisition to enable enterprises to train custom large language models up to 7x faster. The platform…
-
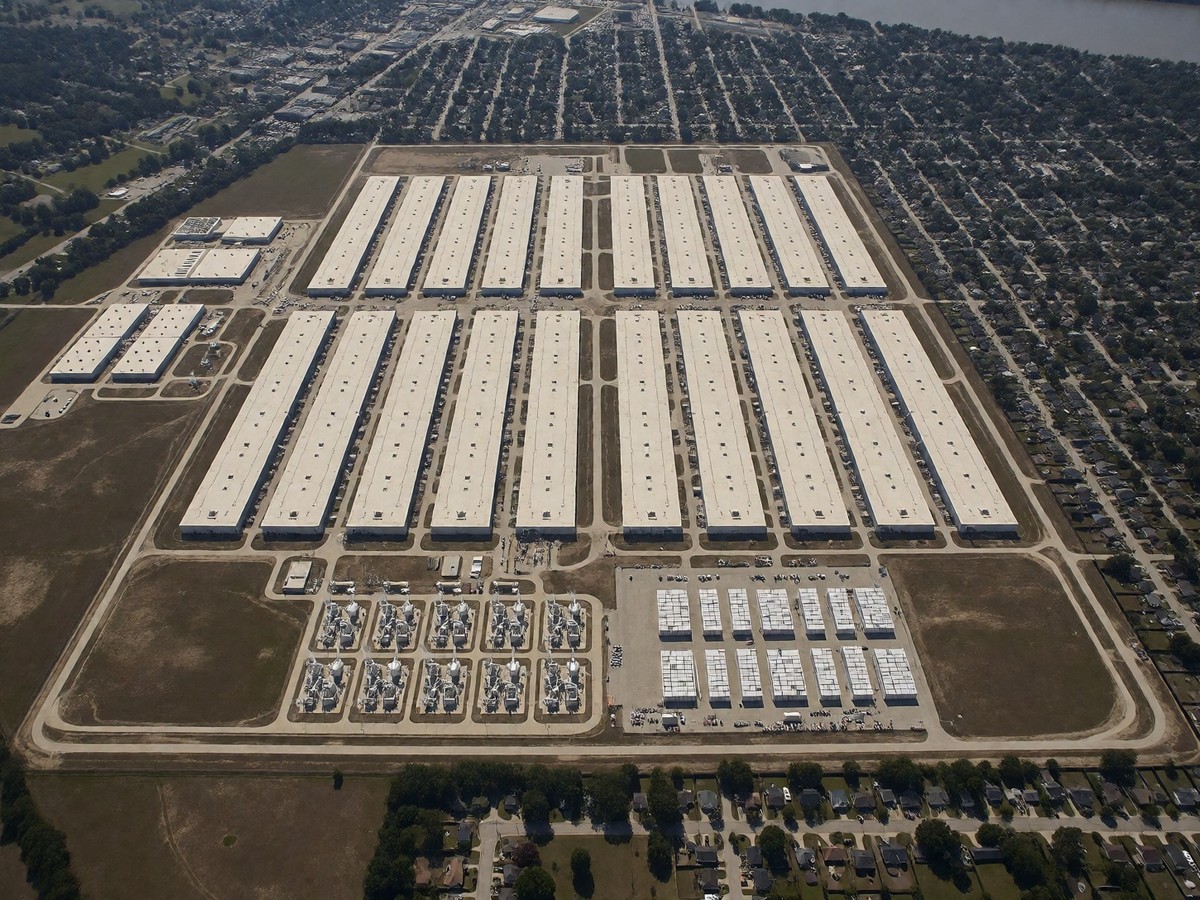
The physical reality of xAI’s Memphis expansion
xAI’s Colossus 2 facility has reached 1GW of compute capacity using 100,000 Nvidia H100 GPUs. This massive expansion creates significant grid pressure…
-
Scaling inference with Positron and Intel hardware
Positron AI’s Atlas hardware delivers 70% faster inference and 66% lower power consumption than H100 setups. The upcoming Titan system utilizes Asimov…
-
Groq secures $6.9B valuation as LPU inference outpaces NVIDIA
Groq has reached a $6.9 billion valuation as its LPU architecture delivers 500 to 750 tokens per second on Llama 3 70B…
-
DeepSeek V3 architecture and enterprise LLM deployment economics
DeepSeek-V3 utilizes a 671B parameter Mixture-of-Experts architecture to drive inference efficiency. DeepSeek-V4-Flash offers significant cost advantages for enterprises, with input costs at…