
Latest stories
-
How o1 Changes the LLM Training Picture, Part 2: Search, Reward and Cost
What reasoning models borrow from game-playing systems, why the reward signal is the bottleneck outside maths and code, and when the extra…
-
How o1 Changes the LLM Training Picture, Part 1: Why Imitation Hits a Ceiling
Pre-train, fine-tune, align. The standard recipe produced remarkable models and could not produce reasoning. Why that limit is structural rather than a…
-
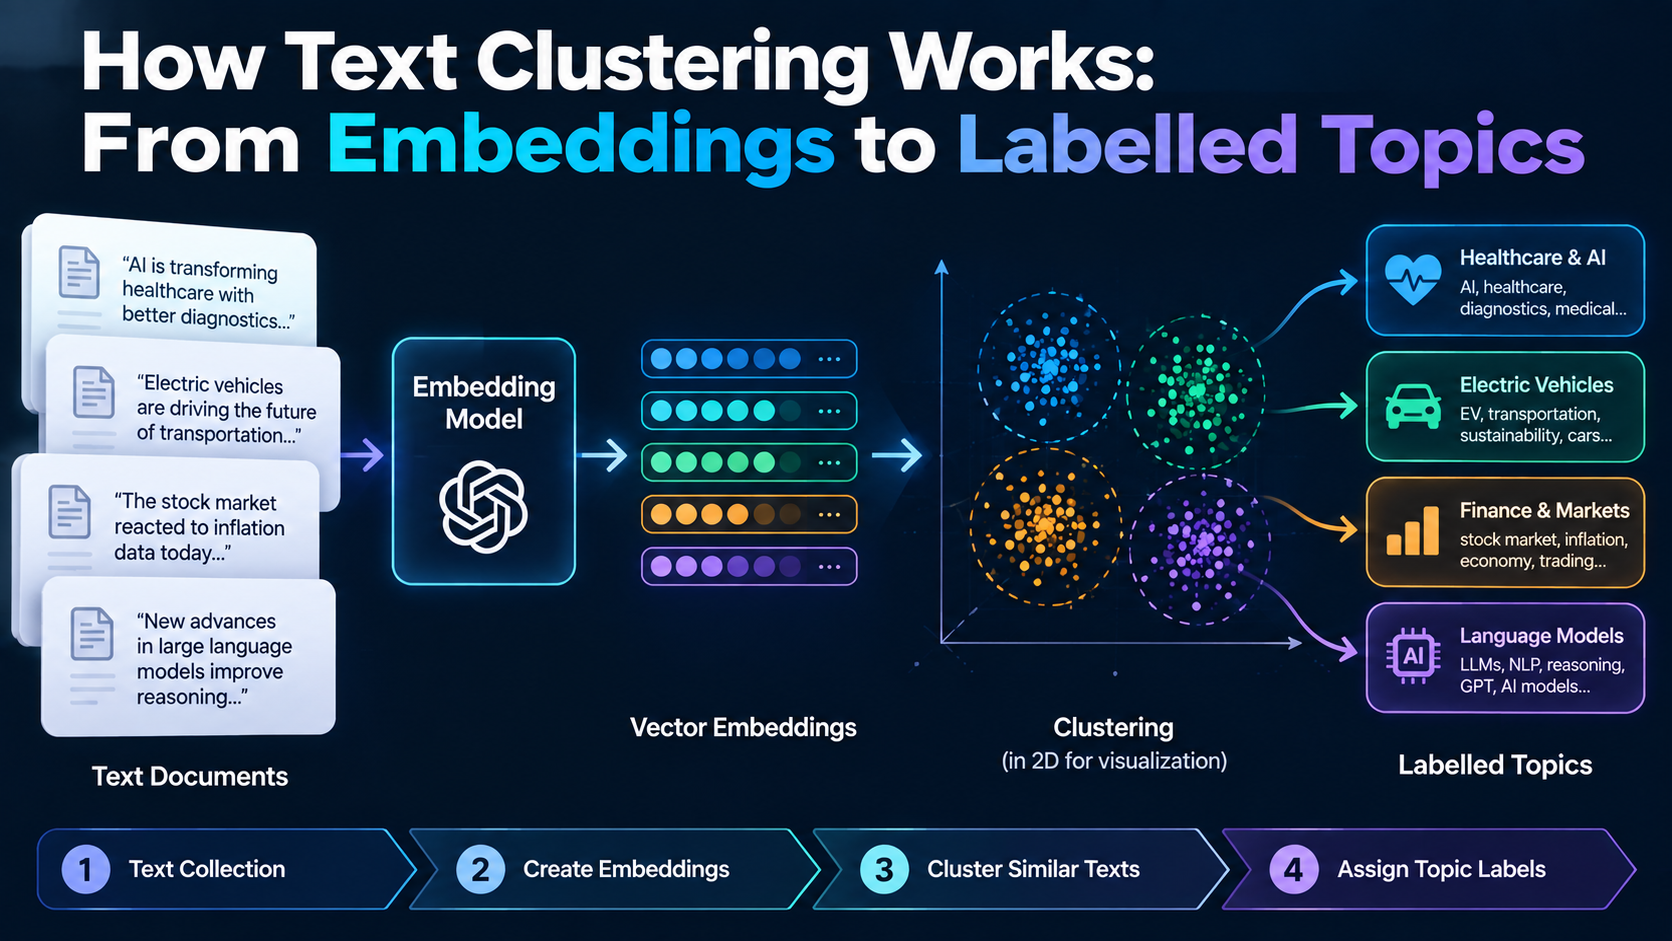
How Text Clustering Works: From Embeddings to Labelled Topics
Fifty thousand support tickets nobody has read. The pipeline that turns them into named topics, and why k-means is usually the wrong…
-
The Comprehensive Guide to LLM Evaluation
The four kinds of evaluation, which metric fits which task, and how to assemble a suite you will still be running in…
-
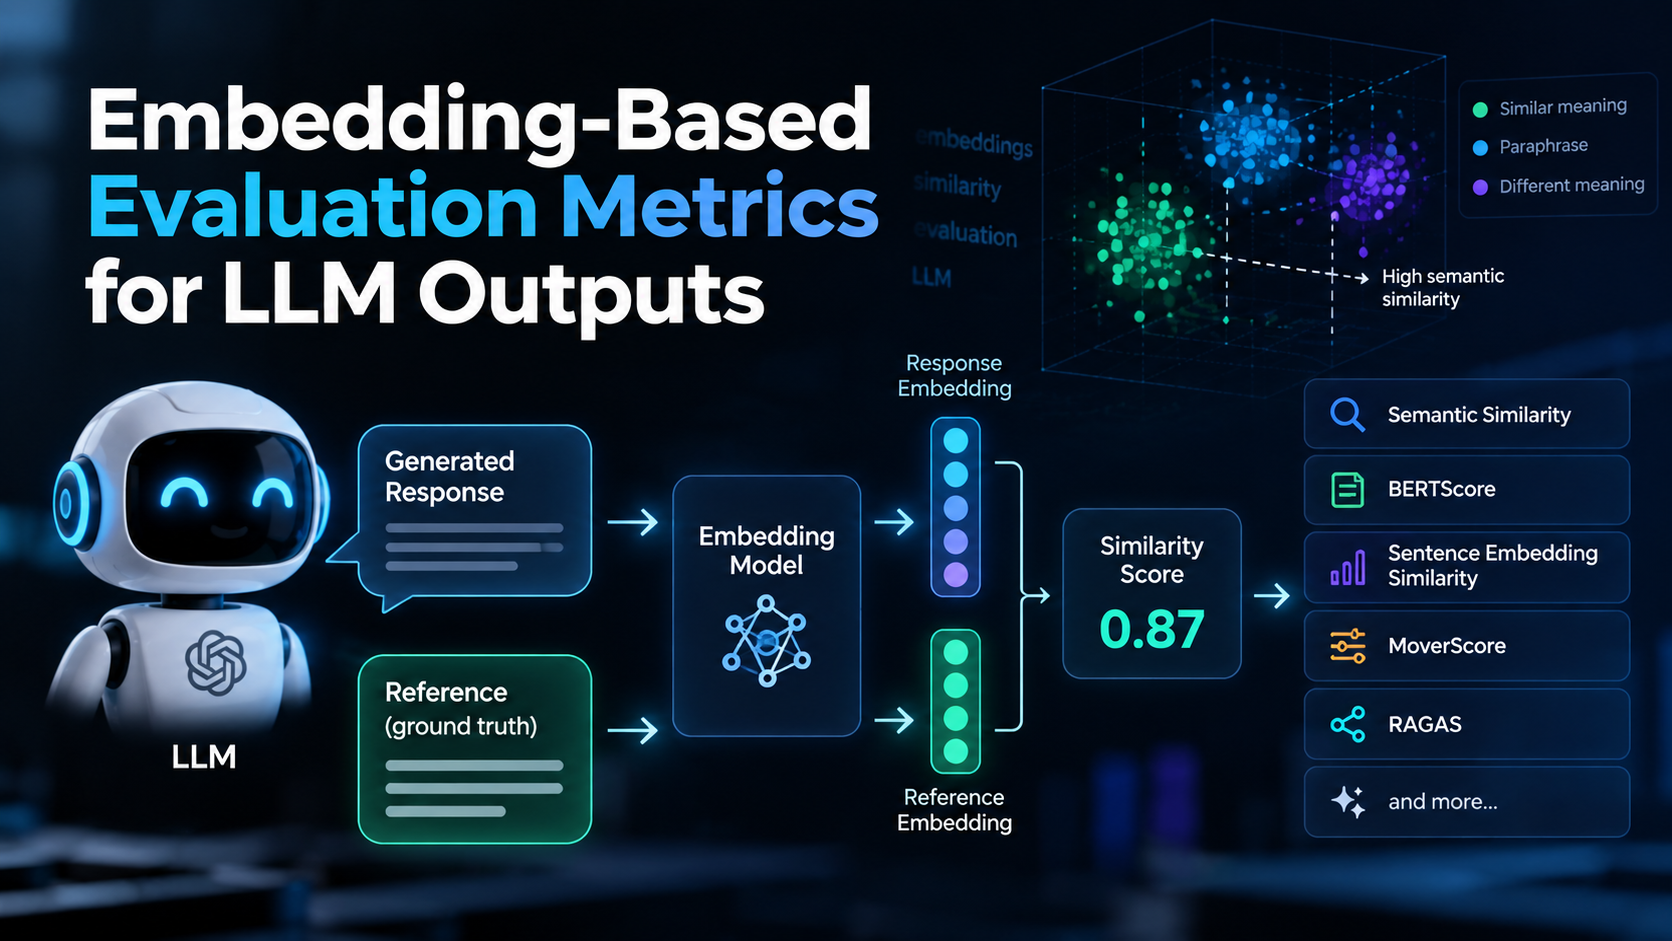
Embedding-Based Evaluation Metrics for LLM Outputs
Two sentences can share no words and mean the same thing. Embedding metrics close part of that gap – and quietly mislead…
Trending Now
- Crusoe Energy scales AI infrastructure with flared gas capture
- The history of NVIDIA’s DGX-1 and the evolution of AI clusters
- Scaling open source intelligence with Together AI and MoE
- xAI’s Colossus vs Lambda Labs’ GPU cloud for YC startups
- The $29 Billion Data Infrastructure Pivot and Federal Safety Shifts