
Latest stories
-
Thermal failures in the age of high-density AI
A voltage transient in the europe-west4-a data hall caused a chiller controller to fail, leading to a 14-hour disruption for 24 private…
-
Implementing Mistral AI Le Chat Enterprise
Mistral AI has rebranded Le Chat as Vibe, offering a unified platform for enterprise productivity and software development. The rollout features Mistral…
-
The researchers behind DeepSeek-V4’s open-source reasoning
DeepSeek released its V4 model family, featuring a 1.6 trillion parameter V4-Pro variant. Built on Huawei Ascend 950PR chips, the architecture uses…
-
Cerebras WSE-3 dominance in defense AI procurement
Cerebras WSE-3 offers a massive memory bandwidth advantage of 21 petabytes per second, outperforming Nvidia H100 by 7,000 times. This wafer-scale architecture…
-
Anthropic’s revenue growth and the accounting gap explained
Anthropic’s annualized revenue reached $65 billion, driven largely by Claude Code and a massive surge in enterprise customers. The company’s lead over…
-
What AI Revenue Multiples Actually Measure
The same headline revenue can mean very different economics once the inference bill is taken out. The questions that separate similar-looking companies.
-
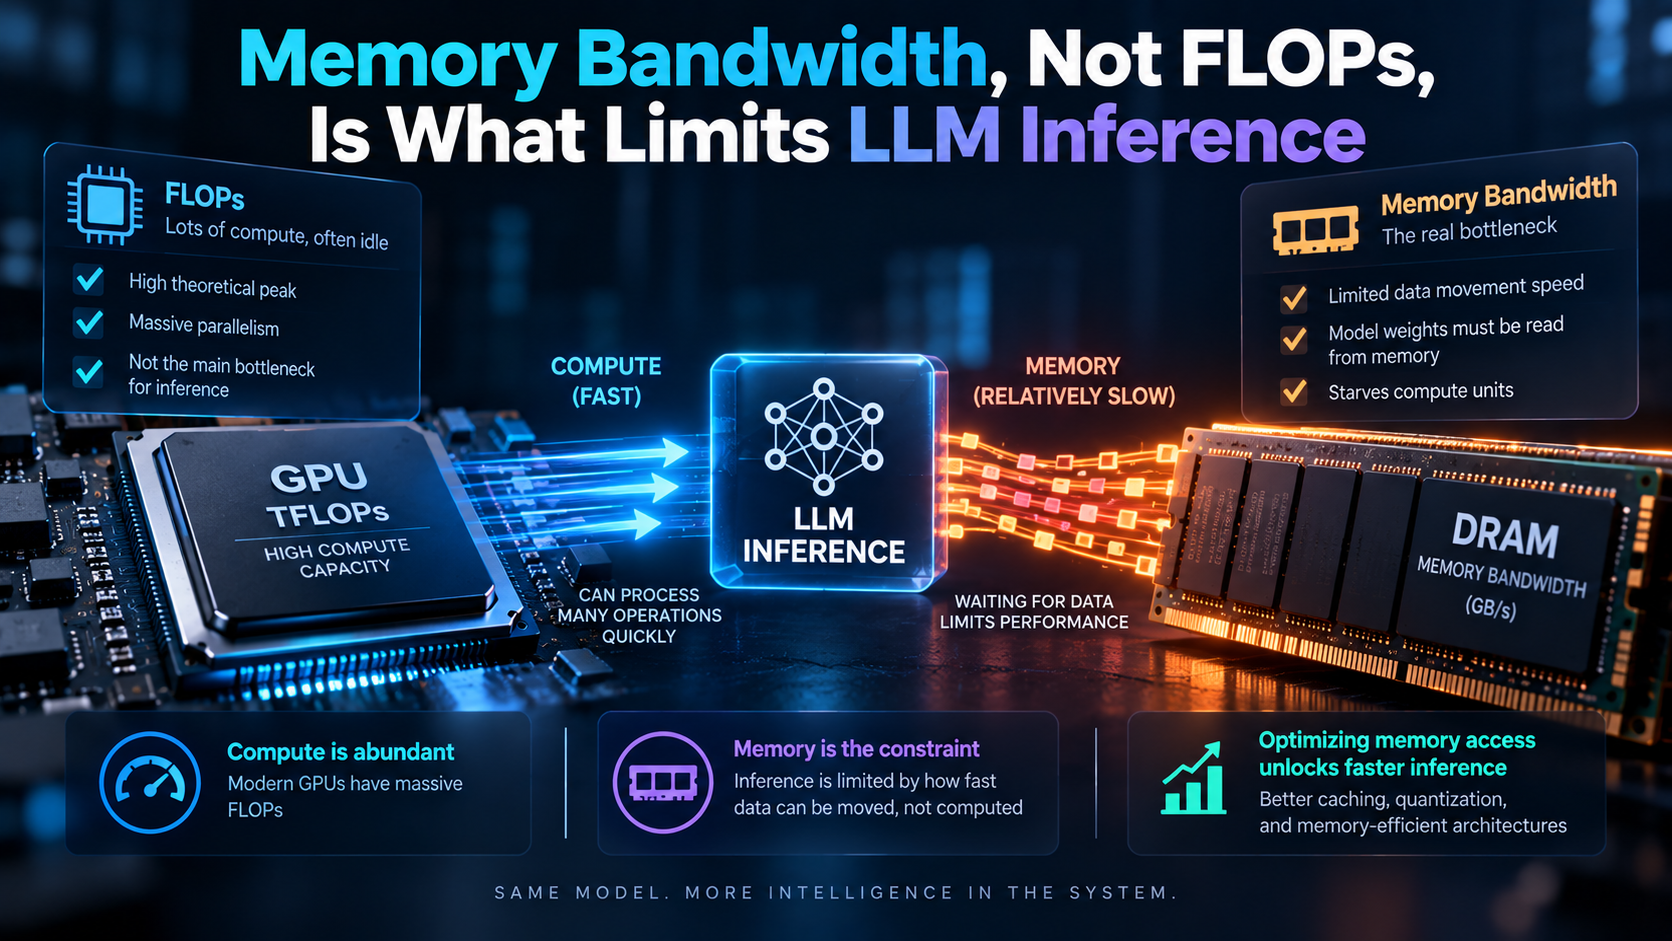
Memory Bandwidth, Not FLOPs, Is What Limits LLM Inference
Accelerators are sold on peak FLOPs, but token generation is bound by how fast weights move out of memory. What to actually…
-
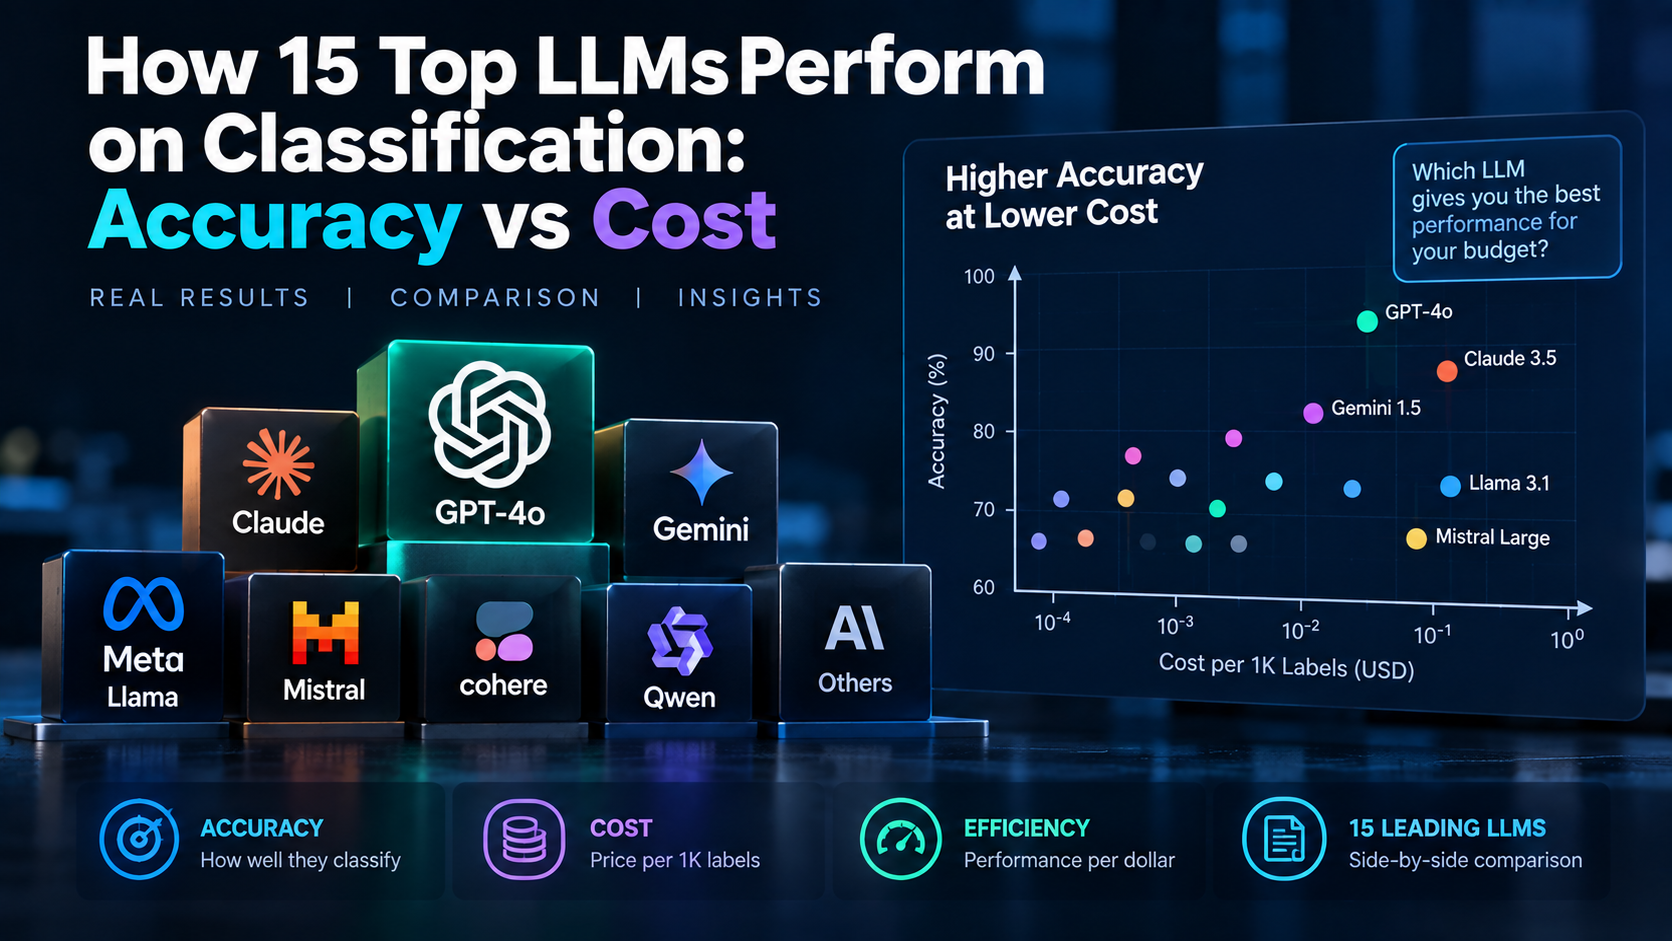
How 15 Top LLMs Perform on Classification: Accuracy vs Cost
Classification is the task most often hiding inside a production system, and the one where per-call cost compounds fastest. How to compare…
-
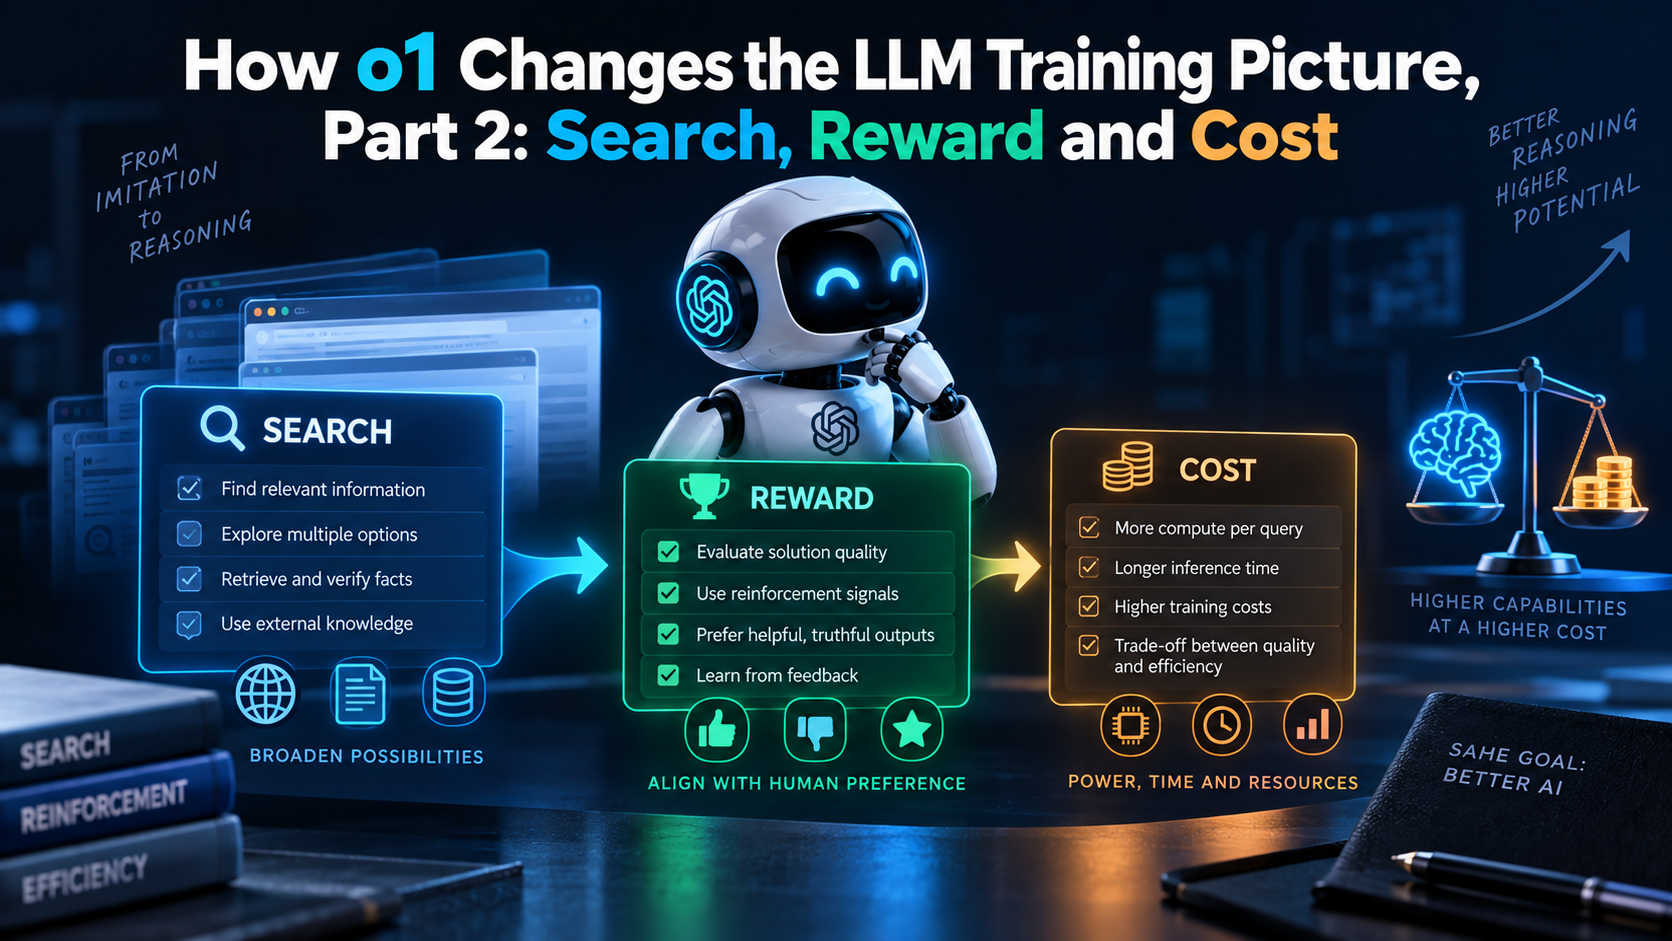
How o1 Changes the LLM Training Picture, Part 2: Search, Reward and Cost
What reasoning models borrow from game-playing systems, why the reward signal is the bottleneck outside maths and code, and when the extra…
-
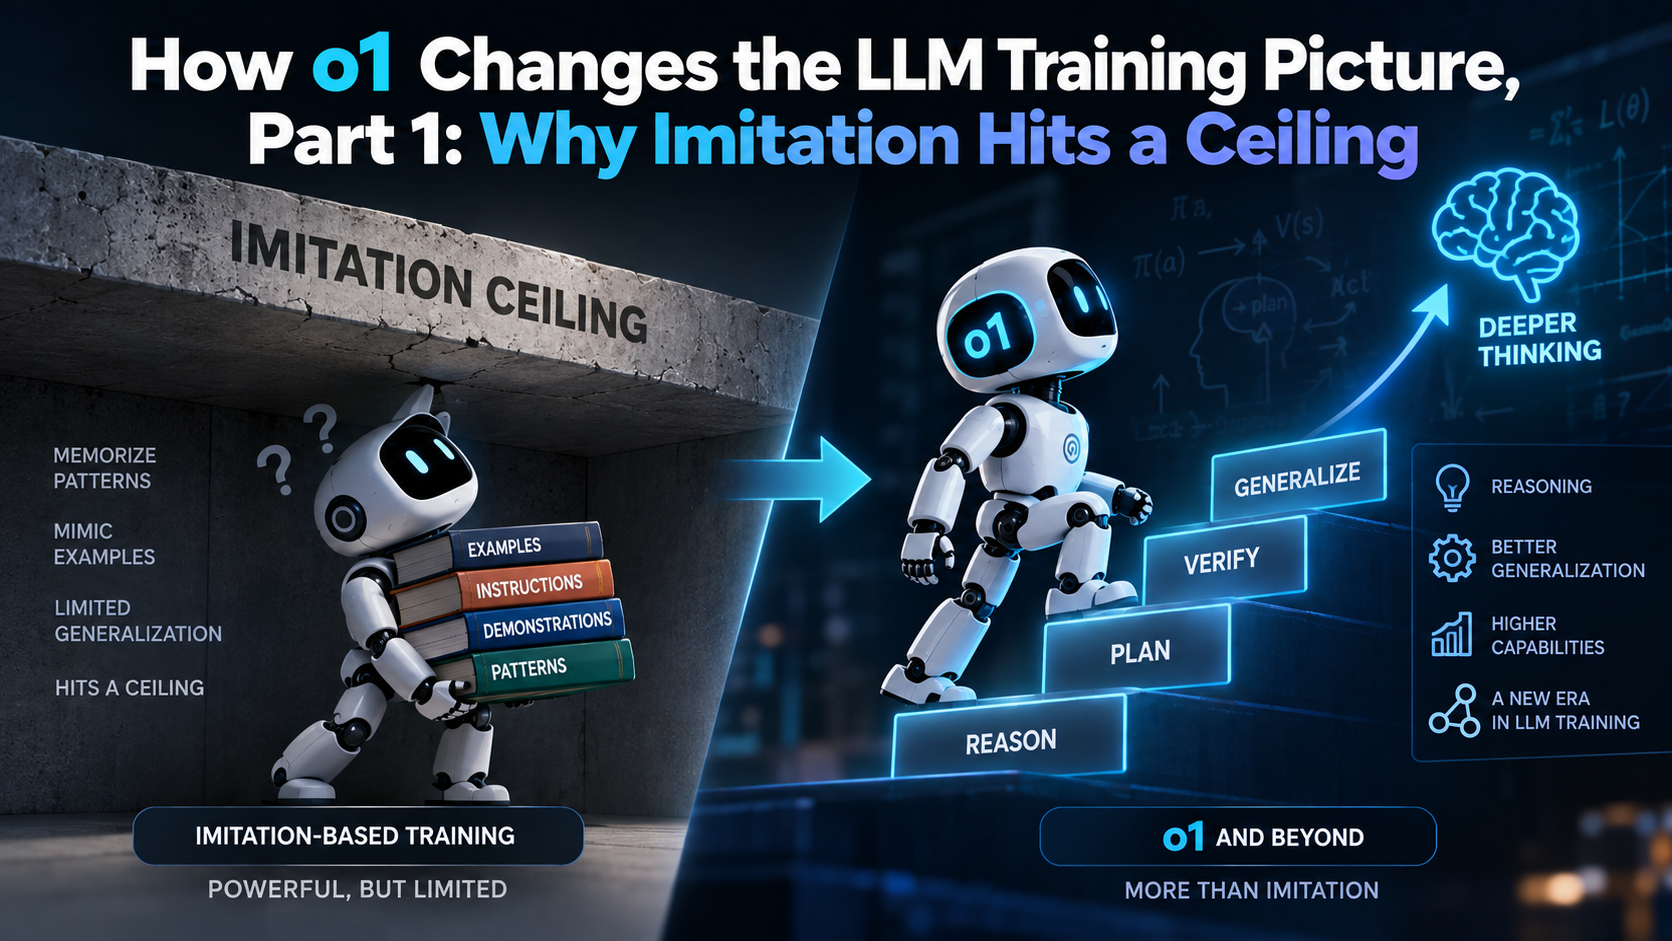
How o1 Changes the LLM Training Picture, Part 1: Why Imitation Hits a Ceiling
Pre-train, fine-tune, align. The standard recipe produced remarkable models and could not produce reasoning. Why that limit is structural rather than a…
-
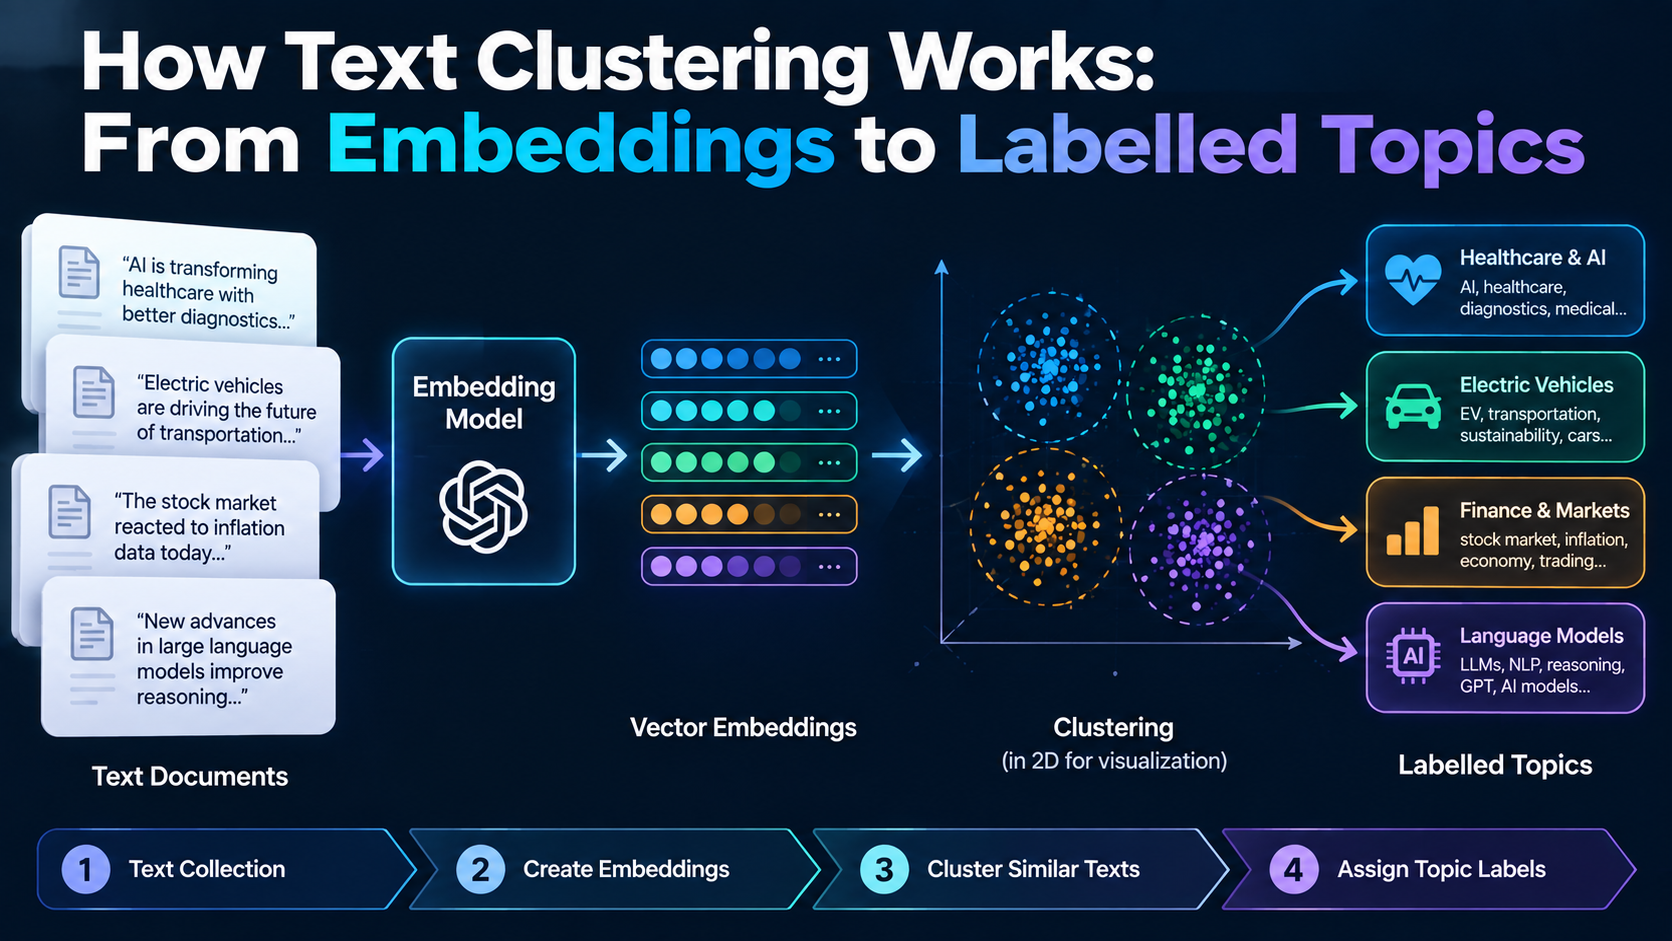
How Text Clustering Works: From Embeddings to Labelled Topics
Fifty thousand support tickets nobody has read. The pipeline that turns them into named topics, and why k-means is usually the wrong…
-
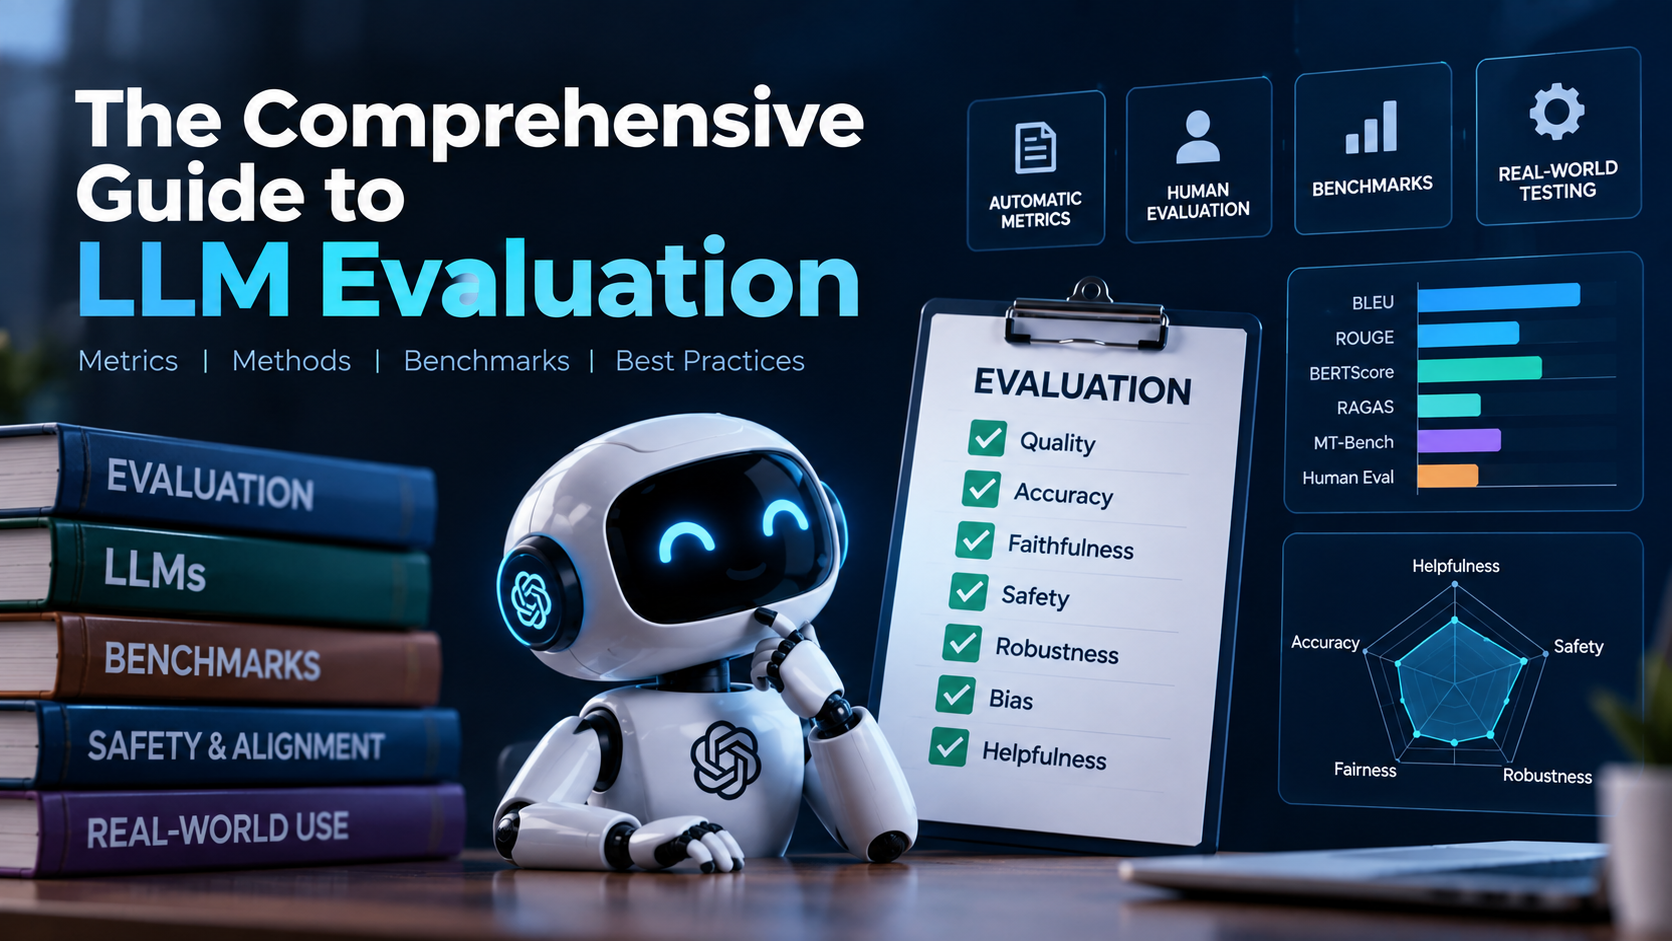
The Comprehensive Guide to LLM Evaluation
The four kinds of evaluation, which metric fits which task, and how to assemble a suite you will still be running in…
Trending Now
- Lightmatter’s Passage photonic interconnect and NVIDIA Blackwell
- Power delivery failures in SambaNova SN40L rack deployments
- Common fine-tuning mistakes that ruin Llama 3.3 enterprise deployments
- Helsing’s defense AI growth and Ukraine drone deployments
- Understanding Anthropic Claude Enterprise pricing and usage