
GPUs
-
VRAM Waste and Routing Failures in MI300X MoE Fine-Tuning
Engineers provisioning AMD Instinct MI300X clusters often face memory failures by using inference-only sizing for MoE training. Proper provisioning for a 235B…
-
The cost of scaling AI interconnects
Marvell’s $3.25 billion acquisition of Celestial AI targets the 16 Tbps Photonic Fabric platform to scale XPU connections. This optical interconnect offers…
-
Deploying Mixtral 8x22B on Fireworks AI
Fireworks AI provides serverless GPU inference for the Mixtral 8x22B model, utilizing a sparse Mixture-of-Experts architecture with 141 billion parameters. Developers can…
-
Scaling Llama 3.3 70B on Lambda Labs 8x H100 instances
Training Llama 3.3 70B requires significant VRAM, with full fine-tuning demanding 1,158 GB. Lambda Labs provides 8x H100 SXM nodes with 3200…
-
NVIDIA Blackwell Ultra supply chain shifts toward memory and substrate constraints
NVIDIA’s Blackwell supply chain faces new bottlenecks in organic substrates from Ajinomoto and Ibiden following TSMC yield recoveries. While TSMC reports stable…
-
Cerebras CS-3 wafer-scale engine and sparse MoE training explained
The Cerebras WSE-3 integrates 4 trillion transistors and 900,000 AI cores onto a single 300mm silicon wafer. This monolithic design delivers 125…
-
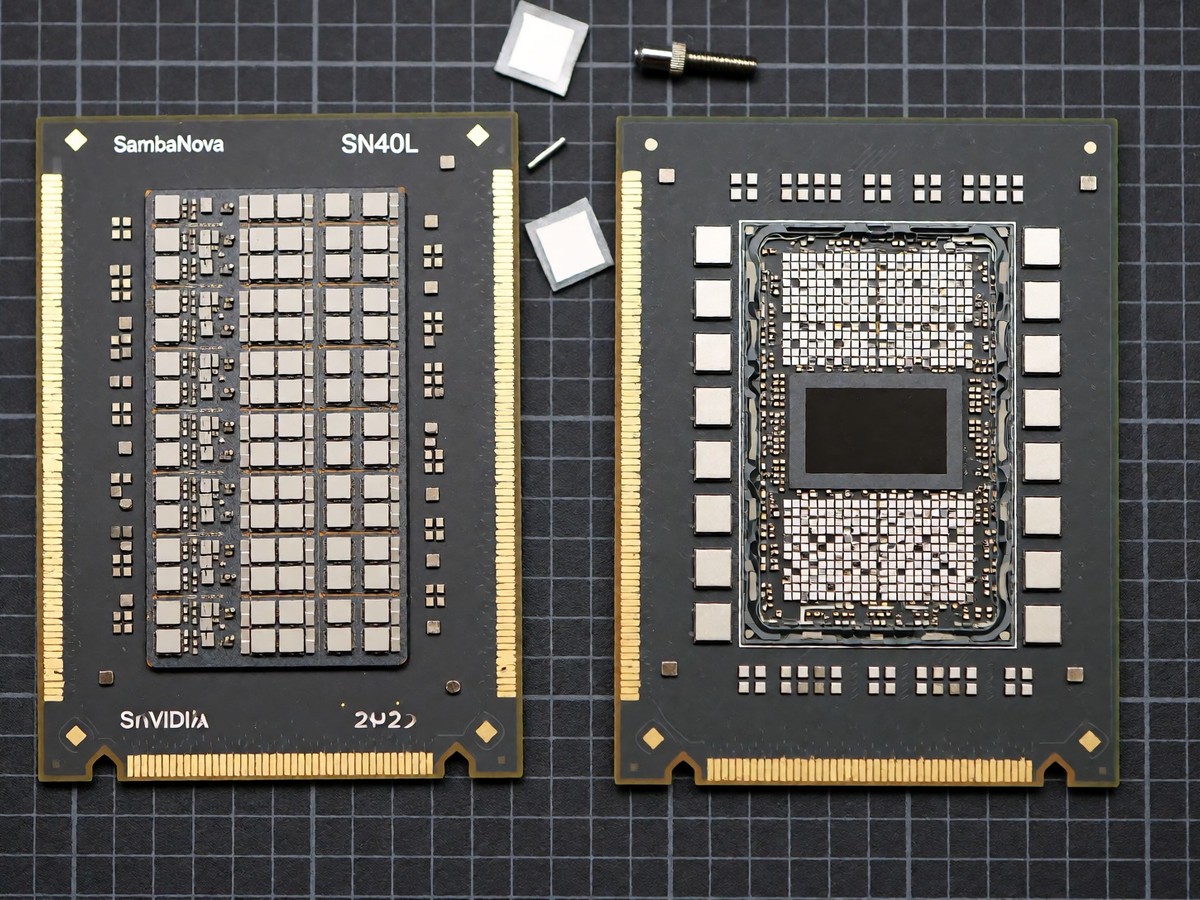
Why the SambaNova SN40L RDU beats the NVIDIA H200 on inference economics
SambaNova’s SN40L RDU delivers 9x greater performance and 5.6x more energy efficiency than the NVIDIA H200 for Llama 3.3 70B at low…
-
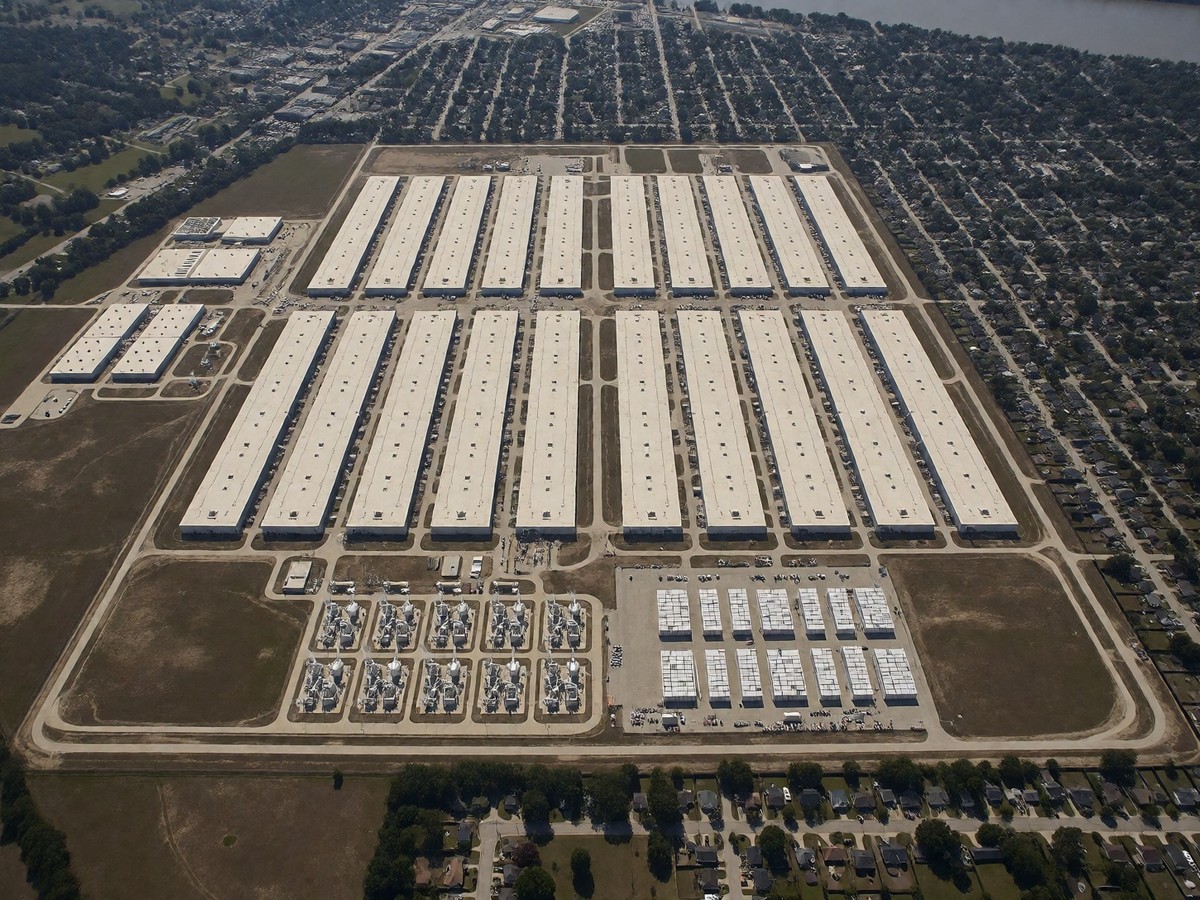
The physical reality of xAI’s Memphis expansion
xAI’s Colossus 2 facility has reached 1GW of compute capacity using 100,000 Nvidia H100 GPUs. This massive expansion creates significant grid pressure…
-
CoreWeave expands AI capacity through OpenAI and Dell deals
CoreWeave expanded its OpenAI partnership with a new $6.5 billion deal, bringing total contract value to $22.4 billion. The company is also…
-
Replicate model hosting and serverless GPU pricing analysis
Replicate offers a model marketplace with over 50,000 public models, but H100 instances cost $5.49 per hour, which is significantly higher than…
-
Meta’s MTIA v2 outperforms GPUs for Instagram recommendation models
Meta’s MTIA v2 architecture delivers 3.5x more dense compute performance than its predecessor to optimize Instagram Reels. The custom silicon provides 128…
-
d-Matrix moves Corsair into production to meet AI inference demand
d-Matrix has launched its Corsair inference accelerator platform to support massive AI workloads, delivering 30,000 tokens per second for Llama 70B models.…