
GPUs
-
SN40L performance and trillion-parameter expert scaling
SambaNova’s SN40L RDU node achieves a 3.7x speedup over DGX H100 when running 150 7B experts totaling over 1 trillion parameters. The…
-
The history of NVIDIA’s DGX-1 and the evolution of AI clusters
NVIDIA’s 2016 DGX-1 system used Pascal architecture to deliver the performance of 250 x86 servers in a single 3U box. This breakthrough…
-
xAI’s Colossus vs Lambda Labs’ GPU cloud for YC startups
xAI’s Colossus supercomputer utilizes 230,000 GPUs for massive scale, but Lambda Labs and specialized marketplaces offer better flexibility and cost savings for…
-
The economics of CoreWeave’s capital expansion and GPU pricing
CoreWeave secured over $30 billion in capital to fund rapid expansion, facing rising operating expenses of $1.19 billion. Specialized GPU rental rates…
-
Intel diverts resources to Jaguar Shores as AMD gains ground
Intel is pivoting from its Falcon Shores AI accelerator to focus on the Jaguar Shores rack-scale system following a $1.6 billion net…
-
CoreWeave’s $23B debt-to-IPO pivot
CoreWeave faces a $35.1 billion debt load as it manages massive capital expenditures and a $103.7 billion backlog. While revenue doubled to…
-
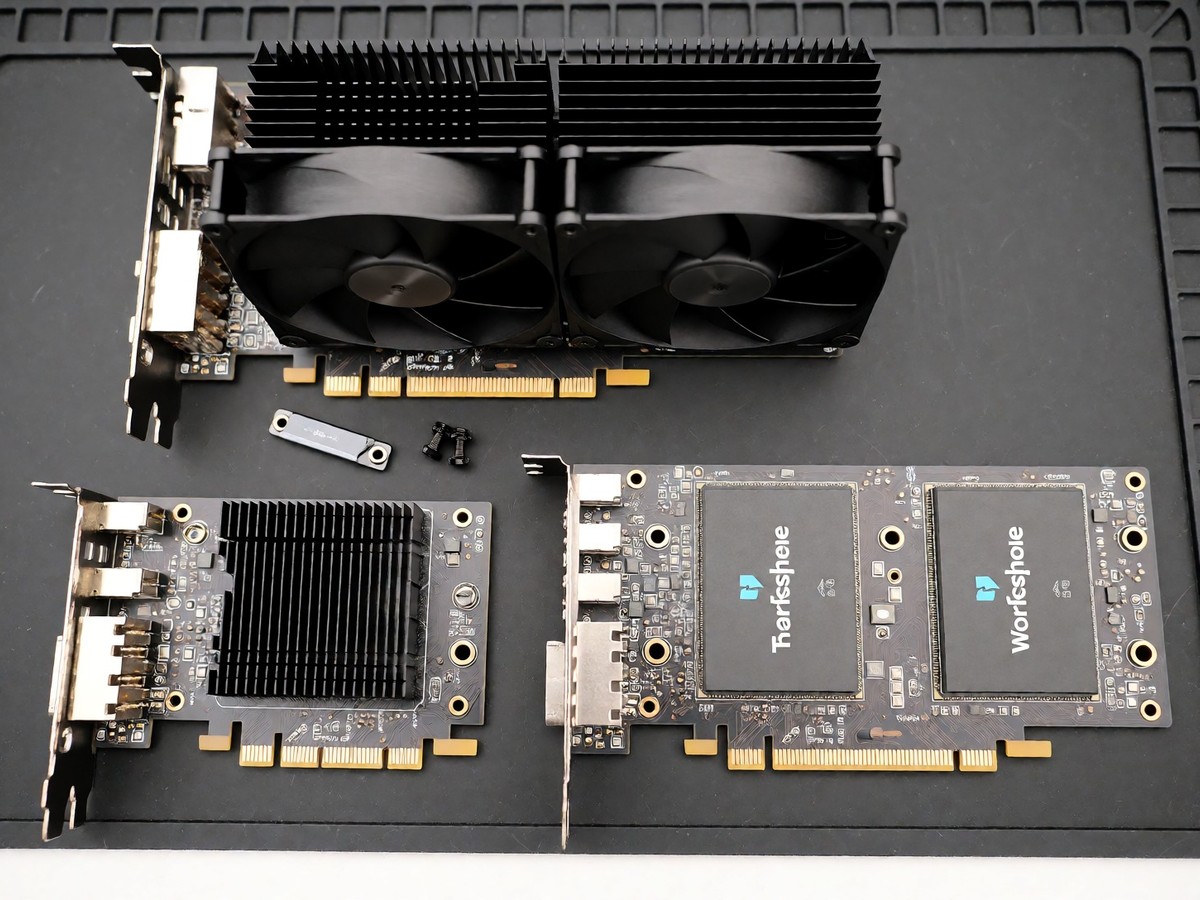
Tenstorrent Blackhole and Wormhole architecture explained
Tenstorrent’s RISC-V based architecture utilizes Tensix cores and explicit DMA data movement to provide an alternative to NVIDIA. The Blackhole p150 developer…
-
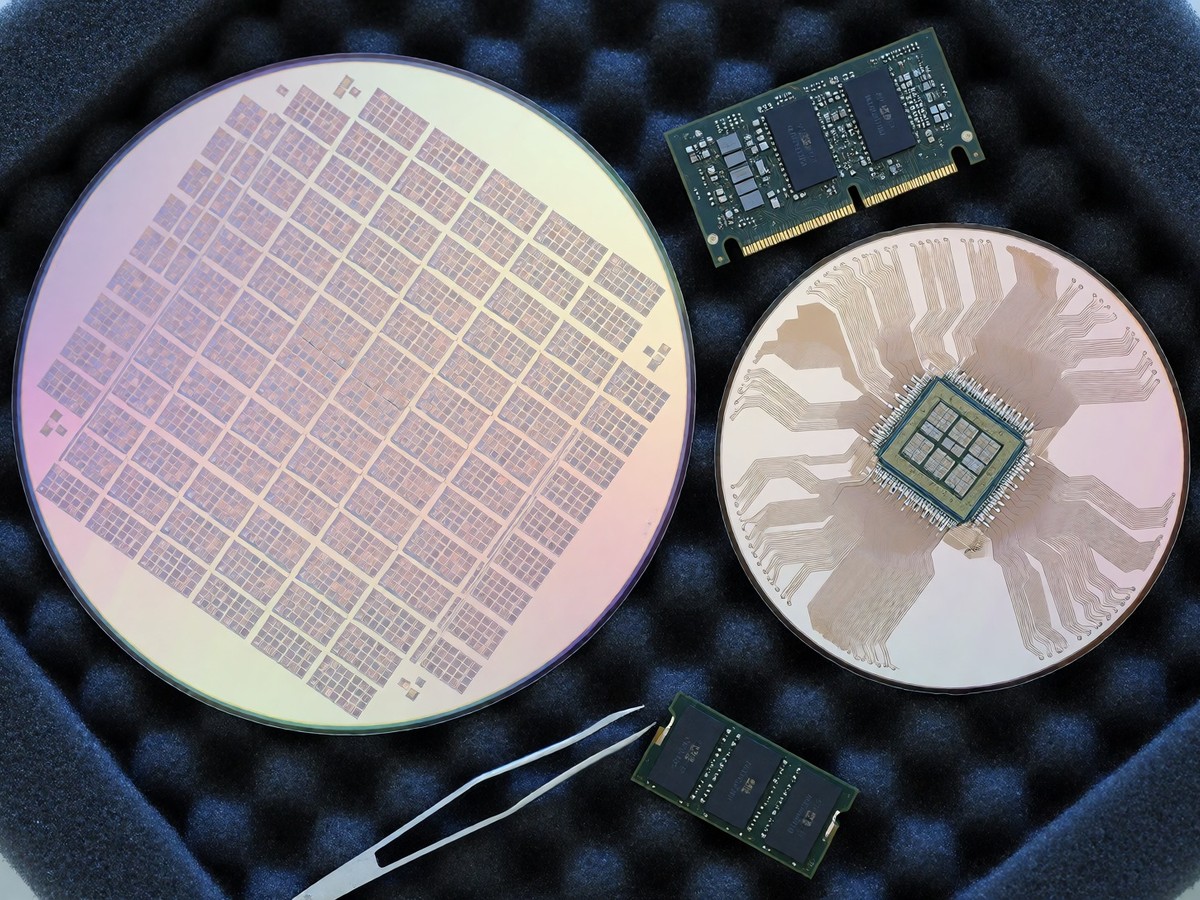
SambaNova SN50 vs Cerebras WSE-3 for large scale inference
SambaNova SN50 delivers 5x the maximum speed and 3x the throughput for agentic inference compared to Blackwell B200 GPUs. Cerebras WSE-3 provides…
-
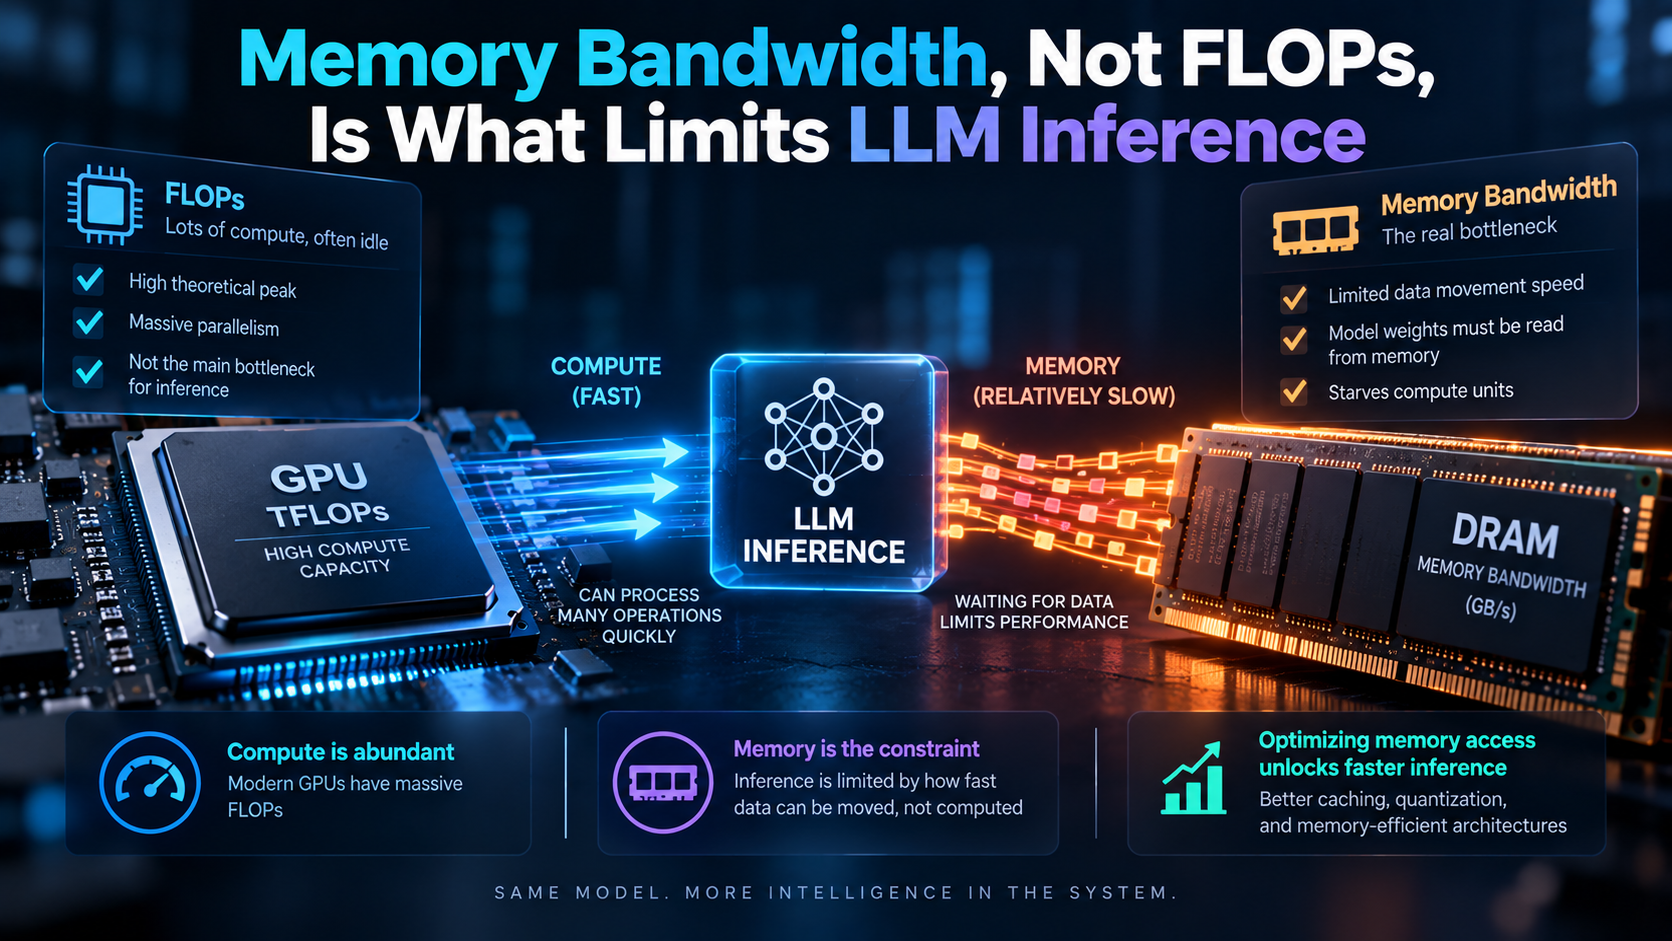
Memory Bandwidth, Not FLOPs, Is What Limits LLM Inference
Accelerators are sold on peak FLOPs, but token generation is bound by how fast weights move out of memory. What to actually…