
Hardware & Compute
Chips, data centres and the infrastructure behind AI.
-
Tenstorrent Wormhole vs AMD MI300X: Sparse LLM Inference Comparison
Tenstorrent’s architecture offers superior scaling for sparse LLM inference by addressing memory and networking bottlenecks. Jim Keller claims his Galaxy servers can…
-
Graphcore Bow IPU: The 350W push against NVIDIA dominance
Graphcore’s Bow IPU utilizes wafer-on-wafer technology to deliver 350 trillion floating point per second of AI arithmetic. The BOW POD-16 offers a…
-
Lambda capitalizes on debt markets as CoreWeave faces earnings pressure
Lambda secured a $1.008 billion senior secured loan to fund GPU infrastructure while CoreWeave reported a second-quarter adjusted loss of 27 cents…
-
The Cerebras CS-3 delivers 2,500 tokens per second for Llama 4 Maverick
Cerebras CS-3 delivers Llama 4 Maverick inference at 2,500 tokens per second per user, significantly outperforming the NVIDIA DGX B200. The WSE-3…
-
Positron AI scales inference infrastructure with Asimov chip
Positron AI secured $875 million to scale its Asimov photonic AI chip, which offers 3.5x better performance per dollar than Nvidia H100…
-
Avoiding HBM bottlenecks in Gaudi 3 LLaMA 405B clusters
Intel Gaudi 3 provides 3.7 TB/s of HBM bandwidth, but failing to use dynamic memory allocation can cause a 20% drop in…
-
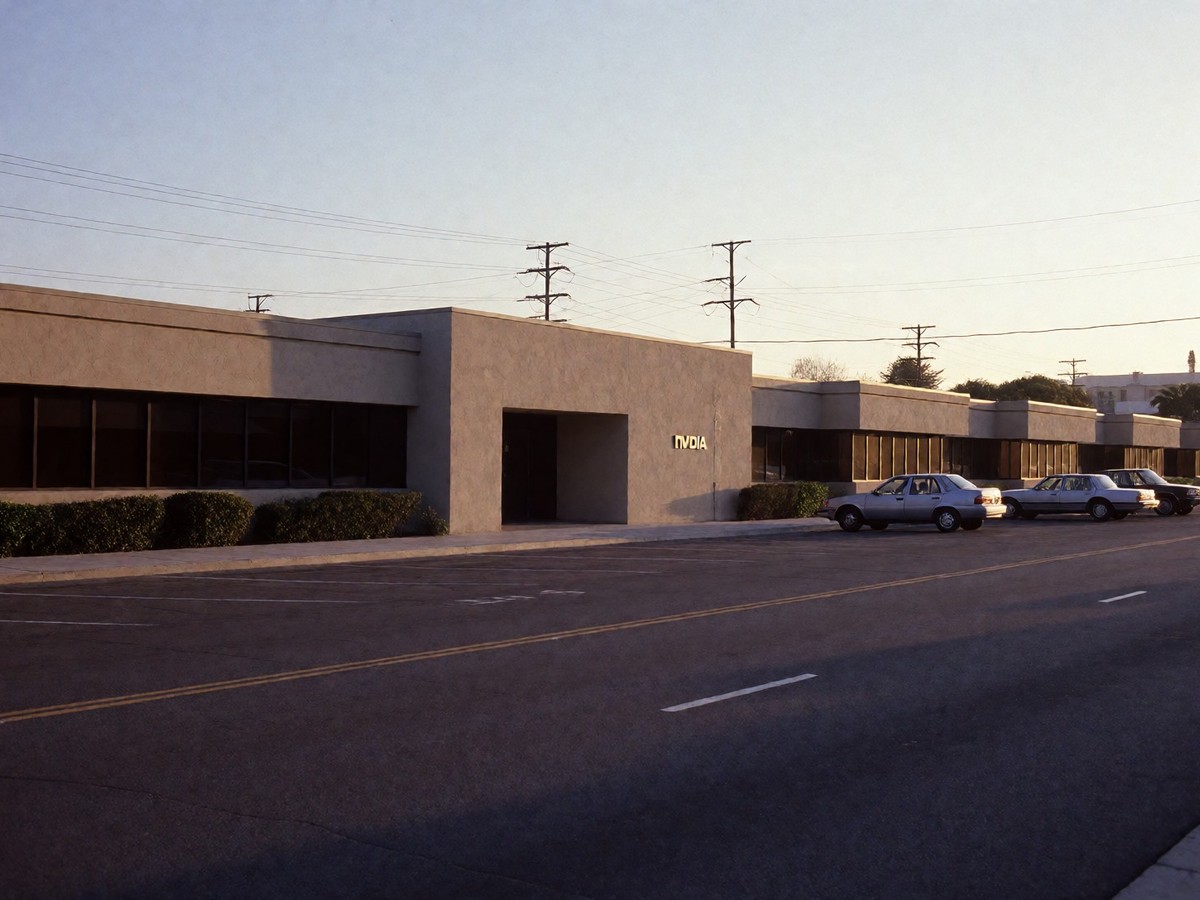
NVIDIA history from 1993 founding to the CUDA AI revolution
NVIDIA transitioned from a gaming chip manufacturer to an AI powerhouse following the 2006 launch of CUDA. This parallel computing platform enabled…
-
Groq’s inference growth and Meta’s Llama 4 deployment
Groq’s Language Processing Unit delivers over 750 tokens per second on Llama 3 70B by utilizing on-chip SRAM to bypass memory bottlenecks.…
-
Deploying Llama 3.2 90B Vision on SambaNova SN40L
SambaNova’s SN40L RDU provides enterprise infrastructure for Llama 3.2 90B Vision, delivering a 3.7x speedup over the DGX H100. The hardware uses…
-
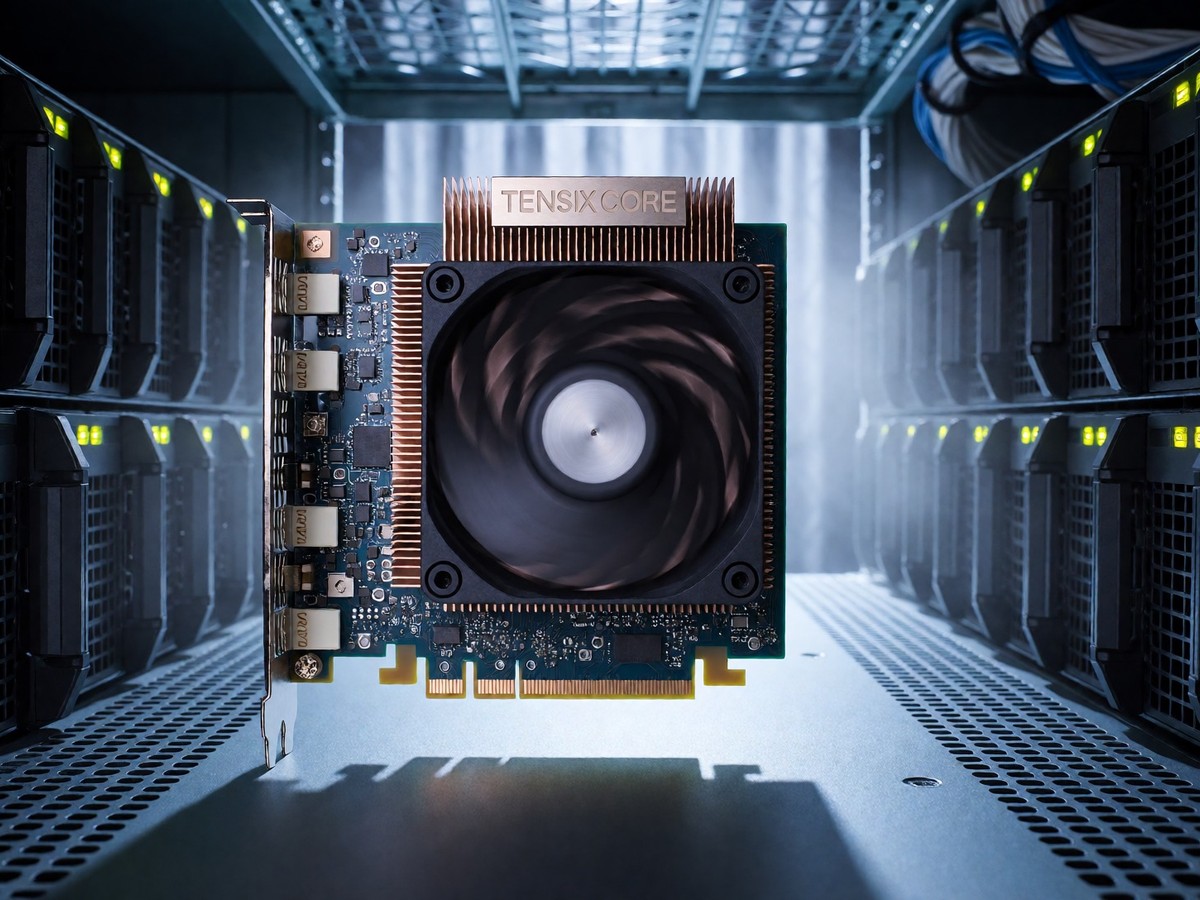
The hardware economics of Tenstorrent Blackhole AI chips
Tenstorrent Galaxy Blackhole systems achieve $6 per million tokens for DeepSeek R1 671B, significantly undercutting NVIDIA’s implied $30 per million token cost.…
-
Metis delivers high throughput for edge vision
Axelera AI’s Metis platform utilizes a quad-core RISC-V architecture and Digital In-Memory Computing to achieve 15 TOPS/W at INT8 precision. The hardware…
-
Cerebras undercuts GPU tokens through wafer-scale speed
Cerebras Inference delivers Llama 3.1 70B at 446 tokens per second for $0.6 per 1M tokens, significantly outperforming H100 clusters. The company’s…