
Hardware & Compute
Chips, data centres and the infrastructure behind AI.
-

D-Matrix Corsair chip delivers 10x faster inference than NVIDIA
D-Matrix began shipping its Corsair digital in-memory compute hardware to hyperscalers and AI labs in June 2026. Led by Sid Sheth, the…
-
The rise and fall of Graphcore
Graphcore developed the $2.8B IPU architecture to accelerate AI training by up to 100 times. After facing a liquidity crisis and a…
-
Yield advantage and packaging limits in wafer-scale AI
Cerebras achieves 93% silicon utilization on its WSE-3 wafer-scale chip through advanced defect tolerance. However, massive 23 kW power draws and TSMC…
-
Positron’s $875M Memory-First Architecture vs Lightmatter’s Passage
Positron AI raised $875M to advance its memory-first architecture, claiming 3.5 times greater power efficiency than Nvidia H100 GPUs. Lightmatter focuses on…
-
The risks of Tesla’s AI chip pivot and Dojo scaling
Tesla is shifting resources from its dedicated Dojo supercomputer team toward a single architecture for AI5 and AI6 processors. This transition occurs…
-

Groq LPU speed advantages for real-time finance
Groq LPU delivers 580 tokens per second for Llama 3.3 70B, significantly outperforming the 90 tokens per second from NVIDIA H100. This…
-

Cerebras WSE-3 vs SambaNova SN40L performance comparison
Cerebras runs Moonshot AI’s Kimi 2.6 trillion-parameter model at 981 tokens per second, outperforming the next-best GPU cloud provider by 6.7x. The…
-

Lambda Labs expands GPU cloud with $4 billion funding and Blackwell clusters
Lambda is raising up to $4 billion at a $14.5 billion valuation to deploy over 1 million GPUs by 2030. The company…
-
Lightmatter’s Passage platform challenges NVIDIA NVLink dominance
Lightmatter’s Passage platform utilizes 3D-stacked silicon photonics to deliver 114 Tbps aggregate bandwidth. This architecture bypasses copper bottlenecks using the Guide light…
-
AMD MI350X challenges Blackwell in training clusters
AMD’s Instinct MI355X delivers 1.3X higher inference throughput than the NVIDIA B200 on Llama 3.1 405B workloads. The new CDNA 4 architecture…
-
SambaNova RDU scaling and composition-of-experts
SambaNova’s SN40L RDU achieves 132 tokens per second for Llama 3.1 405B while consuming only 10KW per rack. This power-efficient architecture uses…
-
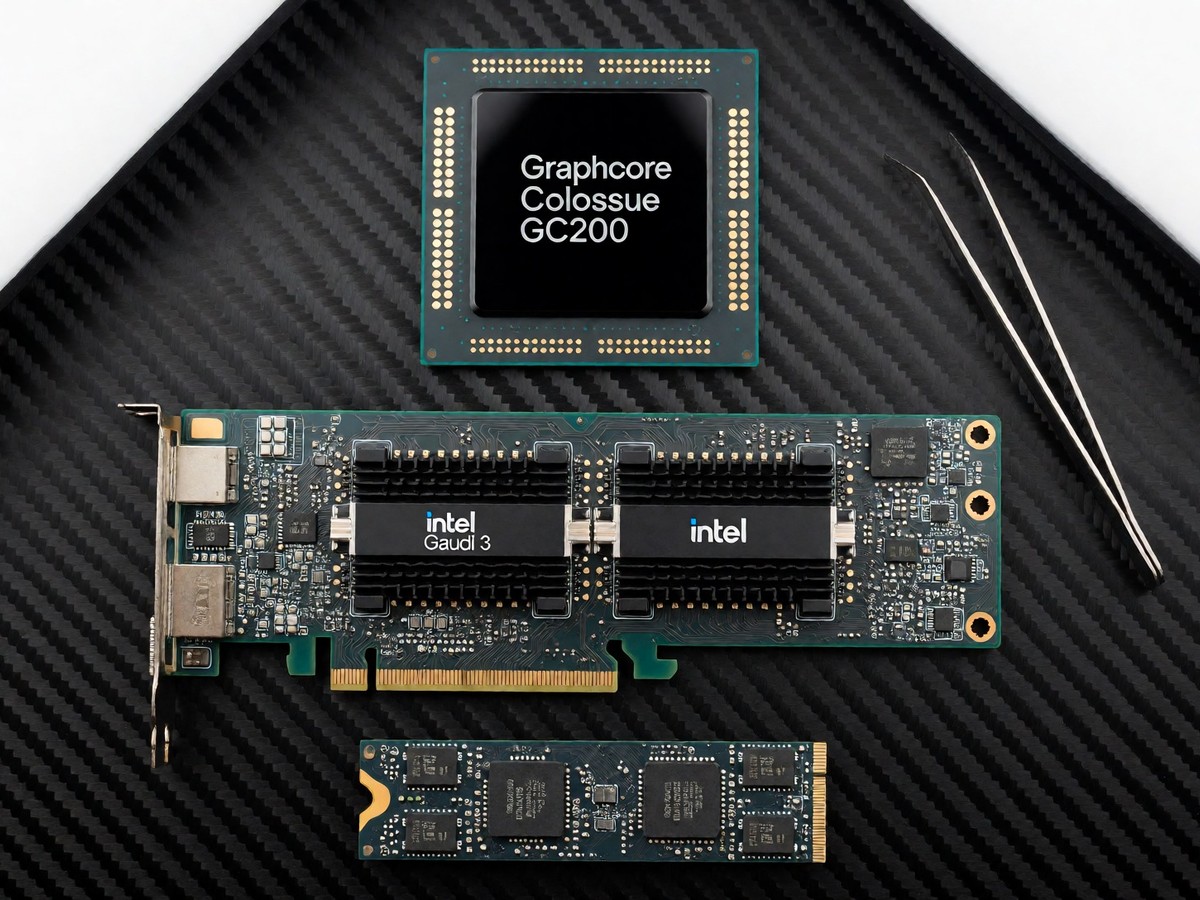
Graphcore IPU vs Intel Gaudi 3 and Nvidia performance
Graphcore CEO Nigel Toon claims the Colossus GC200 IPU outperforms GPUs on complex sparse models, while Intel’s Gaudi 2 showed a 103…