
inference
-
Deploying open-source LLMs with Tenstorrent Wormhole and TT-Metalium
Tenstorrent Wormhole n150 hardware and the TT-Metalium SDK enable efficient local LLM inference. The hardware features Tensix cores and GDDR6 memory, allowing…
-
The history of Google’s TPU v1 and the custom AI accelerator race
Google’s TPU v1 achieved 92 trillion 8-bit operations per second using a systolic array design. This specialized hardware powered the AlphaGo series…
-
Deploying Llama 3.2 90B Vision on Groq LPU for Real-Time Performance
Groq’s LPU architecture delivers 750 to 800 tokens per second for Llama 3 70B, significantly outperforming NVIDIA H100 clusters by eliminating memory-bandwidth…
-
Positron AI reaches $5 billion valuation with Asimov chip
Positron AI secured $875 million in Series C funding to advance its Asimov inference chip, which targets five times more tokens per…
-
The people shaping Groq’s $6.4B chip startup and TSA facial recognition
Groq secured $650 million in growth capital to expand its AI inference cloud following a major NVIDIA technology agreement. Meanwhile, the Privacy…
-
SambaNova reaches $11 billion valuation driven by inference demand
SambaNova Systems achieved an $11 billion post-money valuation following a $1 billion Series F round. The company is pivoting toward premium inference…
-
The chip architects behind Groq’s TSP architecture and NVIDIA’s challenge
Groq’s LPU architecture provides 80 TB/s of internal memory bandwidth to challenge NVIDIA’s dominance in AI inference. Founded by Jonathan Ross, the…
-
Deploying FuriosaAI RNGD for Korean Cloud Inference
FuriosaAI’s RNGD NPU delivers 2.25x better performance per watt for LLMs than GPU solutions. Samsung SDS hosts these accelerators at its Dongtan…
-
Positron Asimov vs Lightmatter Passage for data center inference
Positron’s Asimov silicon targets 5x more tokens per watt than Nvidia’s Rubin, while Lightmatter’s Passage platform provides up to 256 Tbps of…
-
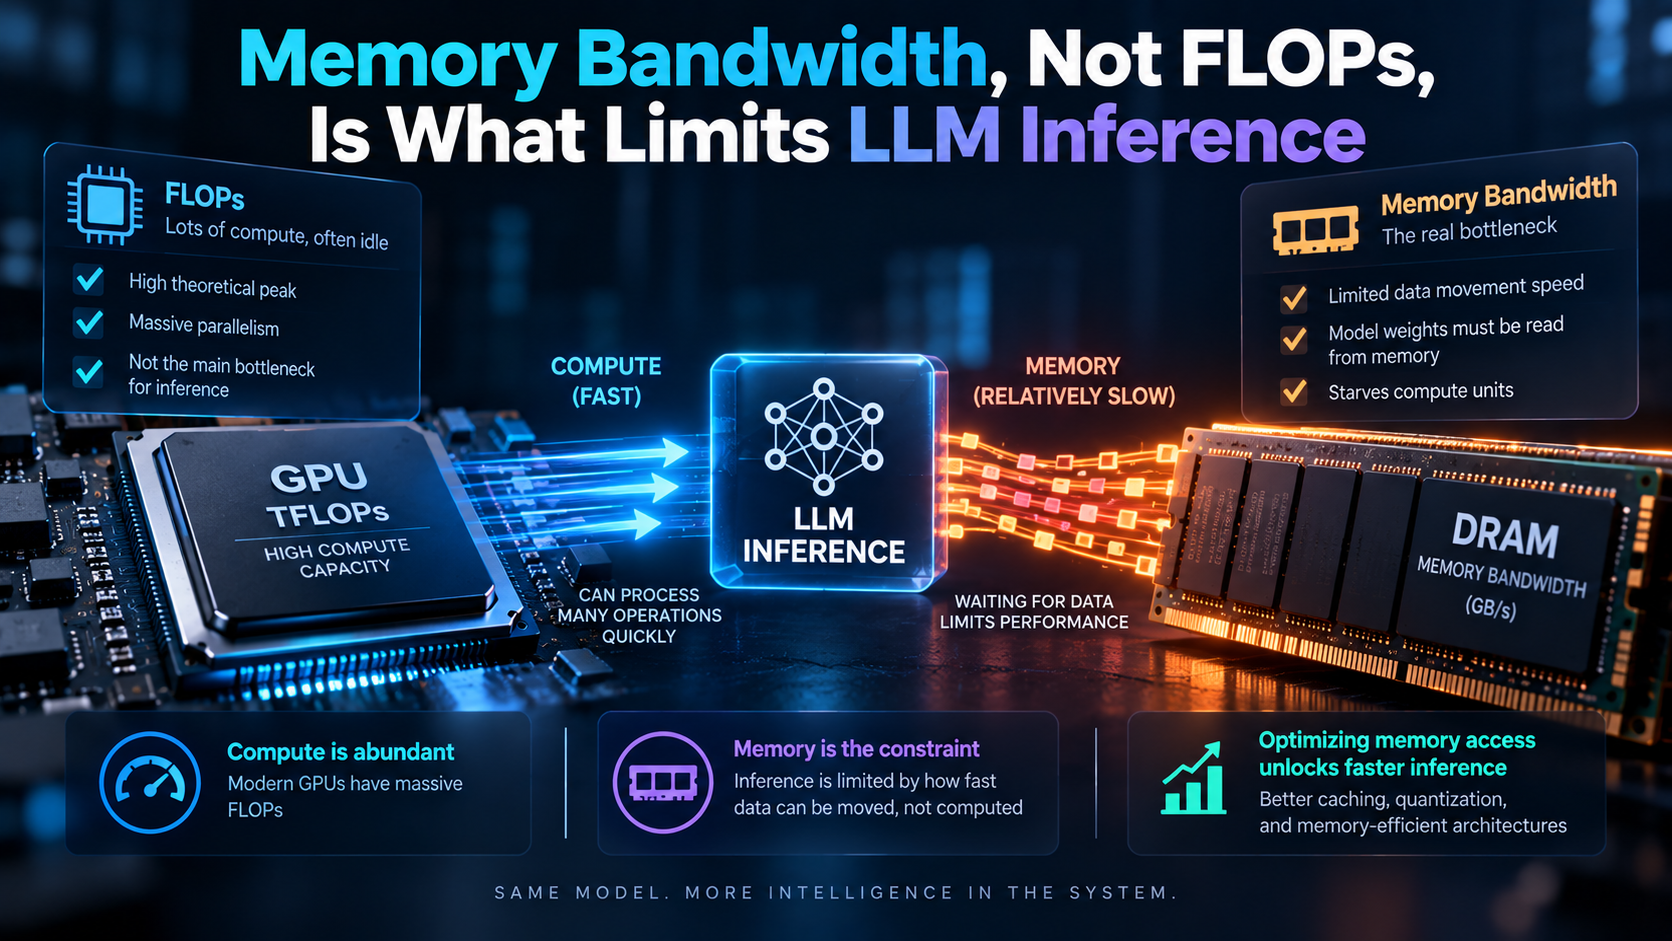
Memory Bandwidth, Not FLOPs, Is What Limits LLM Inference
Accelerators are sold on peak FLOPs, but token generation is bound by how fast weights move out of memory. What to actually…